📄 仓库 README
在 GitHub 查看 ↗ [](https://docs.xllm-ai.com/) [](https://quay.io/repository/jd_xllm/xllm-ai?tab=tags) [](https://opensource.org/licenses/Apache-2.0) [](https://arxiv.org/abs/2510.14686) [](https://deepwiki.com/xLLM-AI/xllm)
News
- 2026-08-27: 🎉 We day-0 support the GLM-5.3-Flash model, please refer to the Deployment Document for deployment.
- 2026-07-06: 🎉 xLLM is officially donated to the OpenAtom Foundation!
- 2026-06-13: 🎉 We day-0 support the MiniMax-M3 model, please refer to the Deployment Document for deployment.
More News
- 2026-04-24: 🎉 We day-0 support the [DeepSeek-V4](https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash) model, please refer to the [Deployment Document](https://github.com/xLLM-AI/xllm/blob/preview/deepseek-v4-mlu/testspace/run_deepseek_v4.sh) for deployment. - 2026-02-12: 🎉 We day-0 support high-performance inference for the [GLM-5](https://github.com/zai-org/GLM-5) model, please refer to the [Deployment Document](https://github.com/zai-org/GLM-5/blob/main/example/ascend.md) for deployment. - 2025-12-21: 🎉 We day-0 support high-performance inference for the [GLM-4.7](https://github.com/zai-org) model. - 2025-12-08: 🎉 We day-0 support high-performance inference for the [GLM-4.6V](https://github.com/zai-org/GLM-V) model. - 2025-12-05: 🎉 We now support high-performance inference for the [GLM-4.5/GLM-4.6](https://github.com/zai-org/GLM-4.5/blob/main/README_zh.md) series models. - 2025-12-05: 🎉 We now support high-performance inference for the [VLM-R1](https://github.com/om-ai-lab/VLM-R1) model. - 2025-12-05: 🎉 We build hybrid KV cache management based on [Mooncake](https://github.com/kvcache-ai/Mooncake), supporting global KV cache management with intelligent offloading and prefetching. - 2025-10-16: 🎉 We recently have released our [xLLM Technical Report](https://arxiv.org/abs/2510.14686) on arXiv, providing comprehensive technical blueprints and implementation insights.Overview
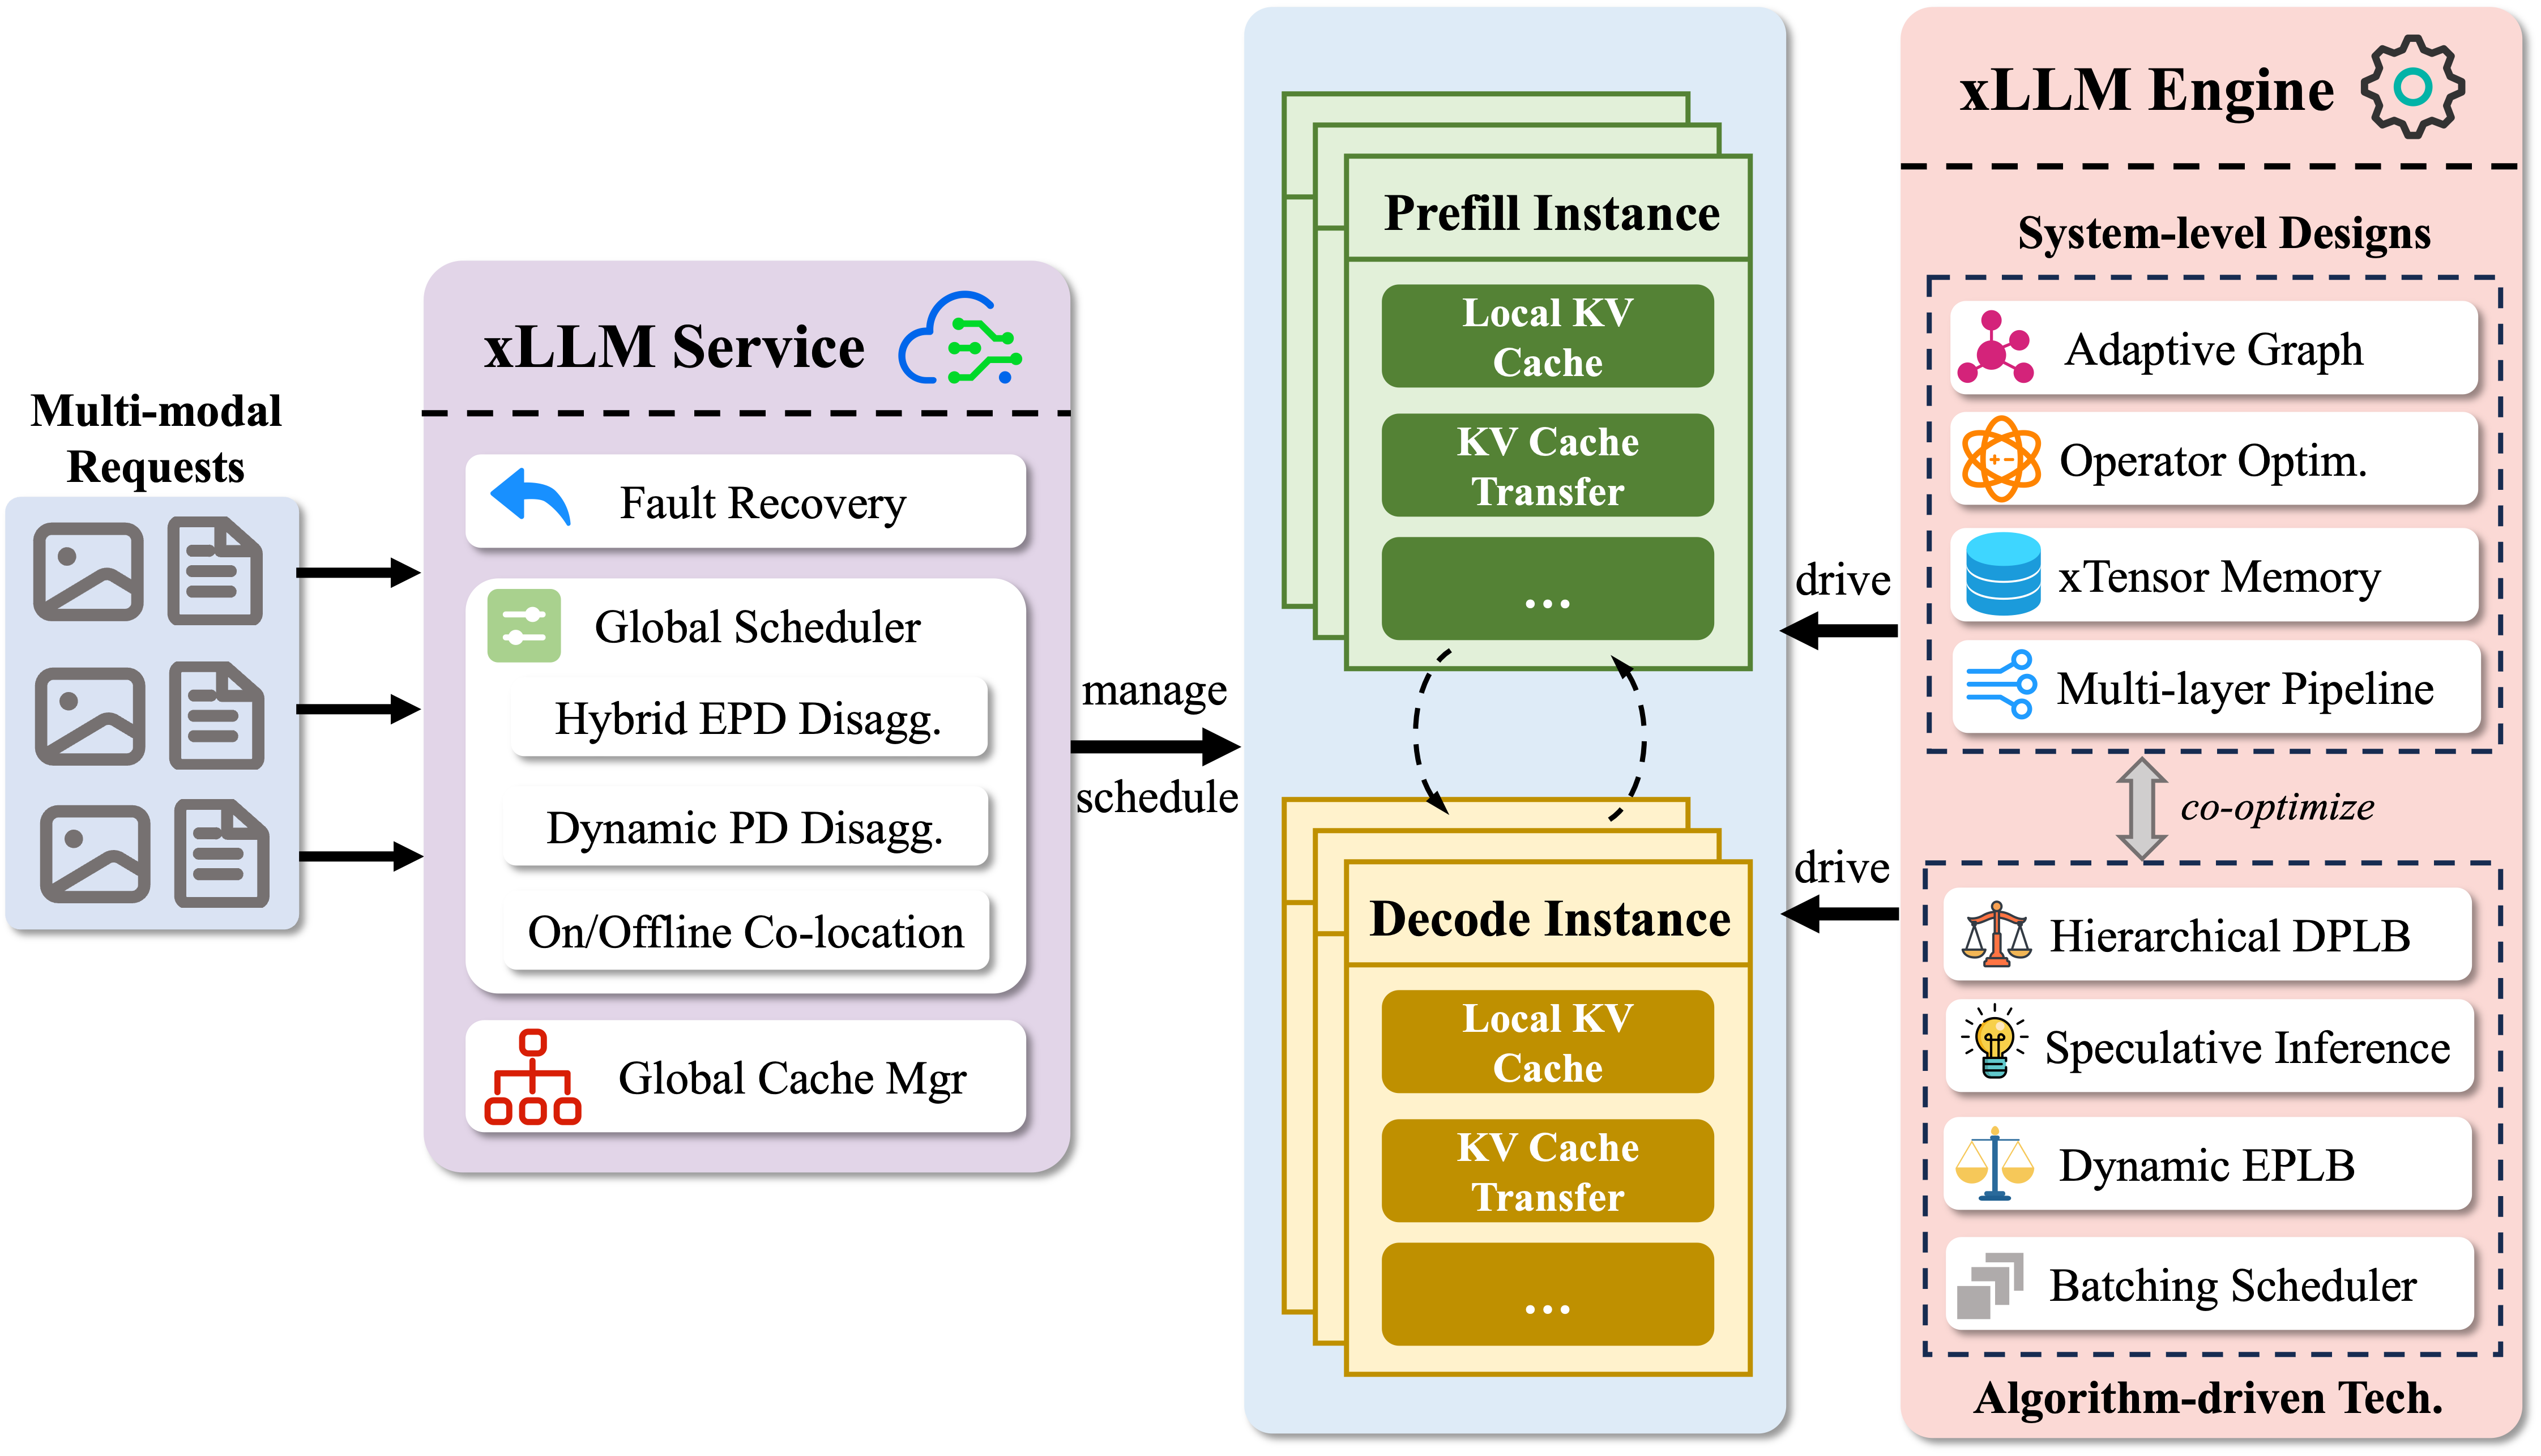
xLLM is an efficient LLM inference framework, specifically optimized for Chinese AI accelerators, enabling enterprise-grade deployment with enhanced efficiency and reduced cost.
Highlights
- Top-tier Performance: Delivers high-throughput, low-latency inference through many advanced features.
- Mainstream Hardware Support: Purpose-built and deeply optimized for Chinese AI accelerators.
- Service-Engine Decoupled Architecture: Service layer handles scheduling and availability; engine layer handles computation.
- Enterprise-grade Deployment: Battle-tested at scale across JD.com's core retail business.
Hardware Support
| Hardware | Abbreviation | Example | Remark |
|---|---|---|---|
| Ascend NPU | NPU | A2, A3 | HDK Driver 25.2.0 + |
| Cambricon MLU | MLU | MLU | |
| Moore Threads GPU | MUSA | S5000 | |
| Hygon DCU | DCU | BW1000 | |
| MetaX MACA | MACA | MXC500 | |
| Iluvatar CoreX GPU | ILU | BI150 |
Getting Started
Community & Support
Acknowledgment
This project was made possible thanks to the following open-source projects:
- ScaleLLM - xLLM draws inspiration from ScaleLLM's graph construction method and references its runtime execution.
- Mooncake - Build xLLM hybrid KV cache management based on Mooncake.
- brpc - Build high-performance http service based on brpc.
- tokenizers-cpp - Build C++ tokenizer based on tokenizers-cpp.
- safetensors - xLLM relies on the C binding safetensors capability.
- Partial JSON Parser - Implement xLLM's C++ JSON parser with insights from Python and Go implementations.
- concurrentqueue - A fast multi-producer, multi-consumer lock-free concurrent queue for C++11.
Thanks to the following collaborating university laboratories:
- THU-MIG (School of Software, BNRist, Tsinghua University)
- USTC-Cloudlab (Cloud Computing Lab, University of Science and Technology of China)
- Beihang-HiPO (Beihang HiPO research group)
- PKU-DS-LAB (Data Structure Laboratory, Peking University)
- PKU-NetSys-LAB (NetSys Lab, Peking University)
- TJU-TANKLab (TANK Lab, Tianjin University)
Thanks to all the following developers who have contributed to xLLM.
Citation
If you think this repository is helpful to you, welcome to cite us:
@article{liu2025xllm,
  title={xLLM Technical Report},
  author={xLLM team},
  journal={arXiv preprint arXiv:2510.14686},
  year={2025}
}
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|