📄 仓库 README
在 GitHub 查看 ↗
Contents
- Why this exists
- Supported providers
- Compatible CLIs & coding agents
- How it compares
- Features
- Quick start
- Desktop app
- Works with OpenAI-compatible clients
- Languages
- Premium (live catalog)
- Using the API
- Screenshots
- How it works
- FAQ
- Limitations
- Contributing
- Disclaimer
Guides: Install & deploy · API reference · Clients & coding agents · Prompt compression · Architecture & internals · Documentation index · Contributor guide
Why this exists
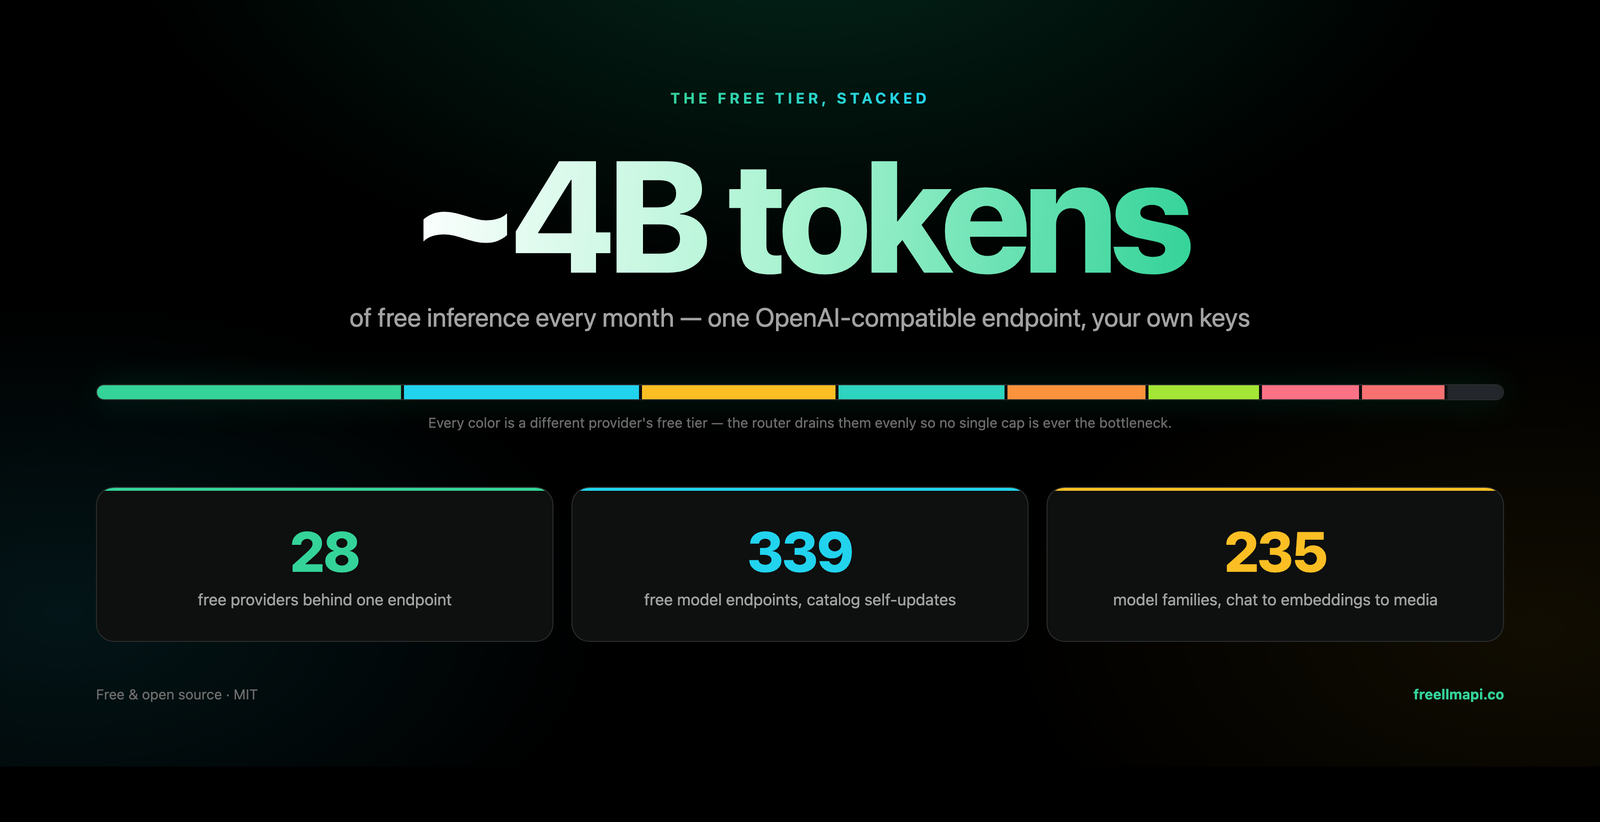
Every serious AI lab now offers a free tier, a few million tokens a month, a few thousand requests a day. On its own each tier is a toy. Stacked together, they add up to roughly 7.4 billion tokens per month of working inference capacity, across 474 model families / 635 provider endpoints from small-and-fast to reasonably capable.
The problem is that stacking them by hand is painful: thirty-four different SDKs, thirty-four different rate limits, thirty-four places a request can fail. FreeLLMAPI collapses that into one OpenAI-compatible endpoint. Point any OpenAI client library at your local server, and it routes transparently across whichever providers you've added keys for.
And the free-tier landscape shifts weekly: providers launch models, retire them, and change quotas without notice. FreeLLMAPI tracks all of that for you. The router pulls a signed model catalog from freellmapi.co on its own, so your install keeps up without a git pull. See Premium (live catalog) for how fast it keeps up.
Supported providers
 |
 Groq |
 Cerebras |
 OpenCode Zen |
 Mistral |
 OpenRouter |
 Cloudflare |
 Cohere |
 Z.ai (Zhipu) |
 NVIDIA |
 HuggingFace |
|
| ModelScope Qwen3 · DeepSeek V4 · GLM-5 (needs Aliyun cn binding) |
Plus a custom provider — point chat, embedding, image, or audio models at any OpenAI-compatible endpoint (llama.cpp, LM Studio, vLLM, a local Ollama, or a remote gateway) from the Keys page.
The full, always-current list lives at freellmapi.co/models with per-model rate limits, context windows, and free-token budgets.
Compatible CLIs & coding agents
 Claude Code |
 Codex CLI |
 Gemini CLI |
 Cursor |
 Cline |
 Roo Code |
 OpenCode |
 Aider |
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|