📄 仓库 README
在 GitHub 查看 ↗This repository is archived. Development and support have ended.
The code remains available for reference under the terms of the LICENSE. No updates, bug fixes, security patches, or support will be provided, and issues and pull requests are no longer monitored. The software is provided "AS IS" as set forth in the license, without any warranty or ongoing responsibility of the original authors.
Archive locations
The source code is preserved under the supertone-oss-archive GitHub organization.
Model downloads now use the supertone-oss-archive Hugging Face namespace:
See Quick Start to download the archived models and run locally. Code and model weights retain their respective licenses. This archive does not include hosted demos or Voice Builder services.
Supertonic — Lightning Fast, On-Device, Accurate TTS
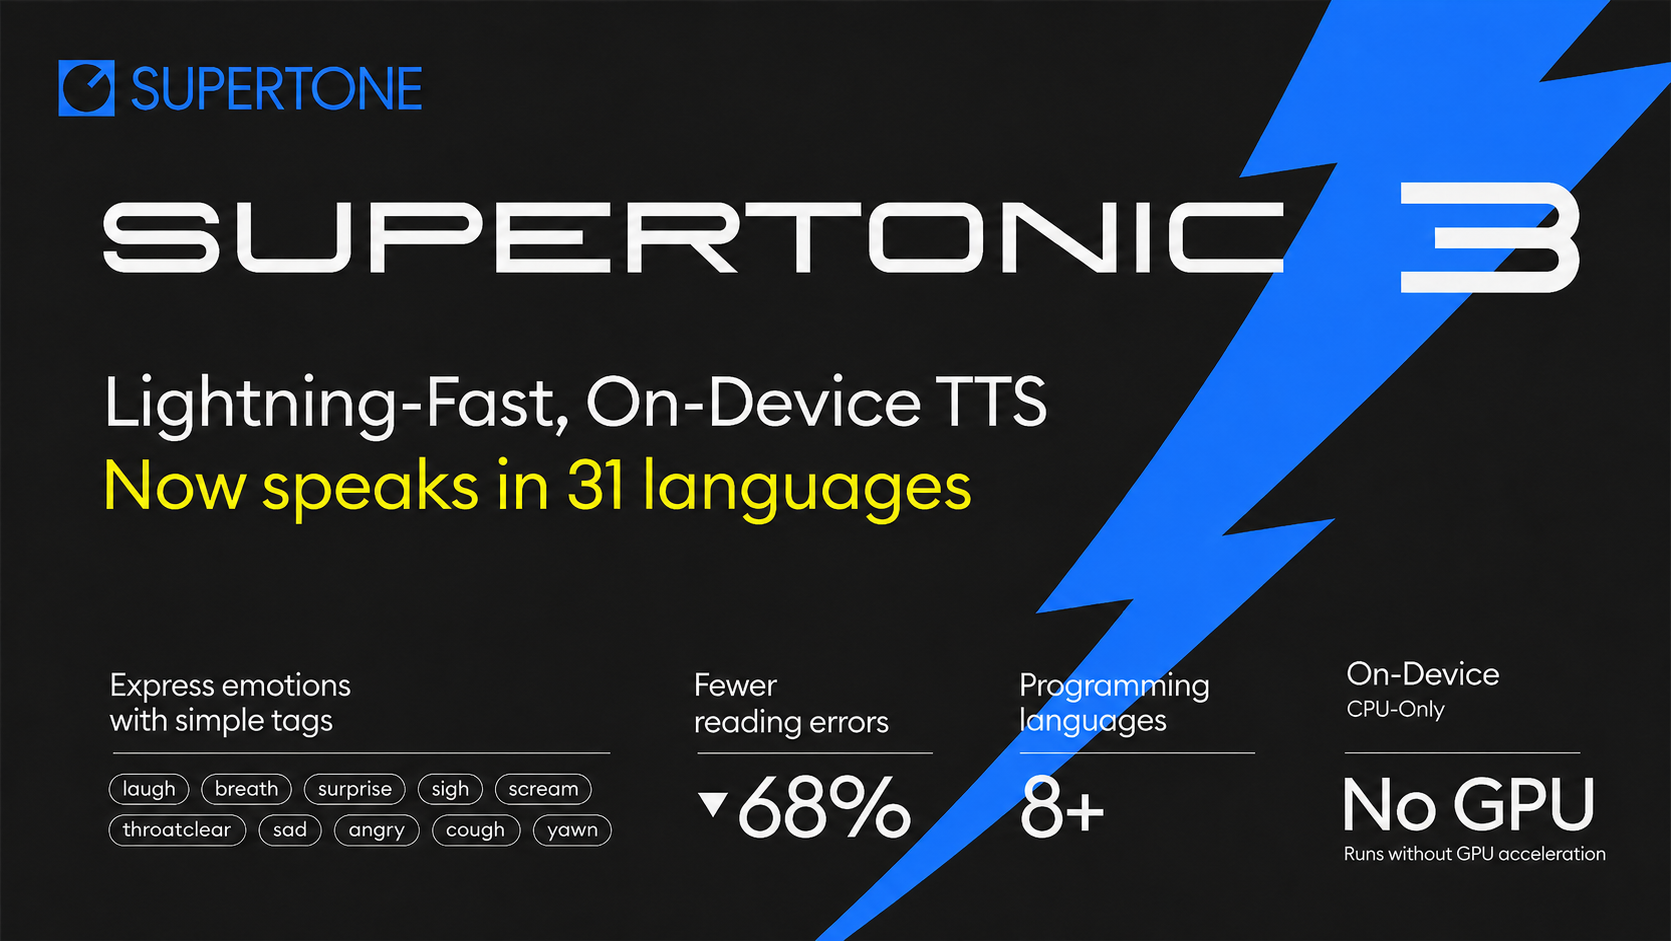

Supertonic is a lightning-fast, on-device multilingual text-to-speech system designed for local inference with minimal overhead. Powered by ONNX Runtime, it runs entirely on your device—no cloud, no API calls, no privacy concerns.
✨ Highlights
- ⚡ Blazingly Fast — Low-latency, real-time synthesis across desktop, browser, mobile, and edge — fast enough to turn an entire webpage into audio in under a second
- 🌍 31-Language Multilingual — Synthesize directly from text across 31 languages, or pass
lang="na"to let Supertonic process the text language-agnostically when you don't know the input language — no separate language adapters needed - 🪶 99M-Parameter Open-Weight Model — A compact, fully open-weight checkpoint — a fraction of the size of 0.7B–2B class open TTS systems — for smaller downloads, faster cold starts, and lower memory footprint
- 📱 Edge-Device Ready — Runs locally on desktop, mobile, browsers, and resource-constrained hardware like Raspberry Pi or e-readers, with zero network dependency, complete privacy, and no GPU required
- 🔊 44.1kHz High-Quality Audio — Outputs studio-grade 44.1kHz 16-bit WAV directly, ready for production playback without any external upsampler
- 🎭 Expression Tags — 10 inline tags (e.g.
<laugh>,<breath>,<sigh>) bring natural human nuance into generated speech without prompt engineering or reference audio - 🛠️ Multi-Runtime SDKs — Ready-to-use examples through ONNX Runtime across Python, Node.js, Browser (WebGPU), Java, C++, C#, Go, Swift, iOS, Rust, and Flutter
🌍 Supported Languages (31)
Arabic (ar), Bulgarian (bg), Croatian (hr), Czech (cs), Danish (da), Dutch (nl), English (en), Estonian (et), Finnish (fi), French (fr), German (de), Greek (el), Hindi (hi), Hungarian (hu), Indonesian (id), Italian (it), Japanese (ja), Korean (ko), Latvian (lv), Lithuanian (lt), Polish (pl), Portuguese (pt), Romanian (ro), Russian (ru), Slovak (sk), Slovenian (sl), Spanish (es), Swedish (sv), Turkish (tr), Ukrainian (uk), Vietnamese (vi)
Not sure which language your text is in? Pass
lang="na"and Supertonic will handle the input in a language-agnostic way — no explicit language tag required.
Historical release notes
These entries describe past releases. Hosted services and support offers mentioned here are no longer provided by this archive. Follow the [archive setup guide](https://github.com/supertone-inc/supertonic/blob/HEAD/README.md#quick-start). - **2026.05.20** - **Supertonic 3** is now officially supported in **[Supertone Play](https://play.supertone.ai/)** and the **[Supertone API](https://www.supertone.ai/ko/api)**. Visit Play or the API if you want a managed content creation workflow with diverse preset voices and zero-shot voice cloning. - **2026.05.18** - Python SDK v1.3.1 adds **`supertonic serve`**, a local HTTP server with native `/v1/tts` and OpenAI-compatible `/v1/audio/speech` endpoints. See the [serve documentation](https://github.com/supertone-oss-archive/supertonic-py/blob/main/docs/cli/serve.md). - **2026.05.18** - **[Voice Builder](https://supertonic.supertone.ai/voice-builder)** now supports **Supertonic 3**. Create a permanent custom voice profile for Supertonic and download version-specific JSON files for both Supertonic 2 and Supertonic 3. If you already created a Supertonic 2 voice, the matching Supertonic 3 JSON is now available from [My Page](https://supertonic.supertone.ai/my-page). - **2026.04.29** - 🎉 **Supertonic 3** released with **31-language support**, improved reading accuracy, fewer repeat/skip failures, and v2-compatible public ONNX assets. [Demo](https://huggingface.co/spaces/Supertone/supertonic-3) | [Models](https://huggingface.co/supertone-oss-archive/supertonic-3) - **2026.01.22** - **[Voice Builder](https://supertonic.supertone.ai/voice-builder)** is now live! Turn your voice into a deployable, edge-native TTS with permanent ownership. - **2026.01.06** - 🎉 **Supertonic 2** released with 5-language support. The v2 code path is preserved on the [`release/supertonic-2`](https://github.com/supertone-oss-archive/supertonic/tree/release/supertonic-2) branch. - **2025.12.10** - Added `supertonic` PyPI package! Install via `pip install supertonic`. For details, visit [supertonic-py documentation](https://github.com/supertone-oss-archive/supertonic-py/blob/main/docs/index.md) - **2025.12.10** - Added [6 new voice styles](https://huggingface.co/supertone-oss-archive/supertonic/tree/c6ad29bec69c380356a0cc393c75dc84a6b37e71/voice_styles) (M3, M4, M5, F3, F4, F5). See [Voices](https://github.com/supertone-oss-archive/supertonic-py/blob/main/docs/voices.md) for details - **2025.12.08** - Optimized ONNX models via [OnnxSlim](https://github.com/inisis/OnnxSlim) now available on [Hugging Face Models](https://huggingface.co/supertone-oss-archive/supertonic) - **2025.11.24** - Added Flutter SDK support with macOS compatibilityQuick Start
Use the examples in this repository with model files downloaded explicitly from the archive. No Hugging Face login, hosted demo, or original Supertone service is required. These instructions use Supertonic 3.
1. Clone the source and install the download tool
Use Python 3.11 in a virtual environment:
git clone https://github.com/supertone-oss-archive/supertonic.git
cd supertonic
python3.11 -m venv .venv
source .venv/bin/activate
python -m pip install huggingface_hub
On Windows, activate the environment with .venv\Scripts\Activate.ps1 in PowerShell.
2. Download the archived model
hf download supertone-oss-archive/supertonic-3 \
  --revision aafc6e32416a594460b32413efc49d7fe4ce6d46 \
  --local-dir assets
This downloads the ONNX models, configuration, and preset voice styles to assets/.
The revision pins the archived snapshot. Git LFS is not needed for this download method.
See Models & Versions for the archived Supertonic 1 and 2 weights.
3. Generate speech locally
python -m pip install -r py/requirements.txt
cd py
python example_onnx.py --n-test 1 --text "This speech was generated locally with the archived Supertonic model." --lang en
The generated WAV file is saved in py/results/. After dependencies and models
have been downloaded, this example performs inference locally without a network connection.
See Python examples for voice selection, batch synthesis, and other options.
Optional Python SDK
Older releases of the supertonic Python package may still use the original
Supertone Hugging Face namespace for automatic downloads. Download assets/
as above and pass model_dir with auto_download=False instead.
To use the preserved SDK source with Supertonic 3 support, run these commands from the repository root in the same virtual environment:
python -m pip install "git+https://github.com/supertone-oss-archive/supertonic-py.git@df0f9686dac7fbbde391b759e2ee5286a3737622"
python py/example_pypi.py
The SDK example uses the local assets/ directory and does not download models.
The archived local server guide
is available for reference; the ONNX example above is the default archive setup.
Getting Started in Other Runtimes
Download the same assets/ directory from the repository root before running
the examples below. The language examples read these local files.
Some language examples need native runtimes:
- Go: install the ONNX Runtime C library. On macOS, brew install onnxruntime.
- Java: use a JDK, not just a JRE. On macOS, brew install openjdk@17.
- C#: targets .NET 9 and allows major-version roll-forward.
Other Runtime Examples
Run Supertonic in other languages and platforms
**Node.js Example** ([Details](https://github.com/supertone-inc/supertonic/blob/HEAD/nodejs/))cd nodejs
npm install
npm start
cd web
npm install
npm run dev
cd java
mvn clean install
mvn exec:java
cd cpp
mkdir build && cd build
cmake .. && cmake --build . --config Release
./example_onnx
cd csharp
dotnet restore
dotnet run
cd go
go mod download
go run example_onnx.go helper.go
cd swift
swift build -c release
.build/release/example_onnx
cd rust
cargo build --release
./target/release/example_onnx
cd ios/ExampleiOSApp
xcodegen generate
open ExampleiOSApp.xcodeproj
Technical Details
- Runtime: ONNX Runtime for cross-platform inference
- Browser Support: onnxruntime-web for client-side inference
- Batch Processing: Supports batch inference for improved throughput
- Audio Output: Outputs 44.1kHz 16-bit WAV files
Performance Highlights
Supertonic 3 is designed for practical on-device inference: compact enough to run locally, while staying competitive with much larger open TTS systems.
Reading Accuracy
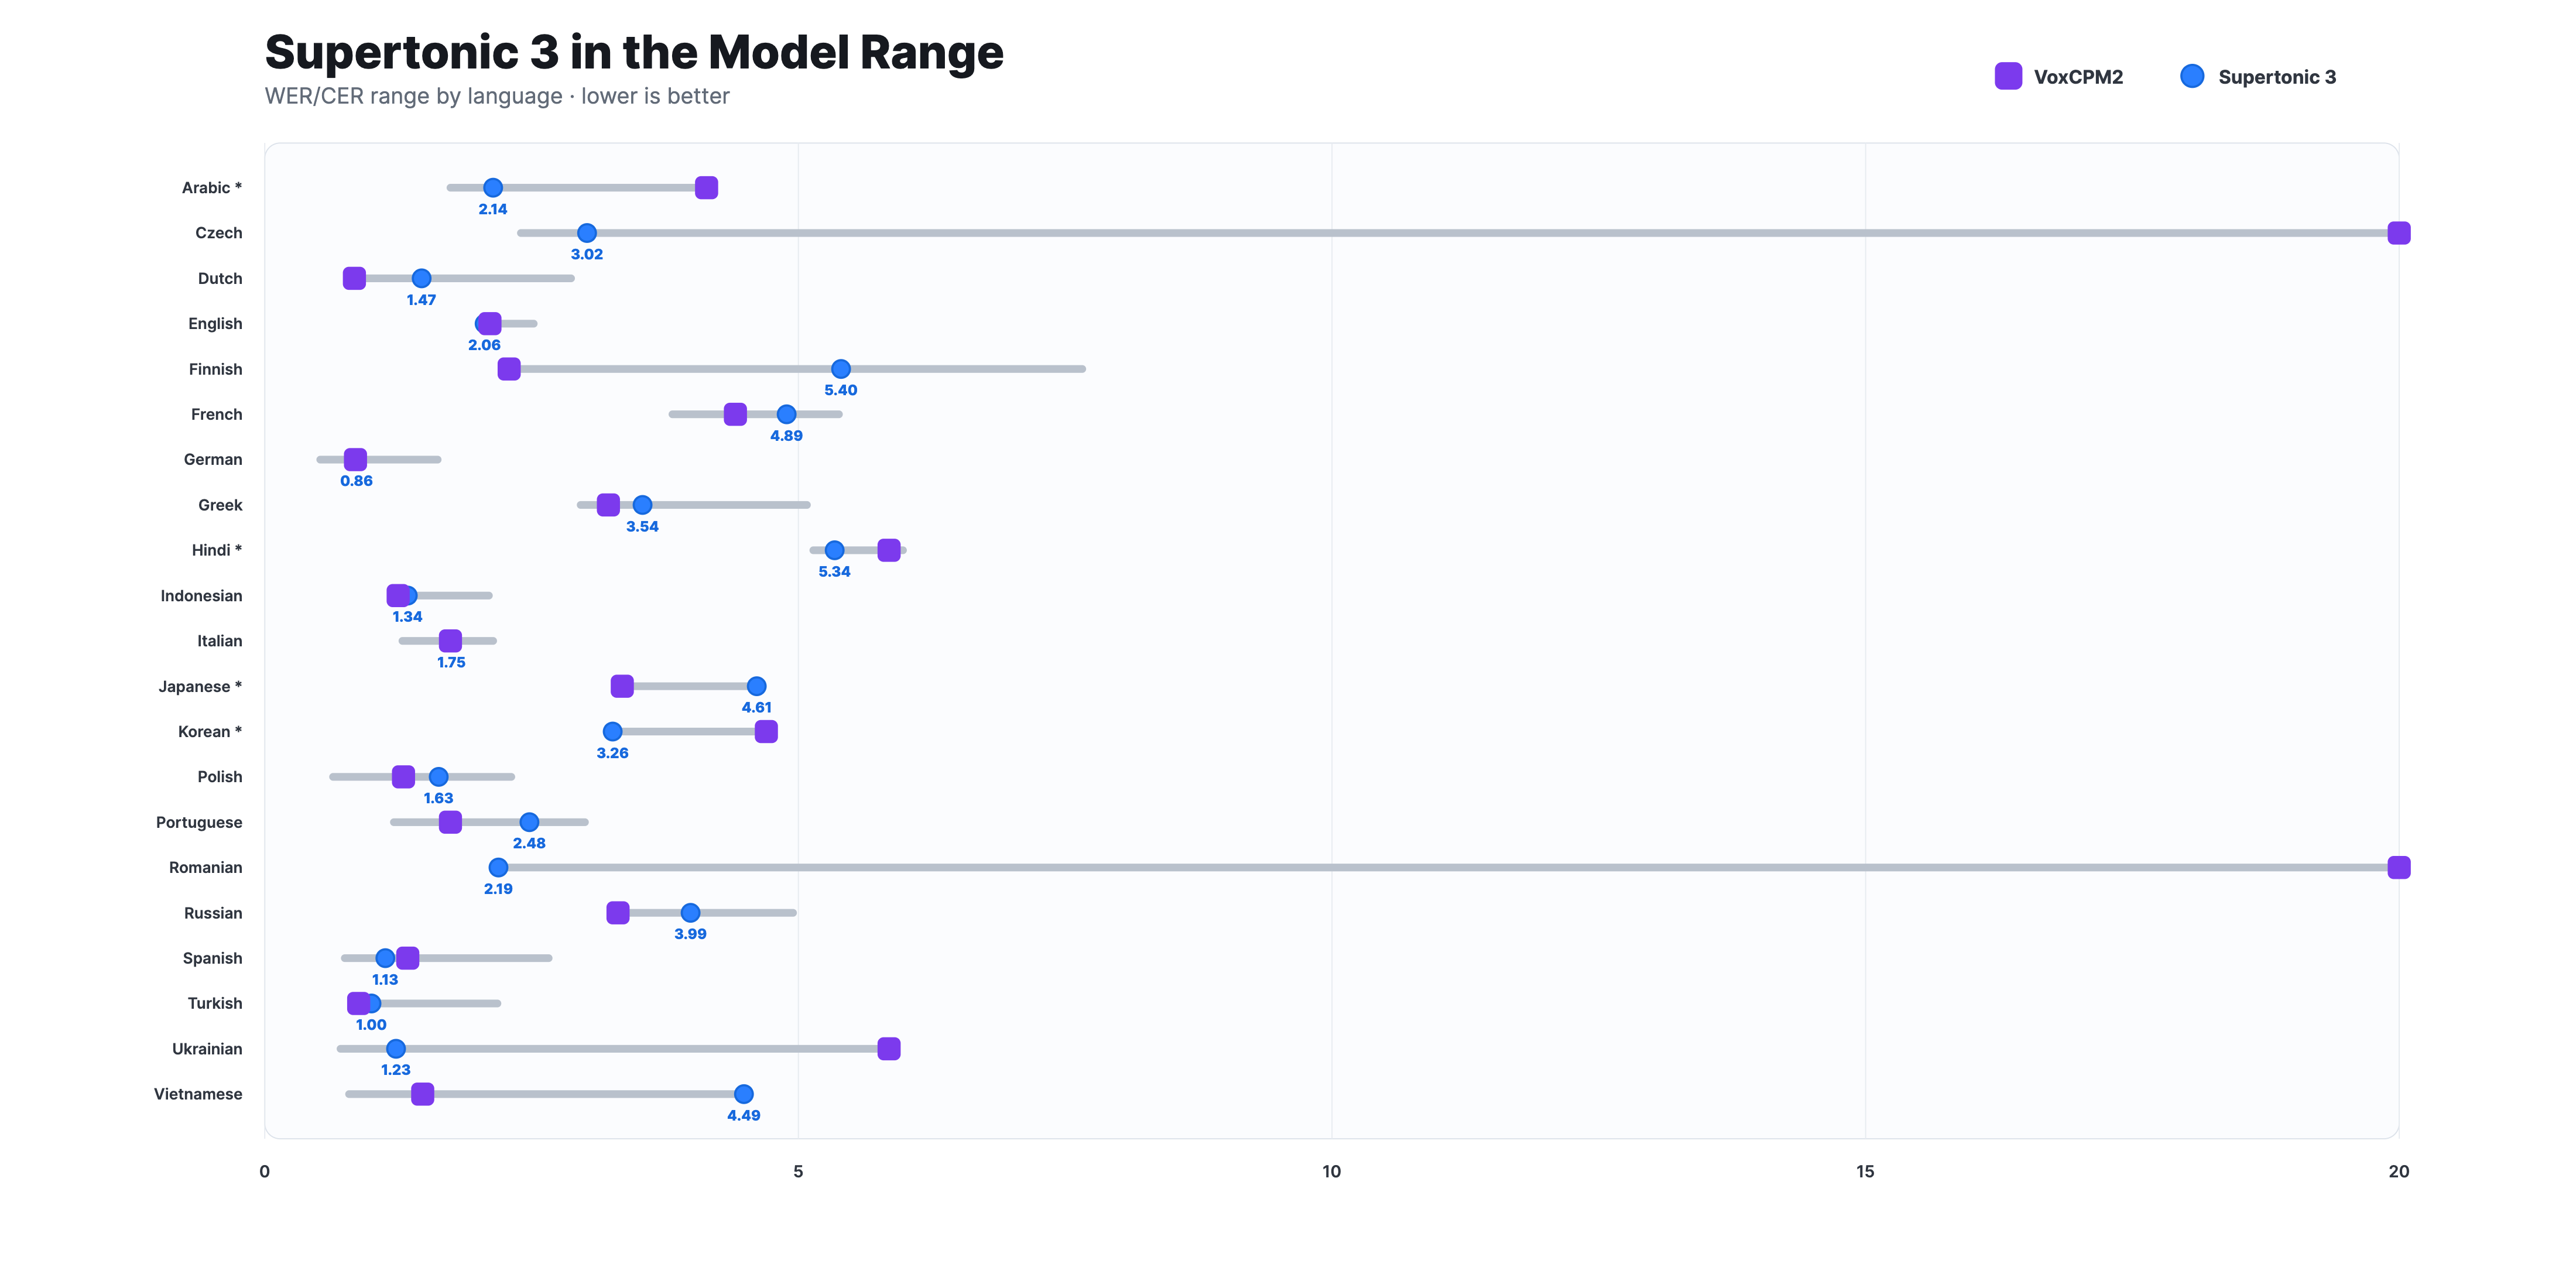
Evaluated on the Minimax-MLS-test benchmark, Supertonic 3 stays within a competitive WER/CER range against much larger open TTS models such as VoxCPM2, while preserving a lightweight on-device deployment path. Asterisked languages (*) use CER; the others use WER.
📊 Detailed per-language results (WER / CER*)
| Lang | VoxCPM2 | OmniVoice | Qwen3-TTS | Supertonic 2 | **Supertonic 3** | |---|:---:|:---:|:---:|:---:|:---:| | arabic\* | 4.14 | 1.74 | — | — | **2.14** | | czech | 23.73 | 2.40 | — | — | **3.02** | | dutch | 0.84 | 0.77 | — | — | **1.47** | | english | 2.11 | 2.02 | 2.25 | 2.52 | **2.06** | | finnish | 2.29 | 3.94 | — | — | **5.40** | | french | 4.41 | 4.74 | 3.82 | 5.09 | **4.89** | | german | 0.85 | 0.96 | 0.52 | — | **0.86** | | greek | 3.22 | 2.96 | — | — | **3.54** | | hindi\* | 5.85 | 5.14 | — | — | **5.34** | | indonesian | 1.25 | 1.67 | — | — | **1.34** | | italian | 1.74 | 1.29 | 1.40 | — | **1.75** | | japanese\* | 3.35 | 3.81 | 3.67 | — | **4.61** | | korean\* | 4.70 | 3.22 | 4.07 | 3.65 | **3.26** | | polish | 1.30 | 0.64 | — | — | **1.63** | | portuguese | 1.74 | 1.40 | 1.21 | 1.52 | **2.48** | | romanian | 22.39 | 2.29 | — | — | **2.19** | | russian | 3.31 | 4.53 | 4.48 | — | **3.99** | | spanish | 1.34 | 0.99 | 0.75 | 1.81 | **1.13** | | turkish | 0.88 | 2.18 | — | — | **1.00** | | ukrainian | 5.85 | 0.71 | — | — | **1.23** | | vietnamese | 1.48 | 0.79 | — | — | **4.49** | > Lower is better. `*` indicates CER (character error rate); all other rows use WER (word error rate). Dashes (`—`) indicate the model does not officially support the language or no result is available.
Supertonic 2 to Supertonic 3
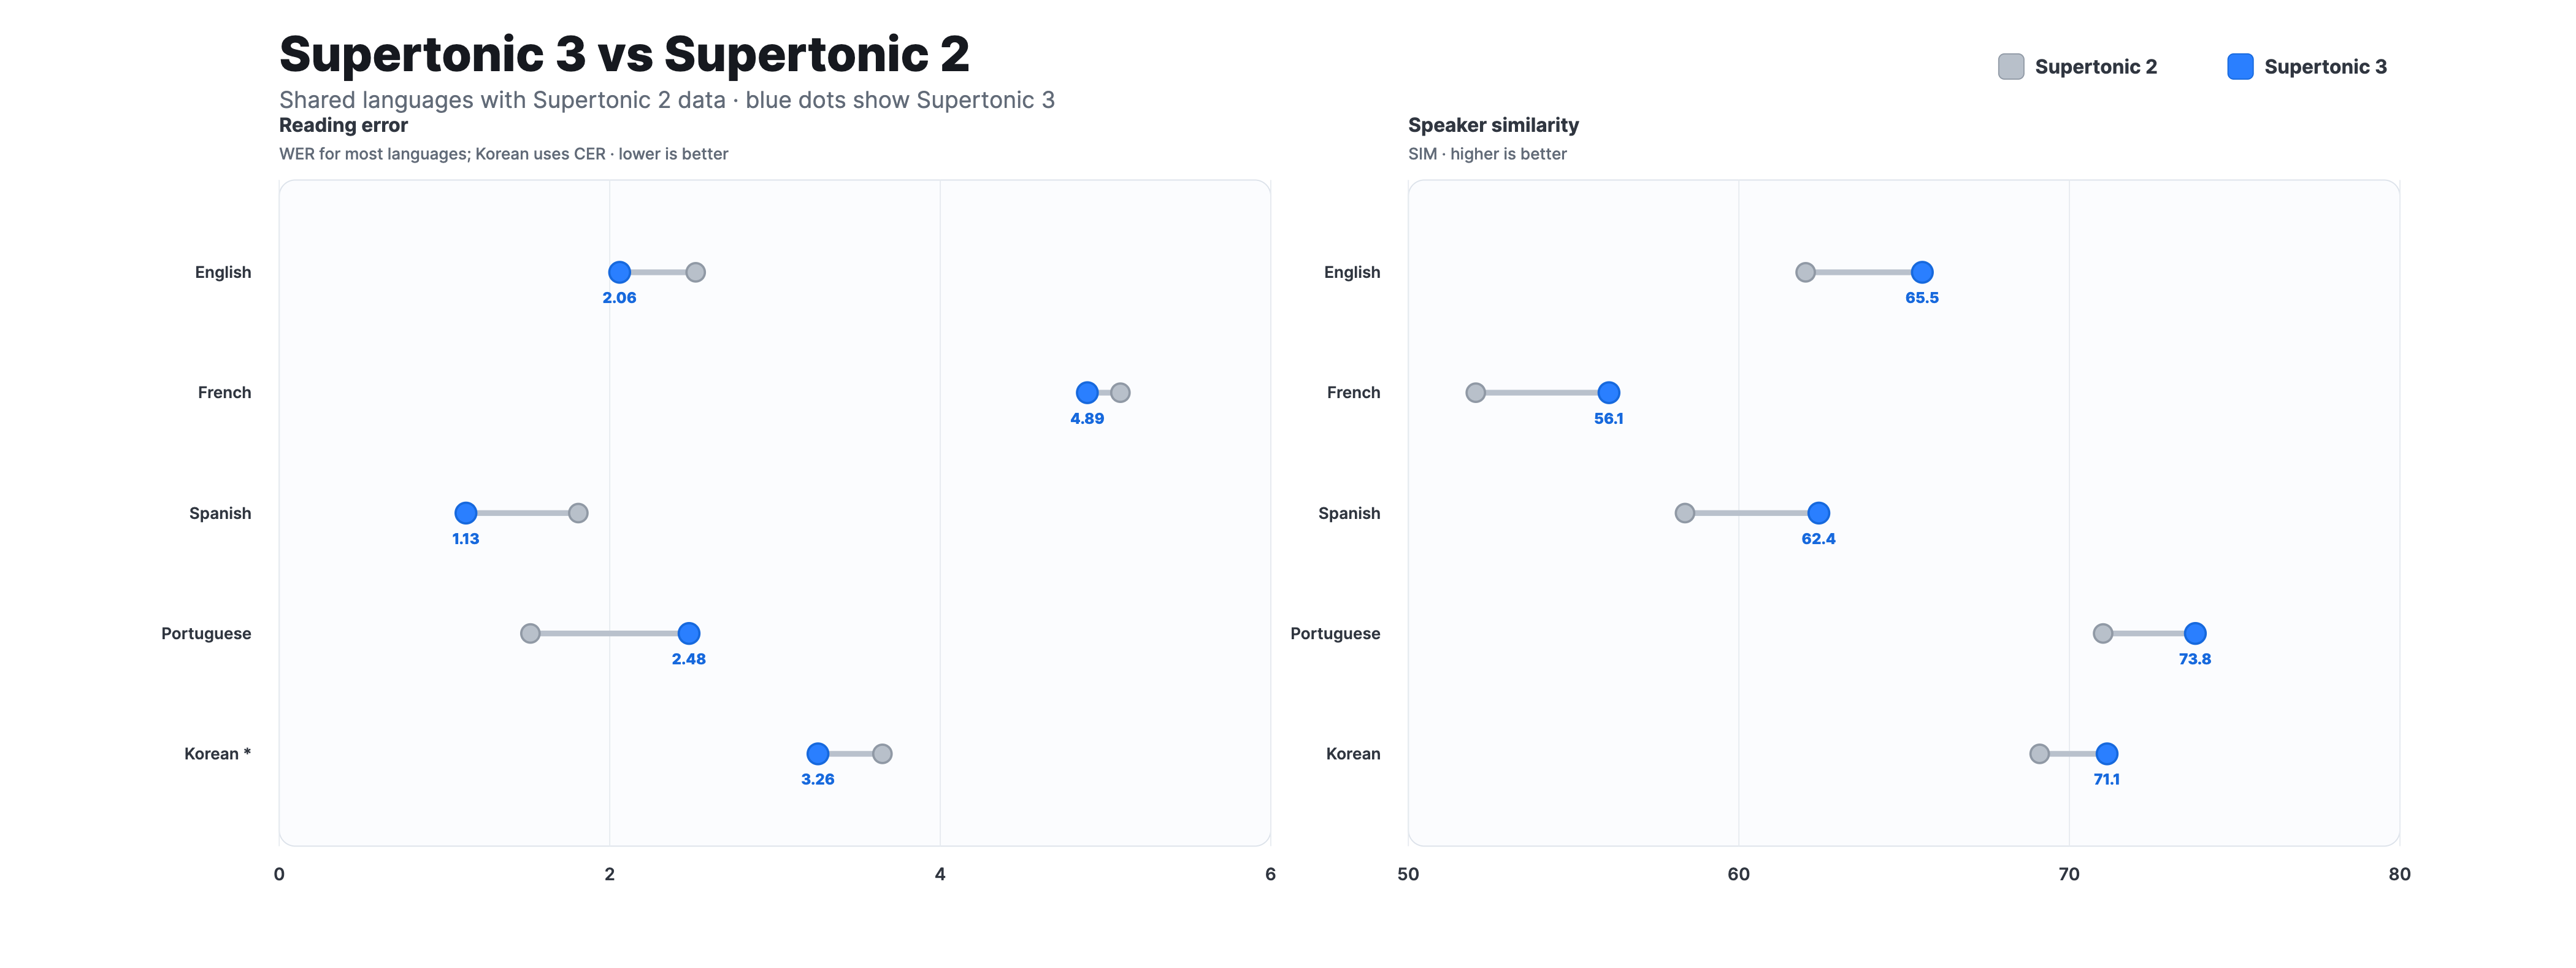
Compared with Supertonic 2, Supertonic 3 reduces repeat and skip failures, improves speaker similarity across the shared-language set, and expands language coverage from 5 to 31 languages. It keeps the v2-compatible public ONNX interface, so existing integrations can move to v3 with the same inference contract.
Runtime Footprint
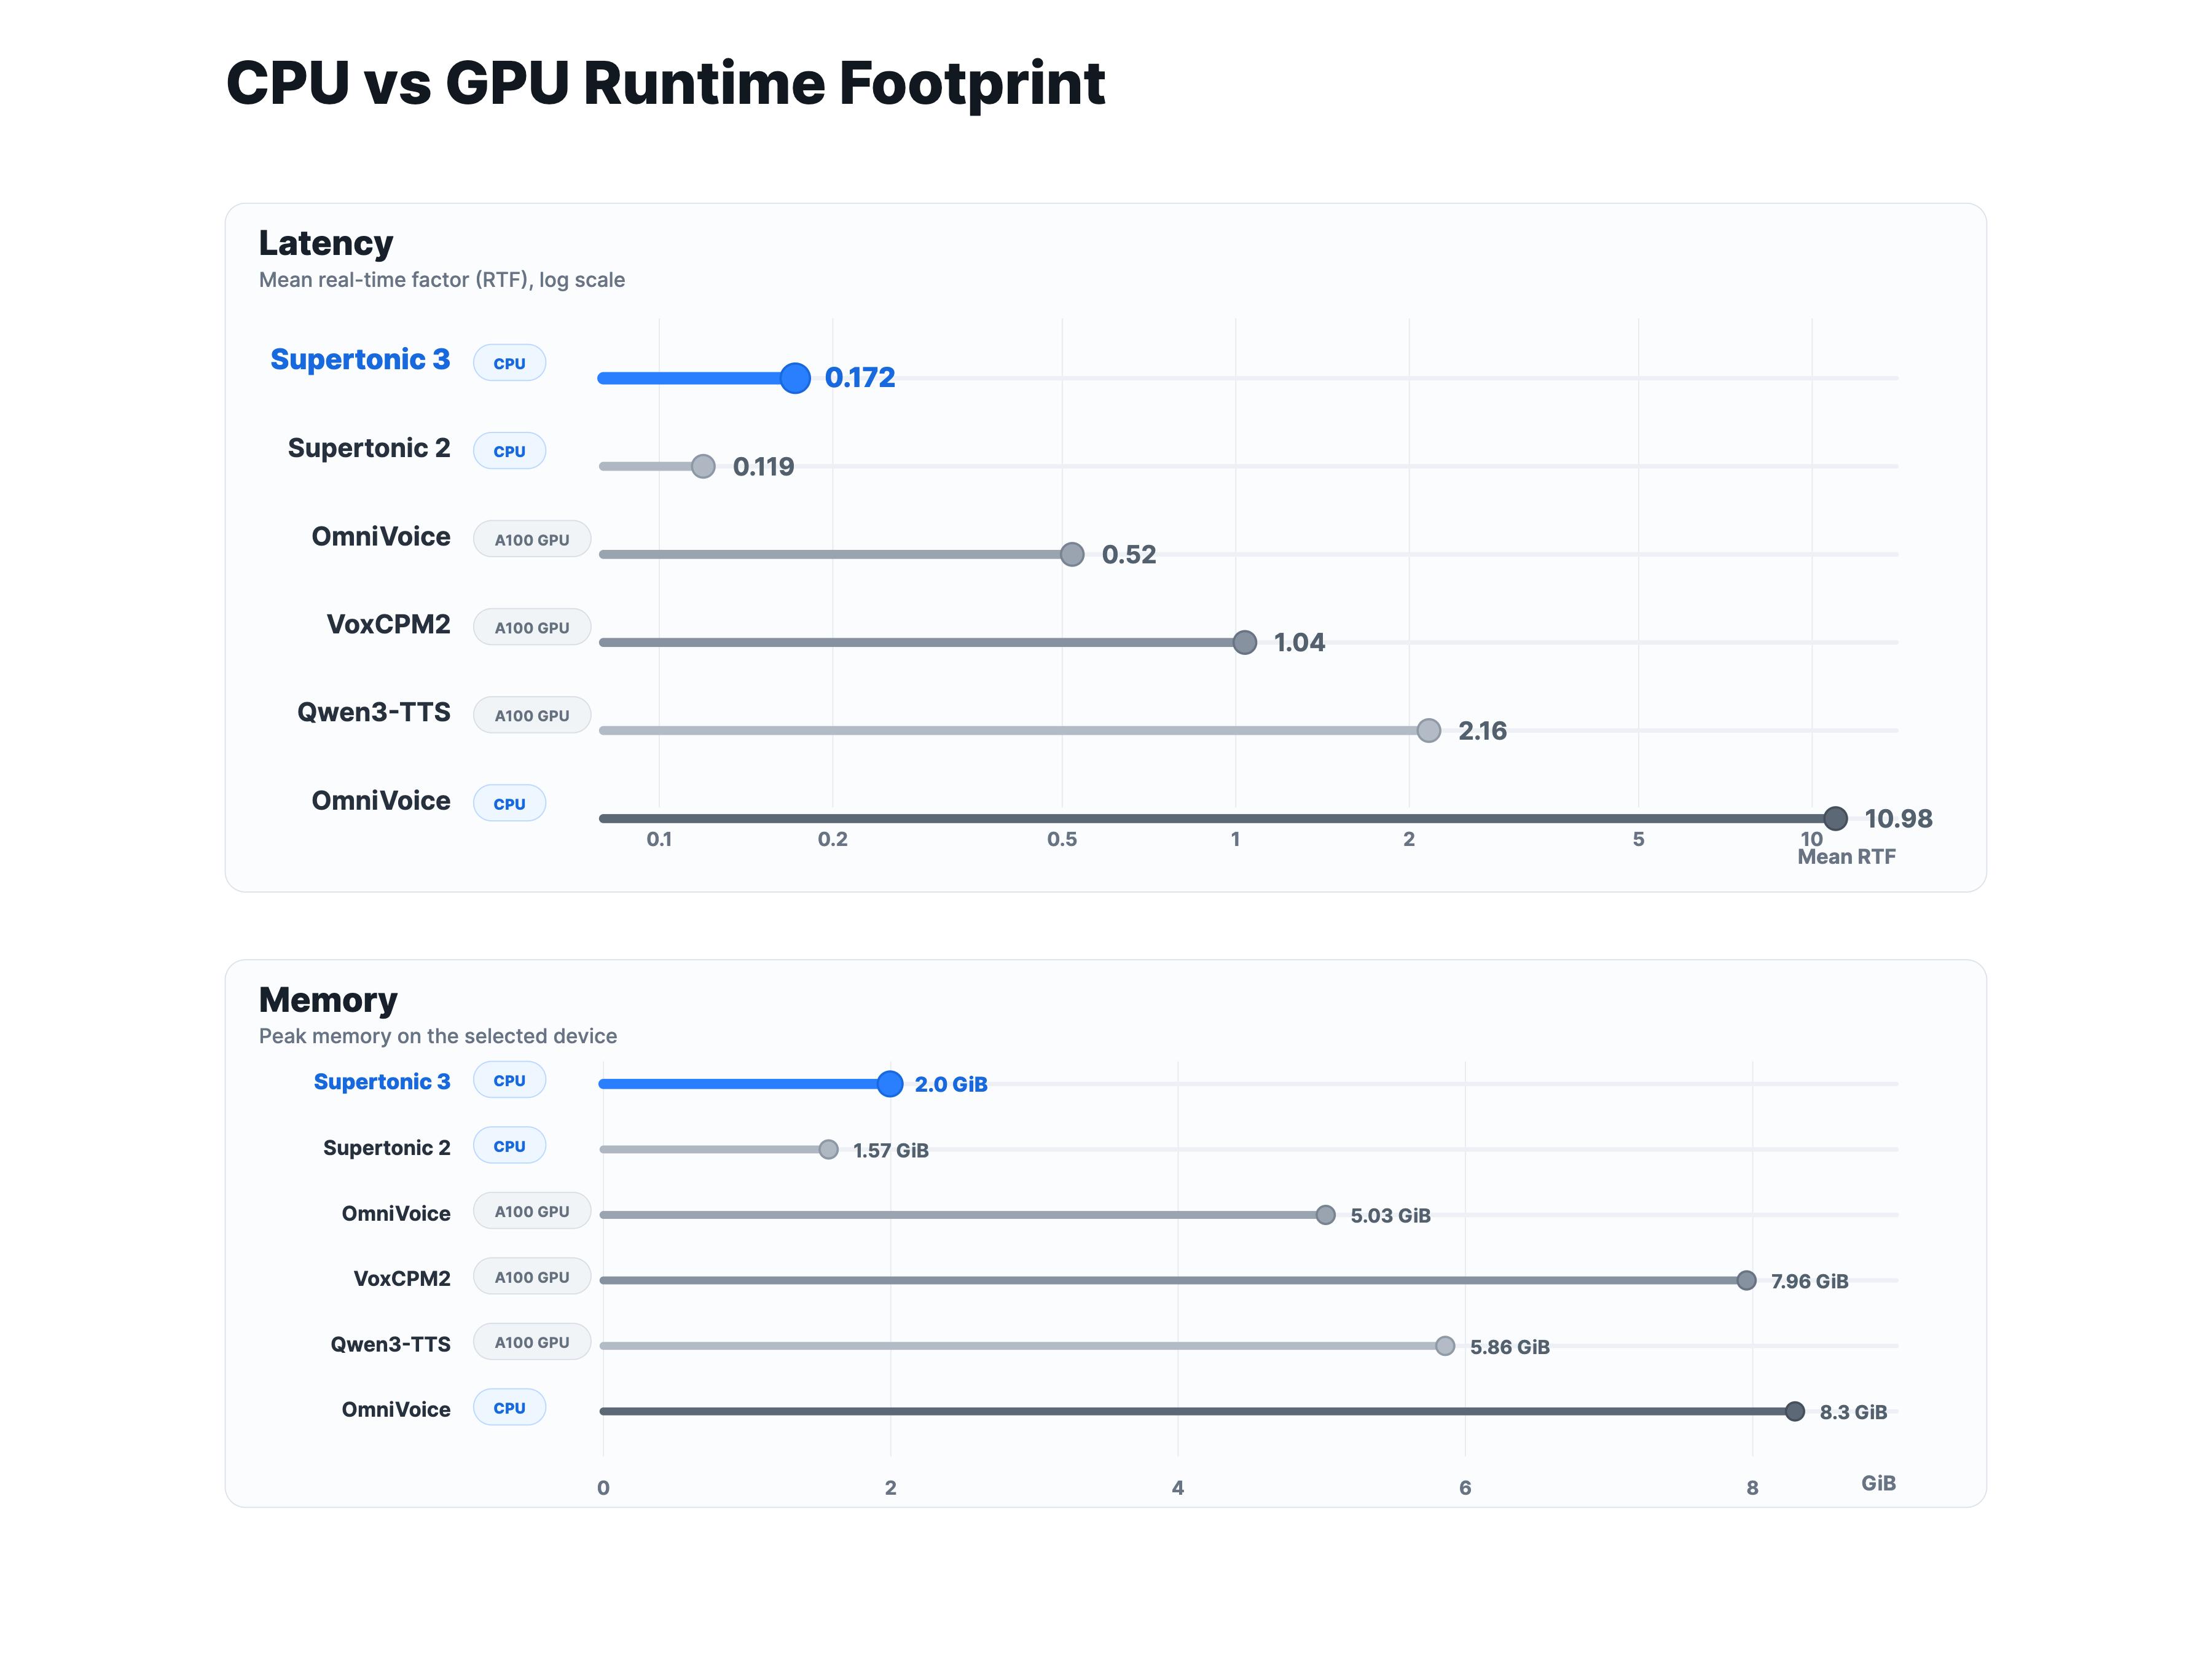
Supertonic 3 runs fast on CPU, even compared with larger baselines measured on A100 GPU, and uses substantially less memory. The open-weight fixed-voice setting does not require a GPU, which makes local, browser, and edge deployment much easier.
Model Size
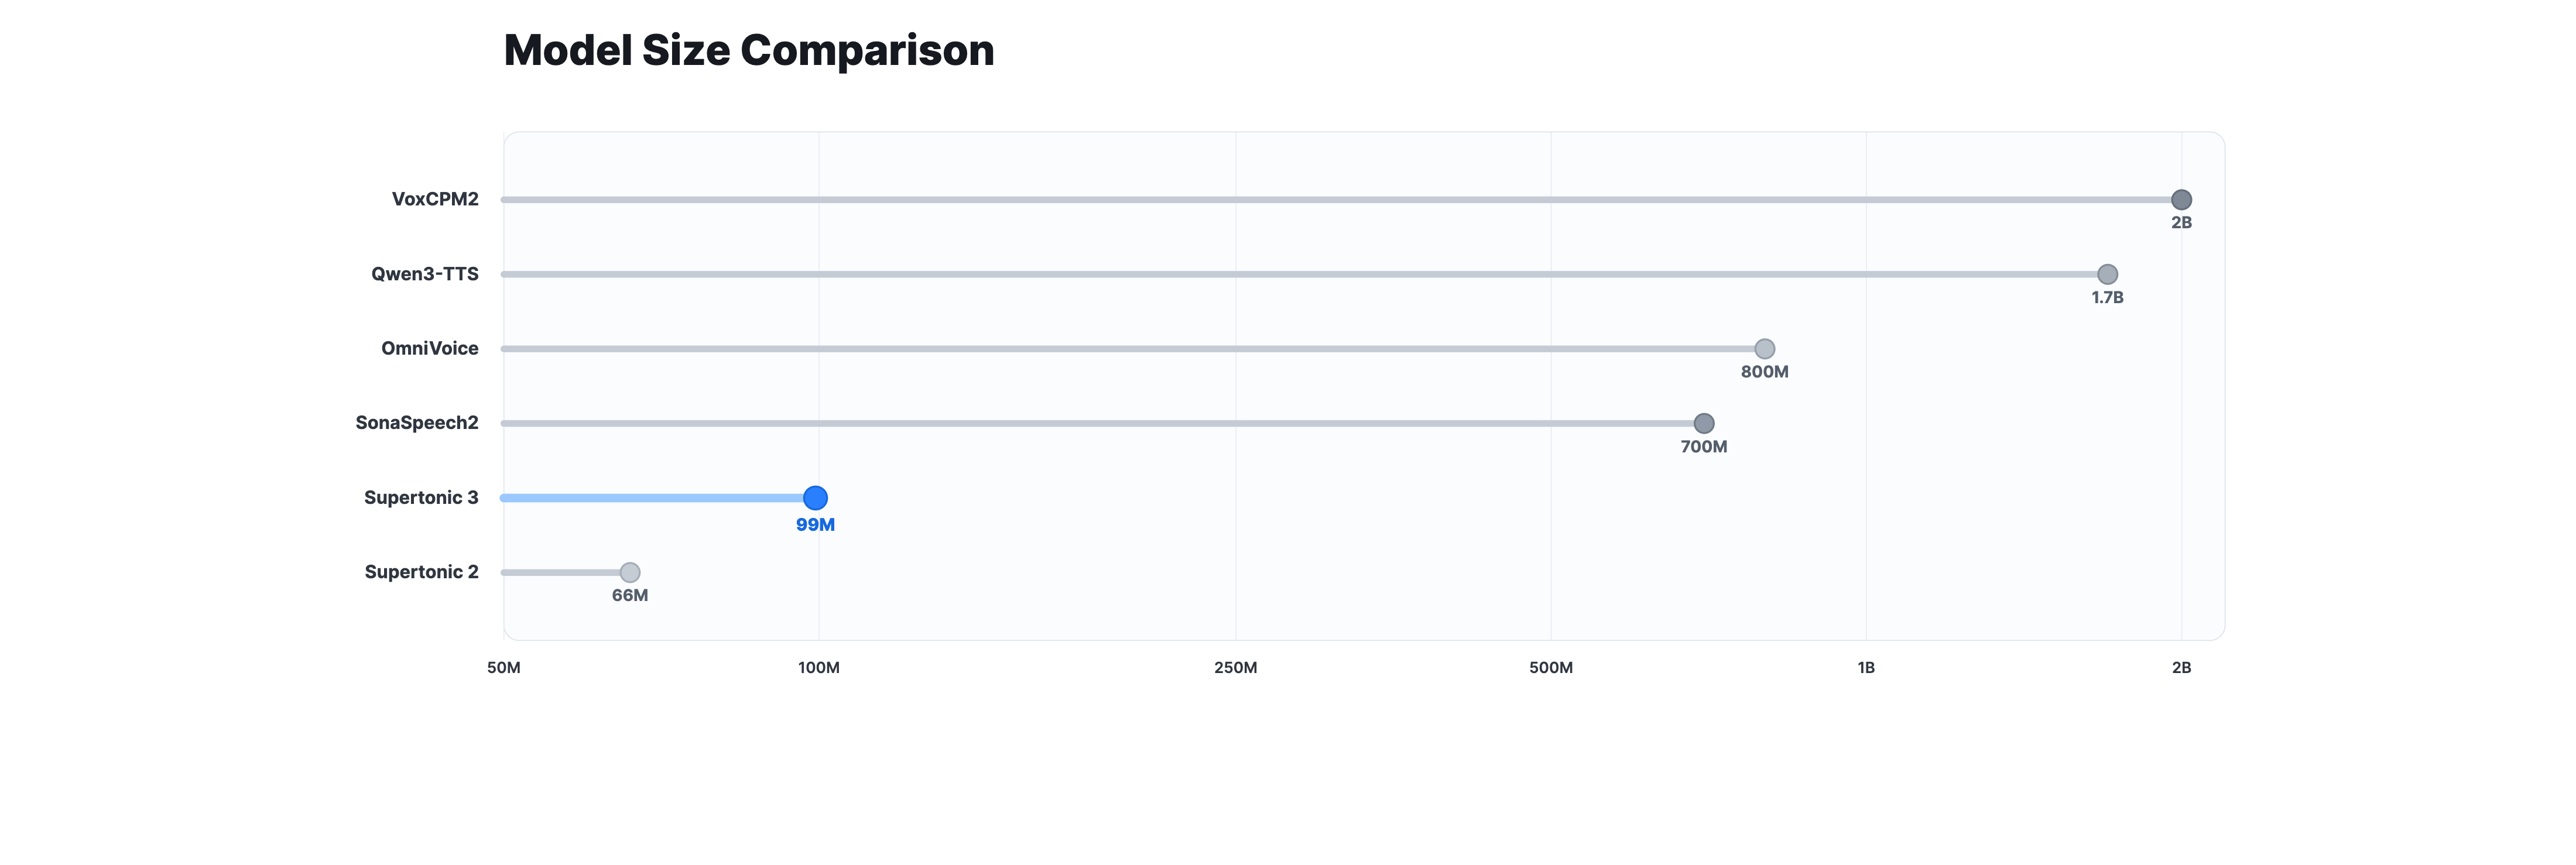
At about 99M parameters across the public ONNX assets, Supertonic 3 is much smaller than 0.7B to 2B class open TTS systems. The smaller model size is a practical advantage for download size, startup time, and on-device inference.
Voice Cloning
This open-weight repository focuses on fixed-voice, local TTS and does not include an official voice-cloning pipeline. If you want to bring your own voice to local Supertonic deployment, Voice Builder turns a short reference recording into version-specific JSON files for Supertonic 2 and Supertonic 3, so the same custom voice can move with you across supported Supertonic versions.
For a managed creation workflow, Supertonic 3 is now officially available in Supertone Play and the Supertone API. Use them when you want hosted content creation tools, diverse commercially usable preset voices, zero-shot voice cloning, or API-based integration without managing local model files. You can also listen to Supertonic 3 zero-shot samples on the official showcase.
Demo
Run locally: Follow Quick Start with the archived weights.
Raspberry Pi
Watch Supertonic running on a Raspberry Pi, demonstrating on-device, real-time text-to-speech synthesis:
https://github.com/user-attachments/assets/ea66f6d6-7bc5-4308-8a88-1ce3e07400d2
E-Reader
Experience Supertonic on an Onyx Boox Go 6 e-reader in airplane mode, achieving an average RTF of 0.3× with zero network dependency:
https://github.com/user-attachments/assets/64980e58-ad91-423a-9623-78c2ffc13680
Chrome Extension
Turns any webpage into audio in under one second, delivering lightning-fast, on-device text-to-speech with zero network dependency—free, private, and effortless:
https://github.com/user-attachments/assets/cc8a45fc-5c3e-4b2c-8439-a14c3d00d91c
Programming Language Support
We provide ready-to-use TTS inference examples across multiple ecosystems:
| Language/Platform | Path | Description |
|---|---|---|
| Python | py/ |
ONNX Runtime inference |
| Node.js | nodejs/ |
Server-side JavaScript |
| Browser | web/ |
WebGPU/WASM inference |
| Java | java/ |
Cross-platform JVM |
| C++ | cpp/ |
High-performance C++ |
| C# | csharp/ |
.NET ecosystem |
| Go | go/ |
Go implementation |
| Swift | swift/ |
macOS applications |
| iOS | ios/ |
Native iOS apps |
| Rust | rust/ |
Memory-safe systems |
| Flutter | flutter/ |
Cross-platform apps |
For detailed usage instructions, please refer to the README.md in each language directory.
Natural Text Handling
Supertonic is designed to handle complex, real-world text inputs that contain natural prose, punctuation, abbreviations, and proper nouns.
These historical audio samples are hosted externally and are not maintained as part of this archive.
Overview of Test Cases:
| Category | Key Challenges | Supertonic | ElevenLabs | OpenAI | Gemini | Microsoft |
|---|---|---|---|---|---|---|
| Financial Expression | Decimal currency, abbreviated magnitudes (M, K), currency symbols, currency codes | ✅ | ❌ | ❌ | ❌ | ❌ |
| Phone Number | Area codes, hyphens, extensions (ext.) | ✅ | ❌ | ❌ | ❌ | ❌ |
| Technical Unit | Decimal numbers with units, abbreviated technical notations | ✅ | ❌ | ❌ | ❌ | ❌ |
Example 1: Financial Expression
**Text:** > "The startup secured **$5.2M** in venture capital, a huge leap from their initial **$450K** seed round." **Challenges:** - Decimal point in currency ($5.2M should be read as "five point two million") - Abbreviated magnitude units (M for million, K for thousand) - Currency symbol ($) that needs to be properly pronounced as "dollars" **Audio Samples:** | System | Result | Audio Sample | |--------|--------|--------------| | **Supertonic** | ✅ | [🎧 Play Audio](https://drive.google.com/file/d/1eancUOhiSXCVoTu9ddh4S-OcVQaWrPV-/view?usp=sharing) | | ElevenLabs Flash v2.5 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1-r2scv7XQ1crIDu6QOh3eqVl445W6ap_/view?usp=sharing) | | OpenAI TTS-1 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1MFDXMjfmsAVOqwPx7iveS0KUJtZvcwxB/view?usp=sharing) | | Gemini 2.5 Flash TTS | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1dEHpNzfMUucFTJPQK0k4RcFZvPwQTt09/view?usp=sharing) | | VibeVoice Realtime 0.5B | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1b69XWBQnSZZ0WZeR3avv7E8mSdoN6p6P/view?usp=sharing) |
Example 2: Phone Number
**Text:** > "You can reach the hotel front desk at **(212) 555-0142 ext. 402** anytime." **Challenges:** - Area code in parentheses that should be read as separate digits - Phone number with hyphen separator (555-0142) - Abbreviated extension notation (ext.) - Extension number (402) **Audio Samples:** | System | Result | Audio Sample | |--------|--------|--------------| | **Supertonic** | ✅ | [🎧 Play Audio](https://drive.google.com/file/d/1z-e5iTsihryMR8ll1-N1YXkB2CIJYJ6F/view?usp=sharing) | | ElevenLabs Flash v2.5 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1HAzVXFTZfZm0VEK2laSpsMTxzufcuaxA/view?usp=sharing) | | OpenAI TTS-1 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/15tjfAmb3GbjP_kmvD7zSdIWkhtAaCPOg/view?usp=sharing) | | Gemini 2.5 Flash TTS | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1BCL8n7yligUZyso970ud7Gf5NWb1OhKD/view?usp=sharing) | | VibeVoice Realtime 0.5B | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1c0c0YM_Qm7XxSk2uSVYLbITgEDTqaVzL/view?usp=sharing) |
Example 3: Technical Unit
**Text:** > "Our drone battery lasts **2.3h** when flying at **30kph** with full camera payload." **Challenges:** - Decimal time duration with abbreviation (2.3h = two point three hours) - Speed unit with abbreviation (30kph = thirty kilometers per hour) - Technical abbreviations (h for hours, kph for kilometers per hour) - Technical/engineering context requiring proper pronunciation **Audio Samples:** | System | Result | Audio Sample | |--------|--------|--------------| | **Supertonic** | ✅ | [🎧 Play Audio](https://drive.google.com/file/d/1kvOBvswFkLfmr8hGplH0V2XiMxy1shYf/view?usp=sharing) | | ElevenLabs Flash v2.5 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1_SzfjWJe5YEd0t3R7DztkYhHcI_av48p/view?usp=sharing) | | OpenAI TTS-1 | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1P5BSilj5xFPTV2Xz6yW5jitKZohO9o-6/view?usp=sharing) | | Gemini 2.5 Flash TTS | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1GU82SnWC50OvC8CZNjhxvNZFKQb7I9_Y/view?usp=sharing) | | VibeVoice Realtime 0.5B | ❌ | [🎧 Play Audio](https://drive.google.com/file/d/1lUTrxrAQy_viEK2Hlu3KLLtTCe8jvbdV/view?usp=sharing) |
Note: These samples demonstrate how each system handles text normalization and pronunciation of complex expressions without requiring pre-processing or phonetic annotations.
Built with Supertonic
| Project | Description | Links |
|---|---|---|
| TLDRL | Free, on-device TTS extension for reading any webpage | Chrome |
| Read Aloud | Open-source TTS browser extension | Chrome · Edge · GitHub |
| PageEcho | E-Book reader app for iOS | App Store |
| VoiceChat | On-device voice-to-voice LLM chatbot in the browser | Demo · GitHub |
| OmniAvatar | Talking avatar video generator from photo + speech | Demo |
| CopiloTTS | Kotlin Multiplatform TTS SDK via ONNX Runtime | GitHub |
| Aftertone | Local post-reply TTS for Cursor & Claude Code (Supertonic 3 ONNX, on-device daemon) | GitHub · Demo |
| Voice Mixer | PyQt5 tool for mixing and modifying voice styles | GitHub |
| Supertonic MNN | Lightweight library based on MNN (fp32/fp16/int8) | GitHub · PyPI |
| Transformers.js | Hugging Face's JS library with Supertonic support | GitHub PR · Demo |
| Pinokio | 1-click localhost cloud for Mac, Windows, and Linux | Pinokio · GitHub |
Models & Versions
Version-specific branches and tags preserve historical code. Their old download
instructions may reference the original organization; use the model archives below.
The Quick Start above uses Supertonic 3 and its matching code on main.
| Supertonic 3 | Supertonic 2 | Supertonic 1 | |
|---|---|---|---|
| Status | Archived | Archived | Archived |
| Parameters | ~99M | ~66M | ~66M |
| Languages | 31 | 5 | 1 (en) |
| Expression Tags | ✅ 10 tags | — | — |
| Code | main | release/supertonic-2 | — |
| Weights | 🤗 HF | 🤗 HF | 🤗 HF |
Previous service notice — July 23, 2026
The following announcement is preserved as a historical record. Its service links may no longer be available; use the archive links above for code and models. > [!CAUTION] > ## ⚠️ Service and Repository Notice (July 23, 2026) > > **This repository will be archived, and there will be no further development or official support for the open-source Supertonic models.** > > **Voice Builder will no longer be accessible after August 31, 2026.** > > For details about the service changes, timeline, and information for existing Voice Builder users, please see the [official announcement](https://supertone.ai). > > Thank you to everyone who has used, contributed to, and supported Supertonic.Citation
The following papers describe the core technologies used in Supertonic. If you use this system in your research or find these techniques useful, please consider citing the relevant papers:
SupertonicTTS: Main Architecture
This paper introduces the overall architecture of SupertonicTTS, including the speech autoencoder, flow-matching based text-to-latent module, and efficient design choices.
@article{kim2025supertonic,
  title={SupertonicTTS: Towards Highly Efficient and Streamlined Text-to-Speech System},
  author={Kim, Hyeongju and Yang, Jinhyeok and Yu, Yechan and Ji, Seunghun and Morton, Jacob and Bous, Frederik and Byun, Joon and Lee, Juheon},
  journal={arXiv preprint arXiv:2503.23108},
  year={2025},
  url={https://arxiv.org/abs/2503.23108}
}
Length-Aware RoPE: Text-Speech Alignment
This paper presents Length-Aware Rotary Position Embedding (LARoPE), which improves text-speech alignment in cross-attention mechanisms.
@article{kim2025larope,
  title={Length-Aware Rotary Position Embedding for Text-Speech Alignment},
  author={Kim, Hyeongju and Lee, Juheon and Yang, Jinhyeok and Morton, Jacob},
  journal={arXiv preprint arXiv:2509.11084},
  year={2025},
  url={https://arxiv.org/abs/2509.11084}
}
Self-Purifying Flow Matching: Training with Noisy Labels
This paper describes the self-purification technique for training flow matching models robustly with noisy or unreliable labels.
@article{kim2025spfm,
  title={Training Flow Matching Models with Reliable Labels via Self-Purification},
  author={Kim, Hyeongju and Yu, Yechan and Yi, June Young and Lee, Juheon},
  journal={arXiv preprint arXiv:2509.19091},
  year={2025},
  url={https://arxiv.org/abs/2509.19091}
}
RobustSpeechFlow: Learning Robust Text-to-Speech Trajectories via Augmentation-based Contrastive Flow Matching
This paper describes the RobustSpeechFlow technique for improving the robustness and quality of text-to-speech generation by optimizing flow-matching trajectories against data variability
@misc{yang2026robustspeechflowlearningrobusttexttospeech,
      title={RobustSpeechFlow: Learning Robust Text-to-Speech Trajectories via Augmentation-based Contrastive Flow Matching},
      author={Jinhyeok Yang and Hyeongju Kim and Yechan Yu and Joon Byun and Frederik Bous and Juheon Lee},
      year={2026},
      eprint={2605.22083},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2605.22083},
}
License
This project's sample code is released under the MIT License. - see the LICENSE for details.
The accompanying model is released under the OpenRAIL-M License. - see the LICENSE file for details.
This model was trained using PyTorch, which is licensed under the BSD 3-Clause License but is not redistributed with this project. - see the LICENSE for details.
Copyright (c) 2026 Supertone Inc.
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|