📄 仓库 README
在 GitHub 查看 ↗
A next-generation crawling and spidering framework


Features • Installation • Usage • Scope • Config • Filters • Join Discord
Features
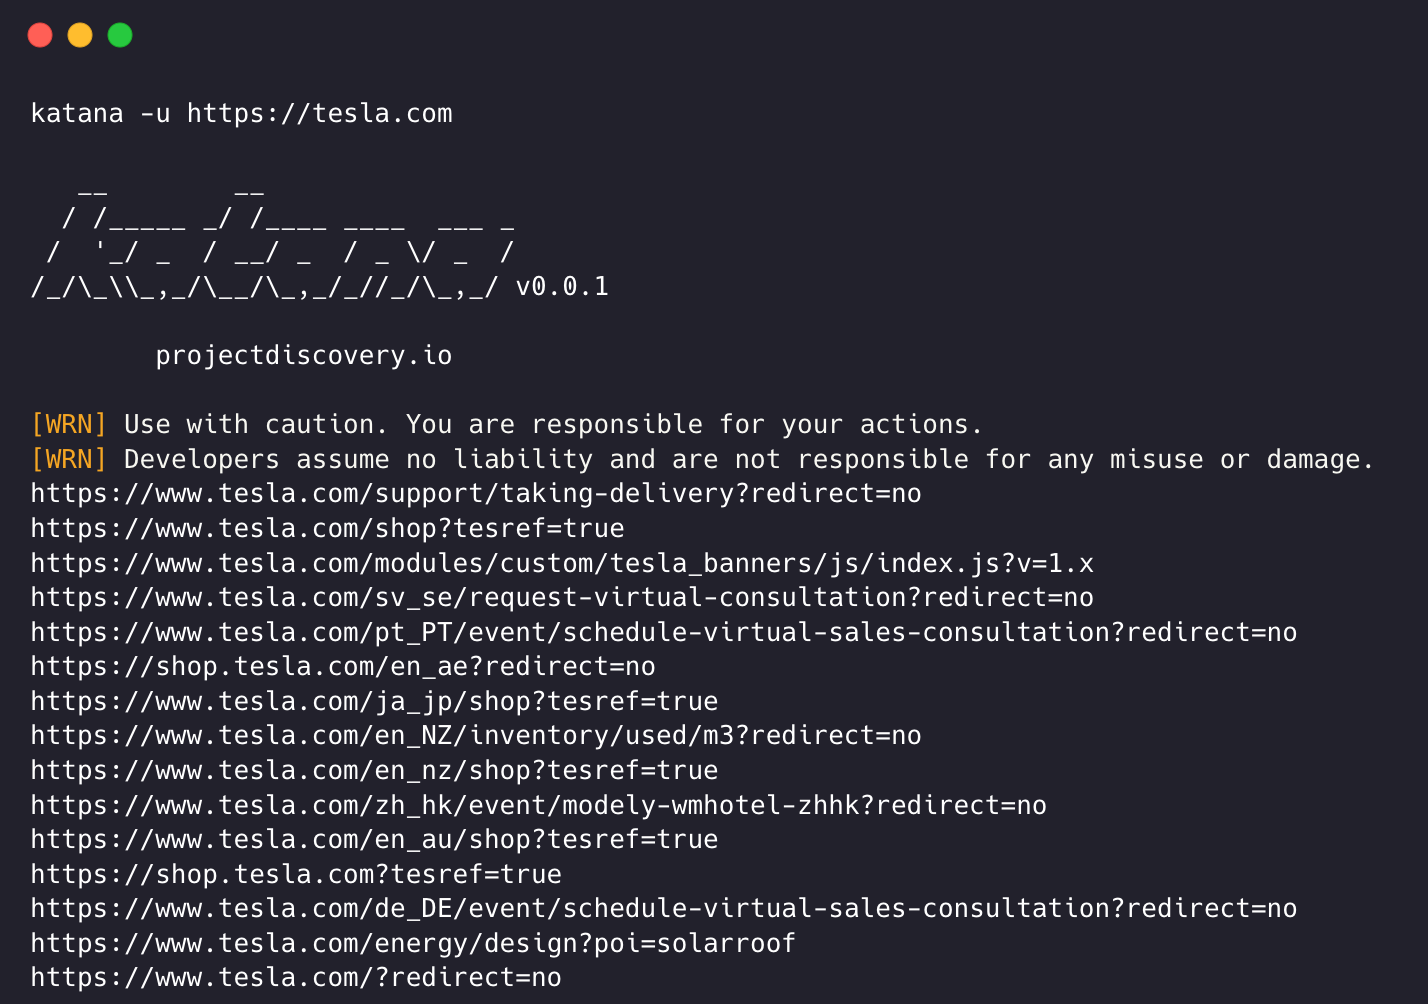
- Fast And fully configurable web crawling
- Standard and Headless mode
- JavaScript parsing / crawling
- Customizable automatic form filling
- Scope control - Preconfigured field / Regex
- Knowledge base - ML page-type / form classification (auto-downloaded model)
- Customizable output - Preconfigured fields
- INPUT - STDIN, URL and LIST
- OUTPUT - STDOUT, FILE and JSON
Installation
katana requires Go 1.26.10+ to install successfully. If you encounter any installation issues, we recommend trying with the latest available version of Go, as the minimum required version may have changed. Run the command below or download a pre-compiled binary from the release page.
CGO_ENABLED=1 go install github.com/projectdiscovery/katana/cmd/katana@latest
More options to install / run katana-
Docker
> To install / update docker to latest tag -docker pull projectdiscovery/katana:latest
docker run projectdiscovery/katana:latest -u https://tesla.com
docker run projectdiscovery/katana:latest -u https://tesla.com -system-chrome -headless
Ubuntu
> It's recommended to install the following prerequisites -sudo apt update
sudo apt install zip curl wget git snapd
sudo snap refresh
sudo snap install golang --classic
sudo install -d -m 0755 /etc/apt/keyrings
curl -fsSL https://dl.google.com/linux/linux_signing_key.pub \
| sudo gpg --dearmor -o /etc/apt/keyrings/google-chrome.gpg
echo "deb [arch=amd64 signed-by=/etc/apt/keyrings/google-chrome.gpg] \
http://dl.google.com/linux/chrome/deb/ stable main" \
| sudo tee /etc/apt/sources.list.d/google-chrome.list > /dev/null
sudo apt update
sudo apt install google-chrome-stable
go install github.com/projectdiscovery/katana/cmd/katana@latest
Usage
katana -h
This will display help for the tool. Here are all the switches it supports.
```console Katana is a fast crawler focused on execution in automation pipelines offering both headless and non-headless crawling.
Usage: ./katana [flags]
Flags: INPUT: -u, -list string[] target url / list to crawl -resume string resume scan using resume.cfg -e, -exclude string[] exclude host matching specified filter ('cdn', 'private-ips', cidr, ip, regex)
CONFIGURATION: -r, -resolvers string[] list of custom resolver (file or comma separated) -d, -depth int maximum depth to crawl (default 3) -jc, -js-crawl enable endpoint parsing / crawling in javascript file -jsl, -jsluice enable jsluice parsing in javascript file (memory intensive) -ct, -crawl-duration value maximum duration to crawl the target for (s, m, h, d) (default s) -kf, -known-files string enable crawling of known files (all,robotstxt,sitemapxml), a minimum depth of 3 is required to ensure all known files are properly crawled. -mrs, -max-response-size int maximum response size to read (default 4194304) -timeout int time to wait for request in seconds (default 10) -aff, -automatic-form-fill enable automatic form filling (experimental) -fx, -form-extraction extract form, input, textarea & select elements in jsonl output -retry int number of times to retry the request (default 1) -proxy string http/socks5 proxy to use -td, -tech-detect enable technology detection -H, -headers string[] custom header/cookie to include in all http request in header:value format (file) -config string path to the katana configuration file -fc, -form-config string path to custom form configuration file -flc, -field-config string path to custom field configuration file -s, -strategy string Visit strategy (depth-first, breadth-first, priority) (default "depth-first") -iqp, -ignore-query-params Ignore crawling same path with different query-param values -fsu, -filter-similar filter crawling of similar looking URLs (e.g., /users/123 and /users/456) -fst, -filter-similar-threshold int number of distinct values before a path position is treated as parameter (default 10) -tlsi, -tls-impersonate enable experimental client hello (ja3) tls randomization -dr, -disable-redirects disable following redirects (default false) -pcs, -page-content-similar enable page content similarity filtering (simhash|tfidf|bm25) -pcsm, -page-content-similar-mode string similarity mode: simhash, tfidf, or bm25 (default simhash) -pcsd, -page-content-similar-distance int simhash max hamming distance (default 3) -pcst, -page-content-similar-threshold float tfidf/bm25 min score 0-1 (default 0.85) -pcsn, -page-content-similar-budget int pages to fully process per similarity cluster (default 1) -sdd, -similarity-deduplication alias for -pcs -kb, -knowledge-base enable knowledge base classification -kb-secrets enable secrets extractor in the knowledge base -kb-validate-secrets validate detected secrets against their provider (sends live API calls) -kb-endpoints enable endpoints extractor (classifies REST/GraphQL/SOAP/XHR requests) -mdp, -max-domain-pages int maximum number of pages to crawl per domain (default unlimited)
DEBUG: -health-check, -hc run diagnostic check up -elog, -error-log string file to write sent requests error log -pprof-server enable pprof server
HEADLESS: -hl, -headless enable headless hybrid crawling (experimental) -sc, -system-chrome use local installed chrome browser instead of katana installed -sb, -show-browser show the browser on the screen with headless mode -ho, -headless-options string[] start headless chrome with additional options -nos, -no-sandbox start headless chrome in --no-sandbox mode -cdd, -chrome-data-dir string path to store chrome browser data -scp, -system-chrome-path string use specified chrome browser for headless crawling -noi, -no-incognito start headless chrome without incognito mode -cwu, -chrome-ws-url string use chrome browser instance launched elsewhere with the debugger listening at this URL -xhr, -xhr-extraction extract xhr request url,method in jsonl output -pls, -page-load-strategy string page load strategy (heuristic, load, domcontentloaded, networkidle, none) (default "heuristic") -dwt, -dom-wait-time int time in seconds to wait after page load when using domcontentloaded strategy (default 5) -csp, -captcha-solver-provider string captcha solver provider (e.g. capsolver) -csk, -captcha-solver-key string captcha solver provider api key (env CAPTCHA_SOLVER_KEY)
AI: -ai-url string openai compatible api url for crawl decisions (e.g. http://127.0.0.1:11434/v1) -ai-model string model to use with -ai-url -ai-key string api key for -ai-url (env AI_API_KEY) -ai-record string file to record ai answers to, reused on later runs -ai-replay string file to replay recorded ai answers from, without calling the api -ai-max-calls int maximum ai api calls per crawl (0 = unlimited) (default 100)
SCOPE: -cs, -crawl-scope string[] in scope url regex to be followed by crawler -cos, -crawl-out-scope string[] out of scope url regex to be excluded by crawler -fs, -field-scope string pre-defined scope field (dn,rdn,fqdn) or custom regex (e.g., '(company-staging.io|company.com)') (default "rdn") -ns, -no-scope disables host based default scope -do, -display-out-scope display external endpoint from scoped crawling
FILTER: -mr, -match-regex string[] regex or list of regex to match on output url (cli, file) -fr, -filter-regex string[] regex or list of regex to filter on output url (cli, file) -f, -field string field to display in output (url,path,fqdn,rdn,rurl,qurl,qpath,file,ufile,key,value,kv,dir,udir) (Deprecated: use -output-template instead) -sf, -store-field string field to store in per-host output (url,path,fqdn,rdn,rurl,qurl,qpath,file,ufile,key,value,kv,dir,udir) -em, -extension-match string[] match output for given extension (eg, -em php,html,js,none) -ef, -extension-filter string[] filter output for given extension (eg, -ef png,css) -ndef, -no-default-ext-filter bool remove default extensions from the filter list -mdc, -match-condition string match response with dsl based condition -fdc, -filter-condition string filter response with dsl based condition -duf, -disable-unique-filter disable duplicate content filtering -filter-page-type string[] filter response with page type (e.g. error,captcha,parked)
RATE-LIMIT: -c, -concurrency int number of concurrent fetchers to use (default 10) -p, -parallelism int number of concurrent inputs to process (default 10) -rd, -delay int
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|