📄 仓库 README
在 GitHub 查看 ↗


Deutsch | Español | français | 日本語 | 한국어 | Português | Русский | 中文
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
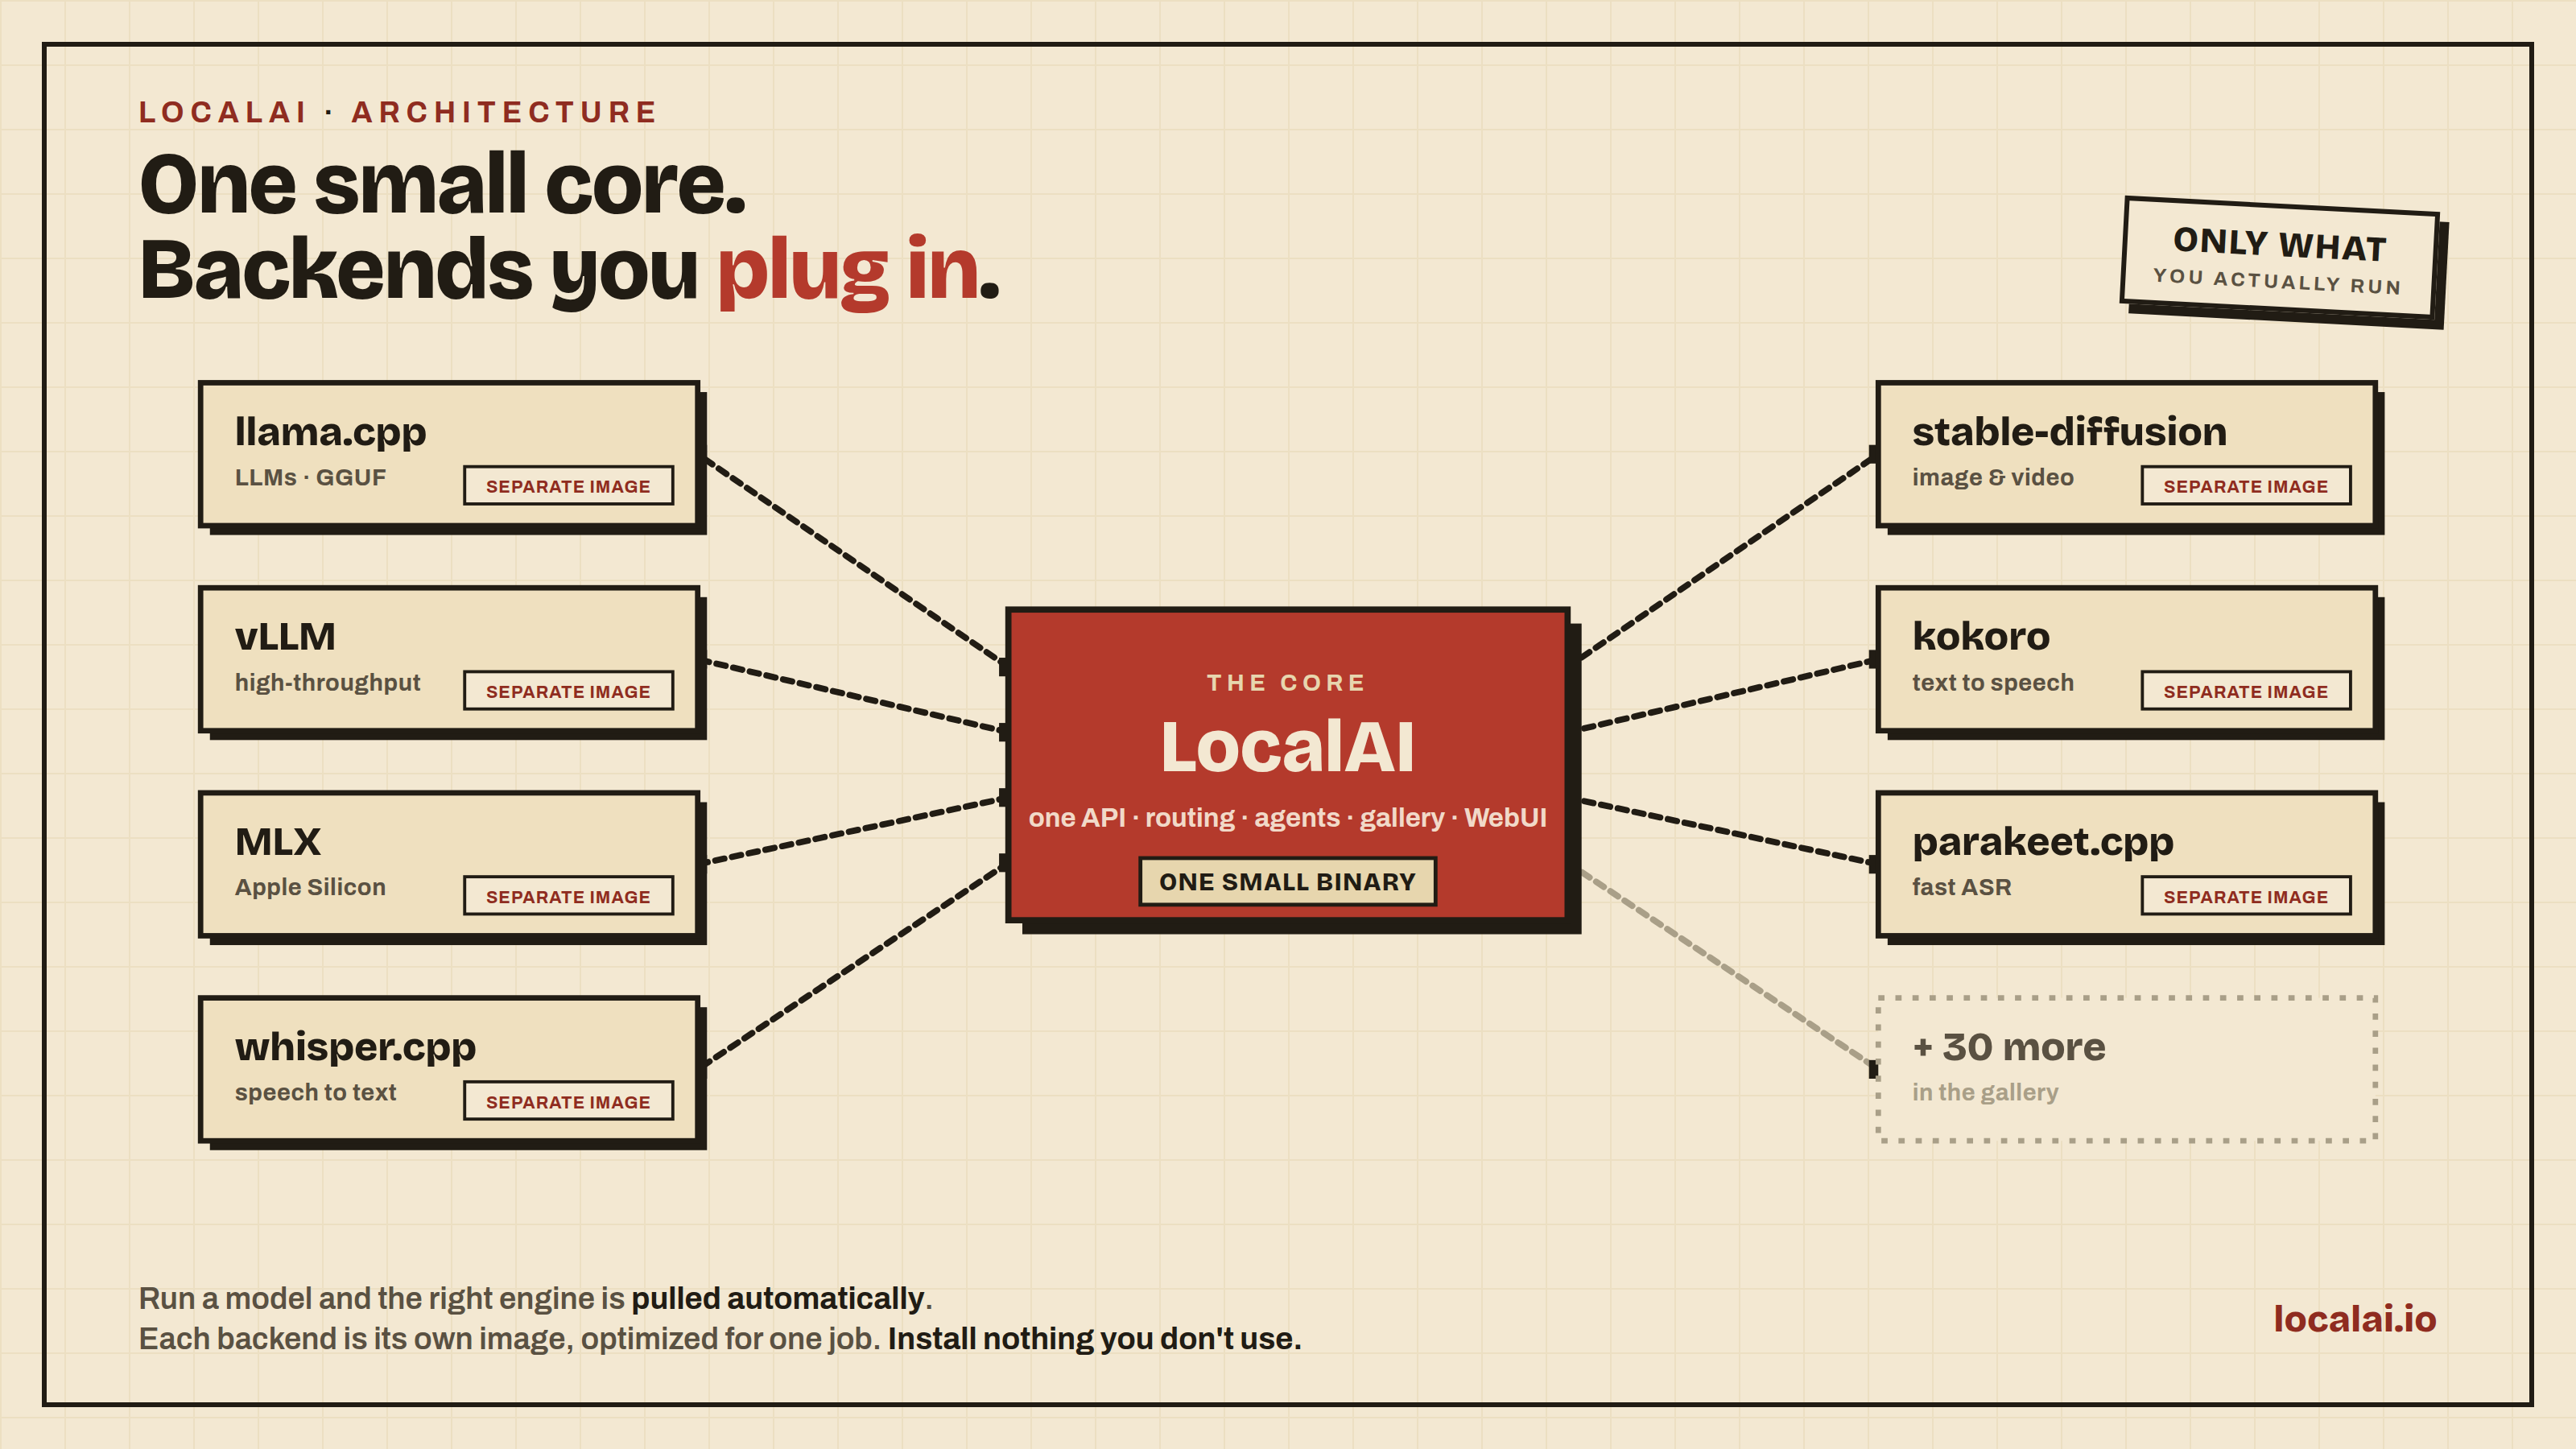
A small core, not a bundle. Each backend wraps a best-in-class engine (llama.cpp, vLLM, whisper.cpp, stable-diffusion, MLX...) in its own image, pulled only when a model needs it. You install nothing you don't use.
- Composable by design: backends are separate and pulled on demand, so you install only what your model needs
- Open and extensible: load any model, or build your own backend in any language against an open interface
- Drop-in API compatibility: OpenAI, Anthropic, and ElevenLabs APIs across every backend
- Any model, any modality: LLMs, vision, voice, image, and video behind one API
- Any hardware: NVIDIA, AMD, Intel, Apple Silicon, Vulkan, or CPU-only
- Multi-user ready: API key auth, user quotas, role-based access
- Built-in AI agents: autonomous agents with tool use, RAG, MCP, and skills
- Privacy-first: your data never leaves your infrastructure
Created by Ettore Di Giacinto and maintained by the LocalAI team.
:book: Documentation | :speech_balloon: Discord | 💻 Quickstart | 🖼️ Models | ❓FAQ
Guided tour
https://github.com/user-attachments/assets/08cbb692-57da-48f7-963d-2e7b43883c18
Click to see more!
#### User and auth https://github.com/user-attachments/assets/228fa9ad-81a3-4d43-bfb9-31557e14a36c #### Agents https://github.com/user-attachments/assets/6270b331-e21d-4087-a540-6290006b381a #### Usage metrics per user https://github.com/user-attachments/assets/cbb03379-23b4-4e3d-bd26-d152f057007f #### Fine-tuning and Quantization https://github.com/user-attachments/assets/5ba4ace9-d3df-4795-b7d4-b0b404ea71ee #### WebRTC https://github.com/user-attachments/assets/ed88e34c-fed3-4b83-8a67-4716a9feeb7bQuickstart
macOS
Note: The DMG is not signed by Apple. After installing, run:
sudo xattr -d com.apple.quarantine /Applications/LocalAI.app. See #6268 for details.
Containers (Docker, podman, ...)
Already ran LocalAI before? Use
docker start -i local-aito restart an existing container.
CPU only:
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest
NVIDIA GPU:
# CUDA 13
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-13

# CUDA 12
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-gpu-nvidia-cuda-12

# NVIDIA Jetson ARM64 (CUDA 12, for AGX Orin and similar)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64

# NVIDIA Jetson ARM64 (CUDA 13, for DGX Spark)
docker run -ti --name local-ai -p 8080:8080 --gpus all localai/localai:latest-nvidia-l4t-arm64-cuda-13
AMD GPU (ROCm):
docker run -ti --name local-ai -p 8080:8080 --device=/dev/kfd --device=/dev/dri --group-add=video localai/localai:latest-gpu-hipblas
Intel GPU (oneAPI):
docker run -ti --name local-ai -p 8080:8080 --device=/dev/dri/card1 --device=/dev/dri/renderD128 localai/localai:latest-gpu-intel
Vulkan GPU:
docker run -ti --name local-ai -p 8080:8080 localai/localai:latest-gpu-vulkan
Loading models
# From the model gallery (see available models with `local-ai models list` or at https://models.localai.io)
local-ai run llama-3.2-1b-instruct:q4_k_m
# From Huggingface
local-ai run huggingface://TheBloke/phi-2-GGUF/phi-2.Q8_0.gguf
# From the Ollama OCI registry
local-ai run ollama://gemma:2b
# From a YAML config
local-ai run https://gist.githubusercontent.com/.../phi-2.yaml
# From a standard OCI registry (e.g., Docker Hub)
local-ai run oci://localai/phi-2:latest
To work with a running LocalAI server from the terminal, start the built-in agent from another shell. It answers questions, reads your files and runs commands on your machine, asking you to approve anything that changes state. Inside a session, /models lists installed models and /model <name> switches between them. See the Terminal agent docs.
# Terminal 1
local-ai run llama-3.2-1b-instruct:q4_k_m

# Terminal 2
local-ai chat --model llama-3.2-1b-instruct:q4_k_m
Automatic Backend Detection: LocalAI automatically detects your GPU capabilities and downloads the appropriate backend. For advanced options, see GPU Acceleration.
For more details, see the Getting Started guide.
Latest News
- October 2026: LocalAI 4.11.0 — Audio scenes with transcription, speaker labels, and sound detection. Also the Decisions API (
/v1/systemone), model failover chains, signed OCI galleries, and Kimodo text-to-animation. Release notes - September 2026: LocalAI 4.10.0 — A fleet operations dashboard, one credentials file for private model sources, and
local-ai benchmarkfor measuring model latency and throughput. Release notes - August 2026: LocalAI 4.9.0 — Deny-by-default authentication, opt-in chat context compression, unified model and backend management, and MiniMax-H3 video generation with audio. Release notes
- August 2026: LocalAI 4.8.0 — Introducing vllm.cpp (alpha development builds), image-to-3D generation with a built-in viewer, and
audio.cppfor speech, transcription, VAD, diarization, source separation and sound generation. Release notes - July 2026: LocalAI 4.7.0 — Managed voice cloning profiles, local video and talking-avatar generation, and interleaved reasoning with tool calls. Release notes
- July 2026: LocalAI 4.6.0 — AMD ROCm fixes, predictable realtime pipeline warmup, conversation forking, and more reliable distributed model loading. Release notes
- June 2026: LocalAI 4.5.0 — Native depth estimation and sound-event detection, NER-based PII filtering, and speaker-aware realtime conversations with automatic history compaction. Release notes
Older news
- **June 2026**: New native biometric backends from the LocalAI team: [voice-detect.cpp](https://github.com/localai-org/voice-detect.cpp) for speaker recognition and voice analysis (ECAPA-TDNN, WeSpeaker, ERes2Net, CAM++, wav2vec2 age/gender/emotion) and [face-detect.cpp](https://github.com/mudler/face-detect.cpp) for face detection, recognition, demographics and anti-spoofing (SCRFD/ArcFace, YuNet/SFace). Both are from-scratch C++/ggml engines with no Python or onnxruntime at inference, self-contained GGUF weights, bit-exact parity with the reference, and GPU cuDNN parity, replacing the heavier Python `insightface` and `speaker-recognition` backends ([PR #10441](https://github.com/mudler/LocalAI/pull/10441)). - **June 2026**: New [realtime voice assistant demo](https://github.com/localai-org/localai-realtime-demo) (a tiny Go client for the Realtime API with a full talk-back voice loop and tool calling), plus [streaming of the realtime LLM / TTS / transcription pipeline stages](https://github.com/mudler/LocalAI/pull/10176) and [configurable WebRTC ICE candidates](https://github.com/mudler/LocalAI/pull/10231). - **June 2026**: Big speech push: the [parakeet.cpp](https://github.com/mudler/parakeet.cpp) ASR engine gains [NeMo-faithful segment timestamps](https://github.com/mudler/LocalAI/pull/10207), a [multilingual streaming Nemotron-3.5 model](https://github.com/mudler/LocalAI/pull/10199), [dynamic batching for concurrent transcription](https://github.com/mudler/LocalAI/pull/10112) and [CUDA graphs](https://github.com/mudler/LocalAI/pull/10273); the new [CrispASR backend](https://github.com/mudler/LocalAI/pull/10099) adds multi-architecture ASR + TTS, and [60 Piper TTS voices across 42 languages](https://github.com/mudler/LocalAI/pull/10296) land in the gallery (plus [per-request TTS instructions and params](https://github.com/mudler/LocalAI/pull/10172)). - **June 2026**: New backends and models: [locate-anything.cpp](https://github.com/mudler/LocalAI/pull/10264) for open-vocabulary object detection via ggml, [Ideogram4 image generation](https://github.com/mudler/LocalAI/pull/10201) in stablediffusion-ggml, [llama.cpp video input](https://github.com/mudler/LocalAI/pull/10216), and the [Gemma 4 QAT family with MTP speculative-decoding pairs](https://github.com/mudler/LocalAI/pull/10215). Plus an [interactive CLI chat mode](https://github.com/mudler/LocalAI/pull/10226) and [RAG source citations in agent responses](https://github.com/mudler/LocalAI/pull/10228). - **June 2026**: Distributed mode hardening: [prefix-cache-aware routing](https://github.com/mudler/LocalAI/pull/10071), a [production-ready request router with auto-sized embedding/rerank batches](https://github.com/mudler/LocalAI/pull/10104), [ds4 layer-split distributed inference](https://github.com/mudler/LocalAI/pull/10098), [NATS JWT auth + TLS/mTLS](https://github.com/mudler/LocalAI/pull/10159), and [resumable file uploads](https://github.com/mudler/LocalAI/pull/10109). - **May 2026**: **LocalAI 4.3.0** - `llama.cpp` [prompt cache on by default](https://github.com/mudler/LocalAI/pull/9925) (repeated system prompts collapse from minutes to seconds), [keyless cosign signing of backend OCI images](https://github.com/mudler/LocalAI/pull/9823), [per-API-key + per-user usage attribution](https://github.com/mudler/LocalAI/pull/9920), Distributed v3 with [per-request replica routing](https://github.com/mudler/LocalAI/pull/9968). [Release notes](https://github.com/mudler/LocalAI/releases/tag/v4.3.0) - **May 2026**: **LocalAI 4.2.0** - LocalAI sees and hears: [voice recognition](https://github.com/mudler/LocalAI/pull/9500), [face recognition + antispoofing liveness](https://github.com/mudler/LocalAI/pull/9480), speaker diarization. Plus [drop-in Ollama API](https://github.com/mudler/LocalAI/pull/9284), [video generation](https://github.com/mudler/LocalAI/pull/9420), redesigned UI with i18n + admin-configurable branding, vLLM at feature parity with llama.cpp, and 11 new backends. [Release notes](https://github.com/mudler/LocalAI/releases/tag/v4.2.0) - **April 2026**: **LocalAI 4.1.0** - LocalAI becomes a control tower: distributed cluster mode with VRAM-aware smart routing + autoscaling, multi-user platform with OIDC and API keys, per-user quotas with predictive analytics, in-UI fine-tuning with TRL (auto-export to GGUF), on-the-fly quantization backend, visual pipeline editor. [Release notes](https://github.com/mudler/LocalAI/releases/tag/v4.1.0) - **March 2026**: **LocalAI 4.0.0** - native agentic orchestration with the new [Agenthub](https://agenthub.localai.io) community hub, full React UI rewrite with Canvas mode, [MCP Apps + client-side](https://github.com/mudler/LocalAI/pull/8947) with tool streaming, [WebRTC realtime audio](https://github.com/mudler/LocalAI/pull/8790), [MLX-distributed](https://github.com/mudler/LocalAI/pull/8801). [Release notes](https://github.com/mudler/LocalAI/releases/tag/v4.0.0) - **February 2026**: [Realtime API for audio-to-audio with tool calling](https://github.com/mudler/LocalAI/pull/6245), [ACE-Step 1.5 support](https://github.com/mudler/LocalAI/pull/8396) - **January 2026**: **LocalAI 3.10.0** — Anthropic API support, Open Responses API, video & image generation (LTX-2), unified GPU backends, tool streaming, Moonshine, Pocket-TTS. [Release notes](https://github.com/mudler/LocalAI/releases/tag/v3.10.0) - **December 2025**: [Dynamic Memory Resource reclaimer](https://github.com/mudler/LocalAI/pull/7583), [Automatic multi-GPU model fitting (llama.cpp)](https://github.com/mudler/LocalAI/pull/7584), [Vibevoice backend](https://github.com/mudler/LocalAI/pull/7494) - **November 2025**: [Import models via URL](https://github.com/mudler/LocalAI/pull/7245), [Multiple chats and history](https://github.com/mudler/LocalAI/pull/7325) - **October 2025**: [Model Context Protocol (MCP)](https://localai.io/docs/features/mcp/) support for agentic capabilities - **September 2025**: New Launcher for macOS and Linux, extended backend support for Mac and Nvidia L4T, MLX-Audio, WAN 2.2 - **August 2025**: MLX, MLX-VLM, Diffusers, llama.cpp now supported on Apple Silicon - **July 2025**: All backends migrated outside the main binary — [lightweight, modular architecture](https://github.com/mudler/LocalAI/releases/tag/v3.2.0)For older news and full release notes, see GitHub Releases and the blog.
Features
- Text generation (
llama.cpp,transformers,vllm... and more) - Text to Audio
- Audio to Text
- Image generation
- OpenAI-compatible tools API
- Realtime API (Speech-to-speech)
- Embeddings generation
- Constrained grammars
- Download models from Huggingface
- Vision API
- Object Detection
- Reranker API
- P2P Inferencing
- Distributed Mode — Horizontal scaling with PostgreSQL + NATS
- Model Context Protocol (MCP)
- Built-in Agents — Autonomous AI agents with tool use, RAG, skills, SSE streaming, and Agent Hub
- Backend Gallery — Install/remove backends on the fly via OCI images
- Voice Activity Detection (Silero-VAD)
- Integrated WebUI
Supported Backends & Acceleration
LocalAI supports 60+ backends including llama.cpp, vLLM, SGLang, transformers, whisper.cpp, diffusers, MLX, MLX-VLM, and many more. Hardware acceleration is available for NVIDIA (CUDA 12/13), AMD (ROCm), Intel (oneAPI/SYCL), Apple Silicon (Metal), Vulkan, and NVIDIA Jetson (L4T). All backends can be installed on-the-fly from the Backend Gallery.
See the full Backend & Model Compatibility Table and GPU Acceleration guide.
Backends built by us
Most backends wrap a best-in-class upstream engine. A handful of them are native C/C++/GGML engines (no Python at inference) developed and maintained by the LocalAI project itself:
| Backend | What it does |
|---|---|
| vllm.cpp | From-scratch C++20 port of vLLM for text generation: paged KV cache, continuous batching, prefix caching, safetensors + GGUF loading, engine-enforced structured output, on CPU, CUDA, Metal and Vulkan. Also serves MiniMax-H3 joint video+audio generation |
| parakeet.cpp | C++/GGML port of NVIDIA NeMo Parakeet ASR (tdt/ctc/rnnt/hybrid), with cache-aware streaming transcription |
| moss-transcribe.cpp | C++/GGML port of OpenMOSS MOSS-Transcribe-Diarize: joint long-form transcription, speaker diarization and timestamping in a single pass |
| moss-tts.cpp | C++/GGML port of the OpenMOSS MOSS-TTS family: text-to-speech (MOSS-TTS-Local v1.5, 48 kHz stereo) with reference-audio voice cloning, through the MOSS-Audio-Tokenizer neural codec |
| magpie-tts.cpp | C++/GGML port of NVIDIA's Magpie TTS Multilingual 357M: 22.05 kHz mono text-to-speech in 5 voices and 9+ languages, with the NanoCodec neural codec and tokenizer/G2P embedded in a single GGUF |
| ced.cpp | C++/GGML port of the CED audio-tagging models: sound-event classification (527-class AudioSet) over REST and the realtime API for live recognition |
| voice-detect.cpp | Speaker recognition and voice analysis (ECAPA-TDNN, WeSpeaker, ERes2Net, CAM++, wav2vec2 age/gender/emotion), replacing the Python speaker-recognition backend |
| voxtral-tts.c | Mistral Voxtral-4B-TTS text-to-speech in pure C: 20 preset voices across 9 languages, 24 kHz WAV output, no dependencies beyond libc |
| vibevoice.cpp | Native port of Microsoft VibeVoice for TTS (voice cloning) and long-form ASR with speaker diarization |
| rf-detr.cpp | Native RF-DETR object detection and instance segmentation |
| locate-anything.cpp | Open-vocabulary object detection and visual grounding (LocateAnything-3B) |
| depth-anything.cpp | Depth Anything 3 monocular metric depth + camera pose estimation |
| face-detect.cpp | Face detection, recognition, demographics and anti-spoofing (SCRFD/ArcFace, YuNet/SFace), replacing the Python insightface backend |
| timestral.cpp | Mistral Timestral time-series forecasting: quantile forecasts with covariates, on the CPU |
| free-splatter.cpp | Pose-free 3D reconstruction (FreeSplatter): turns a handful of plain photos into 3D Gaussians, no camera poses or GPU required |
| trellis2.cpp | C++/GGML port of Microsoft TRELLIS.2: single-image to textured 3D mesh (GLB with PBR materials) |
| gem-x.cpp | Live human motion capture with SOMA and SMPL pose streams (CPU/Vulkan) |
| kimodo.cpp | C++/GGML text-to-motion on CPU and Vulkan, exported as animated skeleton GLB |
| privacy-filter.cpp | Standalone GGML PII/NER token-classification engine powering LocalAI's PII redaction tier |
| LocalVQE | Joint acoustic echo cancellation, noise suppression, and dereverberation |
| local-store | Local-first vector database for embeddings (shipped in-tree) |
We also maintain apex-quant, a per-tensor, per-layer quantization recipe for Mixture-of-Experts models that exploits their structural sparsity to produce GGUFs matching or beating Q8_0 quality - and they run out of the box on stock llama.cpp.
Resources
- Documentation
- LLM fine-tuning guide
- Build from source
- Kubernetes installation
- Integrations & community projects
- Installation video walkthrough
- Blog: release write-ups, benchmarks and engineering notes
- Examples — including the realtime voice assistant demo (Go client for the Realtime API with tool calling)
Team
LocalAI is maintained by a small team of humans, together with the wider community of contributors.
- Ettore Di Giacinto — original author and project lead
- Richard Palethorpe — maintainer
A huge thank you to everyone who contributes code, reviews PRs, files issues, and helps users in Discord — LocalAI is a community-driven project and wouldn't exist without you. See the full contributors list.
Citation
If you utilize this repository, data in a downstream project, please consider citing it with:
@misc{localai,
  author = {Ettore Di Giacinto},
  title = {LocalAI: The free, Open source OpenAI alternative},
  year = {2023},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/go-skynet/LocalAI}},
Sponsors
Do you find LocalAI useful?
Support the project by becoming a backer or sponsor. Your logo will show up here with a link to your website.
A huge thank you to our generous sponsors who support this project covering CI expenses, and our Sponsor list:
Past sponsors
Individual sponsors
A special thanks to individual sponsors, a full list is on GitHub and buymeacoffee. Special shout out to drikster80 for being generous. Thank you everyone!
License
LocalAI is a community-driven project created by Ettore Di Giacinto and maintained by the LocalAI team.
MIT - Author Ettore Di Giacinto mudler@localai.io
Acknowledgements
LocalAI couldn't have been built without the help of great software already available from the community. Thank you!
- llama.cpp
- https://github.com/tatsu-lab/stanford_alpaca
- https://github.com/cornelk/llama-go for the initial ideas
- https://github.com/antimatter15/alpaca.cpp
- https://github.com/EdVince/Stable-Diffusion-NCNN
- https://github.com/ggerganov/whisper.cpp
- https://github.com/rhasspy/piper
- exo for the MLX distributed auto-parallel sharding implementation
Contributors
This is a community project, a special thanks to our contributors!
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|