📄 仓库 README
在 GitHub 查看 ↗
A Flexible Framework for Experiencing Cutting-edge LLM Inference/Fine-tune Optimizations
🎯 Overview | 🚀 Inference | 🎓 SFT | 🔥 Citation | 🚀 Roadmap(2026Q2)🎯 Overview
KTransformers is a research project focused on efficient inference and fine-tuning of large language models through CPU-GPU heterogeneous computing. The project now exposes two user-facing capabilities from the kt-kernel source tree: Inference and SFT.
🔥 Updates
- Oct 15, 2026: DeepSeek-V4-Flash LoRA fine-tuning supports native MXFP4 routed experts. quickstart.
- Oct 8, 2026: We release the author preprint of KTransformers-FineTune (KT-FT), presenting layout-aware and schedule-optimized CPU-GPU co-computation for MoE fine-tuning. Paper and citation · PDF.
- Sep 13, 2026: Kimi K2.5 / K2.6 LoRA fine-tuning is supported with native RAWINT4 routed experts.
- Aug 26, 2026: Added native support for GLM-5.3-flash, bringing 1M-token context and multimodal input to consumer GPUs. (Tutorial)
- Aug 25, 2026: Uploaded a new easy-to-use KTransformers × LlamaFactory MoE Fine-Tuning Cookbook, covering hardware checks, installation, BF16/FP8/INT8 recipes, LoRA and full fine-tuning, resource planning, and troubleshooting.
- Aug 17, 2026: LoRA fine-tuning now supports compatible AVX512 x86 CPUs, including AMD servers, without requiring AMX. (v0.7.0 Release Notes)
- Aug 16, 2026: DeepSeek-V4-Flash on a single Ascend NPU with CPU expert offload. (Tutorial)
- Aug 5, 2026: Introduced native block-FP8 LoRA fine-tuning (PR #2141)
- July 23, 2026: Added end-to-end BF16 full-parameter fine-tuning for MoE models, including complete checkpoint saving. (PR #2094)
- June 21, 2026: MiniMax-M3 Day0 Support! (Tutorial)
- June 17, 2026: GLM-5.2 Day0 Support! (Tutorial)
- May 6, 2026: KTransformers at GOSIM Paris 2026 — "Agentic AI on Edge" track. We'll present KT's inference performance on consumer hardware.
- May 02, 2026: DeepSeek-V4-Flash Support! (Tutorial)
- Apr 30, 2026: KTransformers v0.6.1 refreshes kt-kernel inference and SFT docs with separate Inference and SFT Quick Start entry points.
- Mar 26, 2026: Support AVX2-only CPU backend for KT-Kernel inference. (Tutorial)
- Feb 13, 2026: MiniMax-M2.5 Day0 Support! (Tutorial)
- Feb 12, 2026: GLM-5 Day0 Support! (Tutorial)
- Jan 27, 2026: Kimi-K2.5 Day0 Support! (Tutorial) (SFT Tutorial)
- Jan 22, 2026: Support CPU-GPU Expert Scheduling, Native BF16 and FP8 per channel Precision and AutoDL unified fine-tuning and inference
- Dec 24, 2025: Support Native MiniMax-M2.1 inference. (Tutorial)
- Dec 22, 2025: Support RL-DPO fine-tuning with LLaMA-Factory. (Tutorial)
- Dec 5, 2025: Support Native Kimi-K2-Thinking inference (Tutorial)
- Nov 6, 2025: Support Kimi-K2-Thinking inference (Tutorial) and fine-tune (Tutorial)
- Nov 4, 2025: KTransformers Fine-Tuning × LLaMA-Factory Integration. (Tutorial)
- Oct 27, 2025: Support Ascend NPU. (Tutorial)
- Oct 10, 2025: Integrating into SGLang. (Roadmap, Blog)
- Sept 11, 2025: Support Qwen3-Next. (Tutorial)
- Sept 05, 2025: Support Kimi-K2-0905. (Tutorial)
- July 26, 2025: Support SmallThinker and GLM4-MoE. (Tutorial)
- July 11, 2025: Support Kimi-K2. (Tutorial)
- June 30, 2025: Support 3-layer (GPU-CPU-Disk) prefix cache reuse.
- May 14, 2025: Support Intel Arc GPU (Tutorial).
- Apr 29, 2025: Support AMX-Int8、 AMX-BF16 and Qwen3MoE (Tutorial)
- Apr 9, 2025: Experimental support for LLaMA 4 models (Tutorial).
- Apr 2, 2025: Support Multi-concurrency. (Tutorial).
- Mar 15, 2025: Support ROCm on AMD GPU (Tutorial).
- Mar 5, 2025: Support unsloth 1.58/2.51 bits weights and IQ1_S/FP8 hybrid weights. Support 139K Longer Context for DeepSeek-V3 and R1 in 24GB VRAM.
- Feb 25, 2025: Support FP8 GPU kernel for DeepSeek-V3 and R1; Longer Context.
- Feb 15, 2025: Longer Context (from 4K to 8K for 24GB VRAM) & Slightly Faster Speed (+15%, up to 16 Tokens/s), update docs and online books.
- Feb 10, 2025: Support Deepseek-R1 and V3 on single (24GB VRAM)/multi gpu and 382G DRAM, up to 3~28x speedup. For detailed show case and reproduction tutorial, see here.
- Aug 28, 2024: Decrease DeepseekV2's required VRAM from 21G to 11G.
- Aug 15, 2024: Update detailed tutorial for injection and multi-GPU.
- Aug 14, 2024: Support llamfile as linear backend.
- Aug 12, 2024: Support multiple GPU; Support new model: mixtral 8*7B and 8*22B; Support q2k, q3k, q5k dequant on gpu.
- Aug 9, 2024: Support windows native.
📦 Capabilities
🚀 Inference - High-Performance kt-kernel Serving
CPU-optimized kernel operations for heterogeneous LLM inference.
Key Features: - AMX/AVX Acceleration: Intel AMX and AVX512/AVX2 optimized kernels for INT4/INT8 quantized inference - MoE Optimization: Efficient Mixture-of-Experts inference with NUMA-aware memory management - Quantization Support: CPU-side INT4/INT8 quantized weights, GPU-side GPTQ support - Easy Integration: Clean Python API for SGLang and other frameworks
Quick Start:
cd kt-kernel
pip install .
Use Cases:
- CPU-GPU hybrid inference for large MoE models
- Integration with SGLang for production serving
- Heterogeneous expert placement (hot experts on GPU, cold experts on CPU)
Performance Examples: | Model | Hardware Configuration | Total Throughput | Output Throughput | |-------|------------------------|------------------|-------------------| | DeepSeek-R1-0528 (FP8) | 8×L20 GPU + Xeon Gold 6454S | 227.85 tokens/s | 87.58 tokens/s (8-way concurrency) |
🎓 SFT - Fine-Tuning with LlamaFactory
Research paper: KTransformers-FineTune (KT-FT) · PDF.
KTransformers × LlamaFactory integration for ultra-large MoE model fine-tuning. The new Cookbook provides an easy-to-use path from hardware checks and installation to BF16/FP8/INT8 configuration, LoRA/full training, resource planning, and troubleshooting.
Kimi K2.5 / K2.6 LoRA fine-tuning is supported with native RAWINT4 routed experts. Follow the PyPI installation, training, resume and SGLang serving guide (中文). End-to-end validation uses Kimi K2.5; K2.6 follows the same model-architecture path.
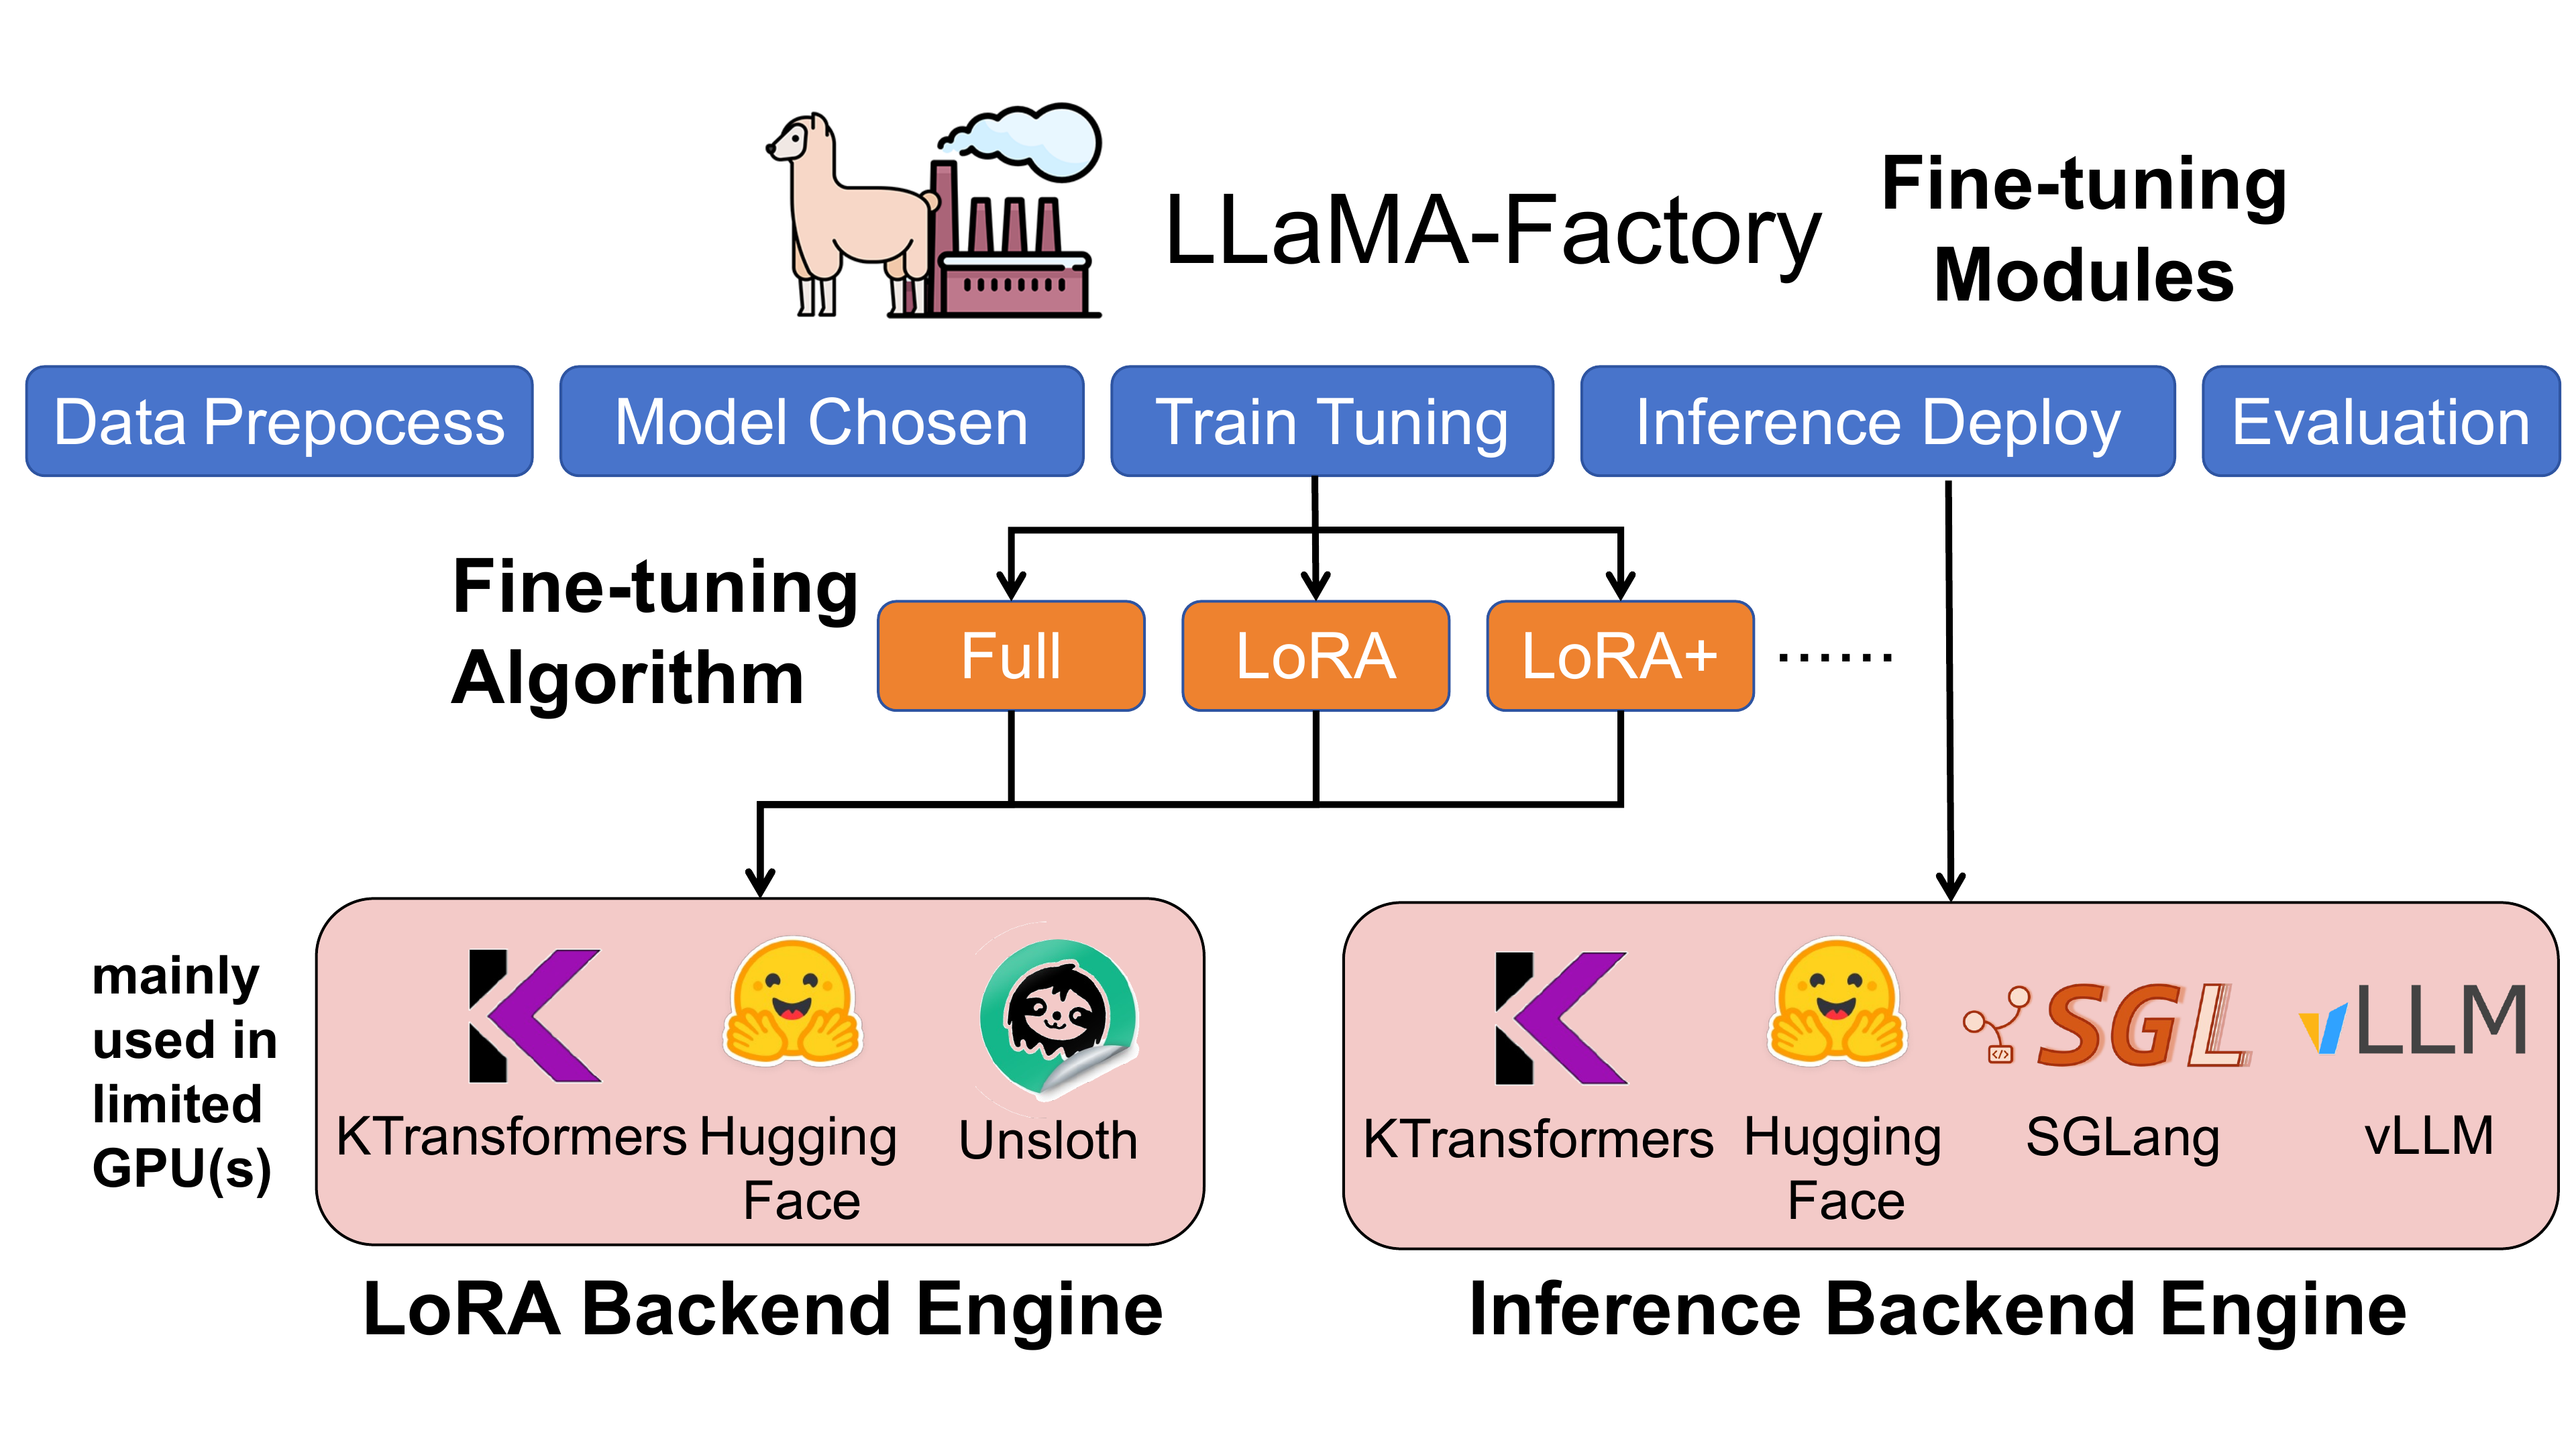
Key Features: - Multi-Backend Support: CPU/GPU hybrid fine-tuning with INT8/INT4 quantization - Ultra-Large MoE Support: Fine-tune models like DeepSeek-V3/R1 on limited GPU memory - Faster than ZeRO-Offload: 6-12x training speedup in benchmarked MoE SFT workloads - Lower CPU Memory: About half the CPU memory of the previous KT SFT path in the benchmarked setup - LlamaFactory Integration: Seamless integration with the popular fine-tuning framework
| Model | GPU Memory | Training Speed | Hardware |
|---|---|---|---|
| DeepSeek-V3 | ~80GB total | 3.7 it/s | 4x RTX 4090 |
| DeepSeek-R1 | ~80GB total | 3.7 it/s | 4x RTX 4090 |
| Qwen3-30B-A3B | ~24GB total | 8+ it/s | 1x RTX 4090 |
Quick Start:
cd /path/to/LLaMA-Factory
python -m pip install -e .
python -m pip install "ktransformers[sft]==0.7.0"
python -m pip install "sglang-kt==0.7.0"
CUDA_VISIBLE_DEVICES=0,1,2,3 accelerate launch \
  --config_file examples/ktransformers/accelerate/fsdp2_kt_int8.yaml \
  src/train.py \
  examples/ktransformers/train_lora/qwen3_5moe_lora_sft_kt.yaml
👉 Easy-to-Use Fine-Tuning Cookbook → 👉 Quick Start → 👉 Full Documentation →
🔥 Citation
If you use KTransformers in your research, please cite the relevant paper.
Inference paper
@inproceedings{10.1145/3731569.3764843,
  title = {KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models},
  author = {Chen, Hongtao and Xie, Weiyu and Zhang, Boxin and Tang, Jingqi and Wang, Jiahao and Dong, Jianwei and Chen, Shaoyuan and Yuan, Ziwei and Lin, Chen and Qiu, Chengyu and Zhu, Yuening and Ou, Qingliang and Liao, Jiaqi and Chen, Xianglin and Ai, Zhiyuan and Wu, Yongwei and Zhang, Mingxing},
  booktitle = {Proceedings of the ACM SIGOPS 31st Symposium on Operating Systems Principles},
  year = {2025}
}
Fine-tuning paper
KTransformers-FineTune (KT-FT) · Full BibTeX
@misc{li2026ktft,
  title = {{KTransformers-FineTune: Beyond Offload with Layout-Aware and Schedule-Optimized Heterogeneous MoE Fine-Tuning}},
  author = {Li, Peilin and Hao, Xingxing and Chen, Hongtao and Xie, Weiyu and Zheng, Yaowei and Wu, Bowen and Yang, Yujie and Shen, Huanming and Ou, Qingliang and Zhang, Boxin and Tang, Jingqi and Yuan, Ziwei and Dong, Jianwei and Kuang, Dongdong and Feng, Zhangchi and Dai, Jiaheng and Yang, Qianrui and Chen, Shaoyuan and Wang, Jiahao and Han, Yaochen and Zhu, Yuening and Liao, Jiaqi and Chen, Xianglin and Ai, Zhiyuan and Wu, Yongwei and Zhang, Mingxing},
  year = {2026},
  note = {Author preprint, version paper-ktft-v1.1},
  howpublished = {Author preprint, GitHub},
  url = {https://github.com/kvcache-ai/ktransformers/tree/paper-ktft-v1.1/papers/kt-ft}
}
👥 Contributors & Team
Developed and maintained by: - MADSys Lab @ Tsinghua University - Approaching.AI - 9#AISoft - Community contributors
We welcome contributions! Please feel free to submit issues and pull requests.
💬 Community & Support
- GitHub Issues: Report bugs or request features
- WeChat Group: See archive/WeChatGroup.png

📦 KT original Code
The original integrated KTransformers framework has been archived to the archive/ directory for reference. The project now organizes the two capabilities above from the kt-kernel source tree for clearer documentation and maintenance.
For the original documentation with full quick-start guides and examples, see: - archive/README.md (English) - archive/README_ZH.md (中文)
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|