📄 仓库 README
在 GitHub 查看 ↗treehouse


Manage worktrees without managing worktrees.
Are you still only working on one task at a time? Are you manually juggling between a few clones of the same repo?
Or... are you starting a new worktree for every agent session, losing all your installed dependencies and build cache each time, and wondering why your agents are slow?
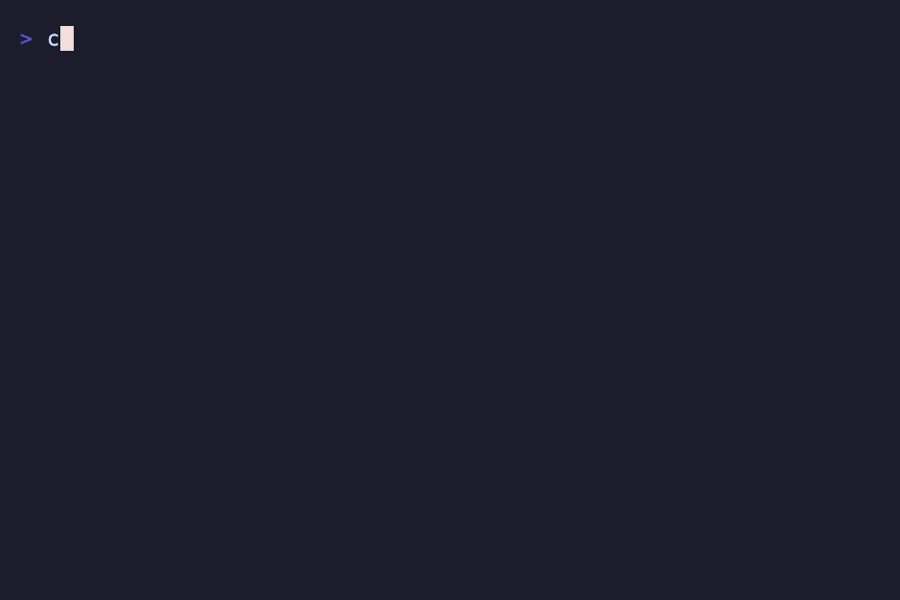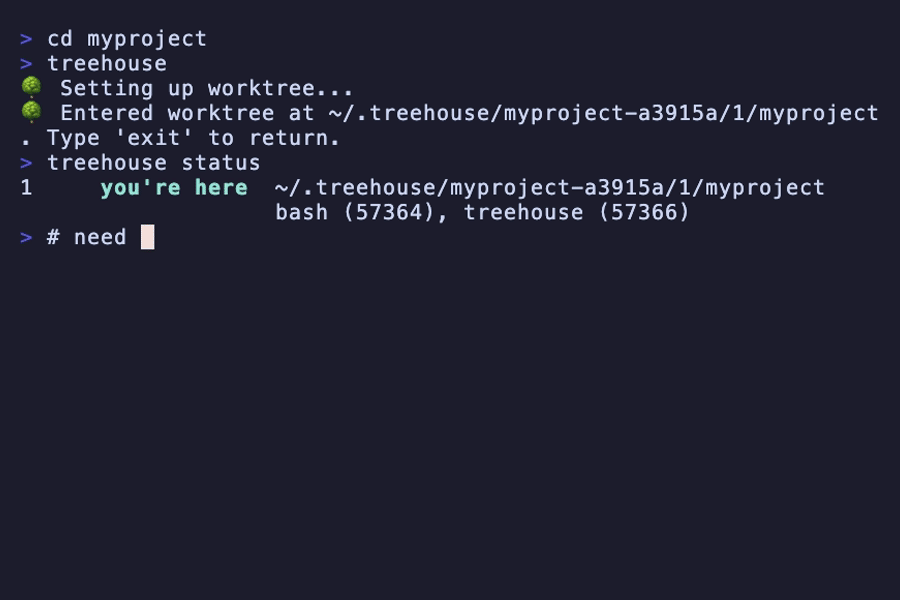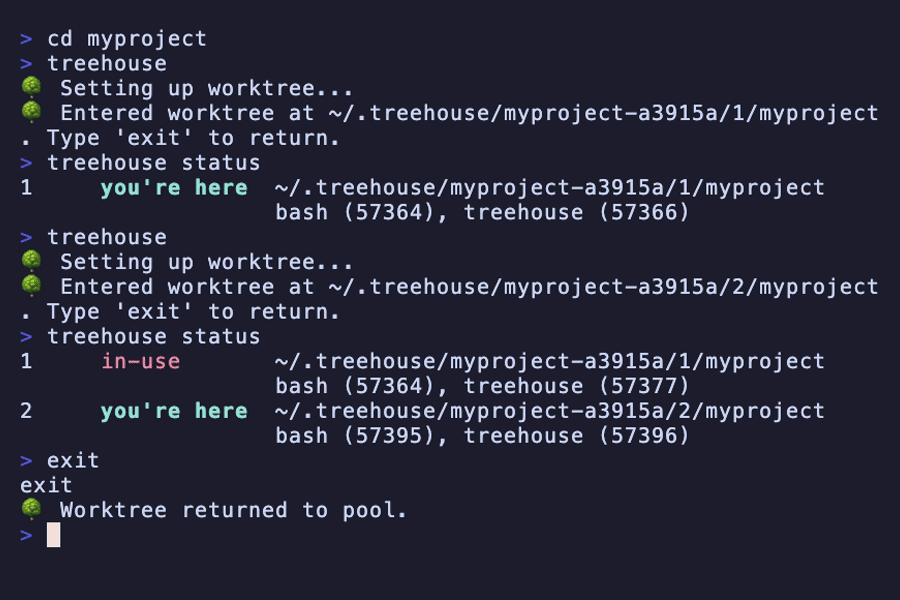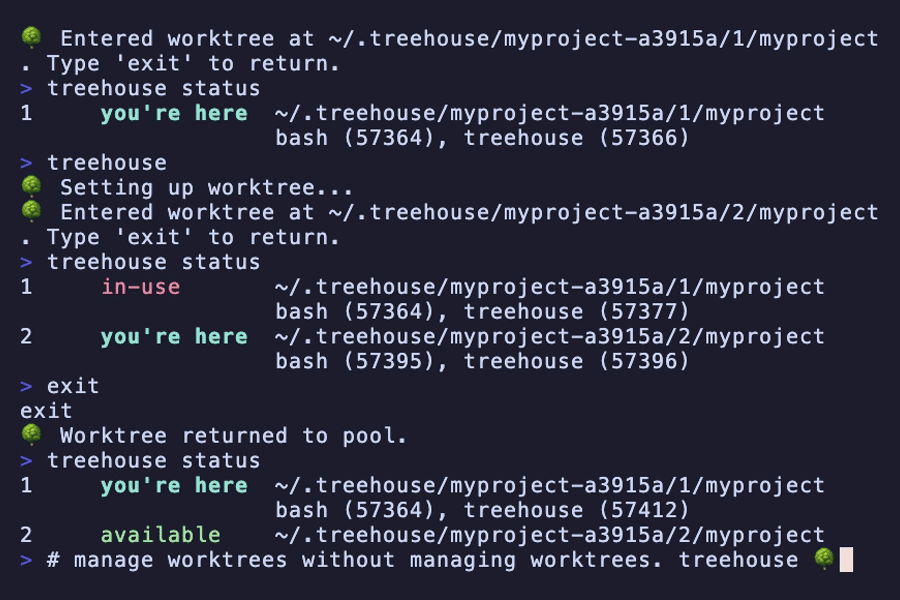
Treehouse helps you manage a pool of reusable, isolated worktrees so each of your agents gets its own environment instantly — no cloning, no conflicts, no coordination overhead.
- Instant isolation —
treehouseputs you into a clean worktree with zero hassel. - Reusable worktrees — worktrees are preserved in a pool when you're done, with dependencies and build cache intact, ready for the next agent.
- Conflict-free — automatic detection of in-use worktrees and your agents never step on each other's toes.
Quick Start
$ cd myproject                 # start in your repo as usual
$ treehouse                    # get a worktree and drop into a subshell
🌳 Entered worktree at ~/.treehouse/myproject-a1b2c3/1/myproject. Type 'exit' to return.

# You're now in an isolated worktree.
# Run your AI agent, make changes, do whatever you need.

$ exit                         # exit the subshell when you're done
🌳 Terminated lingering processes: opencode (pid 12345)
🌳 Worktree returned to pool.
Install
macOS / Linux
curl -fsSL https://kunchenguid.github.io/treehouse/install.sh | sh
Windows (PowerShell)
irm https://kunchenguid.github.io/treehouse/install.ps1 | iex
Nix
nix run github:kunchenguid/treehouse
# or pin a specific release tag:
nix run github:kunchenguid/treehouse/v3.1.2
Install into your Nix profile:
nix profile add github:kunchenguid/treehouse
Or add to your flake inputs:
treehouse = {
  url = "github:kunchenguid/treehouse";
  inputs.nixpkgs.follows = "nixpkgs";
};
The flake exposes #default and #treehouse package outputs, plus apps for nix run.
A Nix install upgrades through Nix: treehouse update refuses to run from the Nix store and the update notice stays silent there.
Go
go install github.com/kunchenguid/treehouse/v3@latest
From source
git clone https://github.com/kunchenguid/treehouse.git
cd treehouse
make install
How It Works
Treehouse manages a pool of git worktrees per repository, stored under the configured treehouse root.
The default treehouse root is ~/.treehouse/.
You can instead keep the pool inside the project with --root ., so it lives next to the code and is removed with the project.
  treehouse
      │
      ▼
  Find repo root
      │
      ▼
  git fetch origin
      │
      ▼
  ┌──────────────────────────────────────────────────────┐
  │  Scan pool for a safely reusable worktree            │
  │  (this clone's, idle, unleased, clean, and HEAD      │
  │  merged into the exact reset target; skip if safety  │
  │  or clone ownership is unprovable)                   │
  └──────────┬───────────────────────────────────────────┘
             │
        ┌────┴────┐
        │  Found? │
        └────┬────┘
         yes/ \no
           /   \
          ▼     ▼
   Reset to   Create new worktree
   latest     (detached HEAD at
   default    latest default
   branch     branch)
              & add to pool
          \   /
           \ /
            ▼
  Spawn subshell in worktree
  (agent works here)
           │
           ▼
     exit subshell
           │
           ▼
  Terminate lingering worktree
  processes and verify none remain
           │
           ▼
  Reset worktree & return to pool
  (ready for next agent)
- Detached HEAD by default — without
-b/--branch, worktrees use detached HEAD mode and reset to whichever of the local or remote default branch is further ahead. Passtreehouse get -b <name>to create and check out a new local Git branch at the acquired commit. See Base branch for base selection and branch-creation details. - Choosable base branch — set
base_branchintreehouse.toml, or passtreehouse get --base <branch>, to cut worktrees from a branch other than the repository default. Opt-in; unset keeps today's inference. This composes with--branch: the new branch starts at the selected base. - Unique worktree directory names — pass
treehouse get --unique-leaf(or setunique_leafintreehouse.toml) to name new slots<repo>-<slot>instead of<repo>, so tooling that derives per-checkout identity from the directory name tells the slots apart. Opt-in; off keeps today's layout, and existing worktrees are never moved. - Choosable worktree path — set
worktree_pathintreehouse.toml, or passtreehouse get --worktree-path '<template>', to place new worktrees somewhere a tool requires instead of{pool}/{slot}/{repo}. Opt-in, and creation-only: worktrees already in the pool keep their recorded paths. See Worktree path. - Clone-correct reuse — two local clones of the same remote share one pool, but a worktree is only ever reused by the clone it belongs to, judged by its physical Git common directory (symlinked or, on a case-insensitive filesystem, differently cased paths to one clone count as that clone). Another clone's idle worktree is skipped and left intact; if nothing reusable is left,
getcreates a new worktree up tomax_treesand otherwise fails with a message counting the foreign and unverifiable worktrees. A worktree whose owning clone cannot be proven is never reused, and neither is any worktree when the requesting clone's own identity cannot be proven. Non-colocated jj repositories have no Git common directory, so their worktrees are never reused;getcreates a new one each time untilmax_treesis reached. - Opt-in APFS sharing - share identical large tracked files with the main checkout using independent copy-on-write clones. Default off, macOS/APFS and fresh Git slots only; existing slots and ignored output are never swept. See APFS copy-on-write sharing.
- No daemon - all operations are inline CLI commands. Pool state is a small on-disk file, written under a lock by each command.
- Interactive shell setup — when opening a subshell on macOS or Linux,
treehouse,treehouse get, andtreehouse enterstart$SHELLas an interactive login shell when it resolves tobash,fish, orzsh. Other shells, fallback shells, and Windows use their default invocation. A regular executable that is merely named like a supported shell but does not accept-i -l(for example a wrapper script at/opt/tools/bash) is an accepted limitation: the resolved basename is the contract, and PATH-identity probing would reject genuine second installs of the same shell. - In-use detection — treehouse scans running processes and short-lived owner reservations to determine which worktrees are in-use. Reservations are persisted only while
get,destroy, andprunelifecycle work is running. - Durable leases -
treehouse get --leasereserves a worktree as a persistent home without keeping a process inside it. Each acquisition gets an immutable random lease identity, and the lease is recorded in treehouse's own state. An ordinary lease keeps the worktree out of latergetandpruneuntil you release it withtreehouse return. Unlike process-based in-use detection, it survives with zero processes running inside the worktree; recovered leases follow the state recovery policy. - State recovery - treehouse writes pool state atomically via a temp file and replacement. If an existing state file is empty, truncated, or omits an on-disk worktree, treehouse rebuilds the missing entries. See Recovering missing pool state for automatic recovery and handling slots that remain quarantined.
- Gitignored file seeding — commit a
.worktreeincludefile for the default selection, or passget --include-file <path>for a personal manifest. Selected local files are copied from the main checkout on each acquire. See Seeding gitignored files. - Dirty detection - treehouse treats tracked changes and untracked files as dirty, even when repository config hides untracked files from normal
git statusoutput. - Safe pruning - By default,
treehouse pruneremoves only clean, idle managed worktrees with landed HEAD commits. See Base branch for the merge rule.treehouse prune --allapplies the same safety checks across every managed pool under the user-level treehouse root. Backing-repository-missing orphans are reported by default;--prune-orphansincludes them as unverified prune candidates, and--yesis required before deletion. It is a dry run unless you pass--yes. - Self-healing get -
treehouse getclears stale git worktree bookkeeping for the exact path it is about to create (e.g. left behind by a crashed or forcibly removed worktree), so a prunable registration never wedges the pool with a "missing but already registered worktree" error. Registrations for other paths are never touched, so a live worktree that the caller cannot see (for example under another account's private pool root) is never deregistered.
CLI Reference
| Command | Description |
|---|---|
treehouse |
Get a worktree and open a subshell (alias for get) |
treehouse get |
Acquire a worktree from the pool |
treehouse get --lease |
Durably lease a worktree withou |
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|