📄 仓库 README
在 GitHub 查看 ↗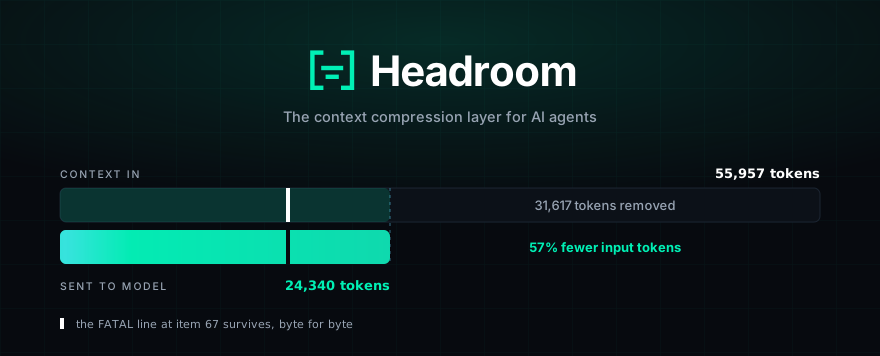



Quickstart · Headroom for Teams · Install · Proof · Agents · Docs · Discord · llms.txt
AI agents / LLMs: read/llms.txt here, or fetch
the live index ·
full docs blob.
Headroom compresses everything your AI agent reads — tool outputs, logs, RAG chunks, files, and conversation history — before it reaches the LLM. Same answers, fraction of the tokens. Compression runs on your machine; no prompt or file content is sent anywhere to be compressed.
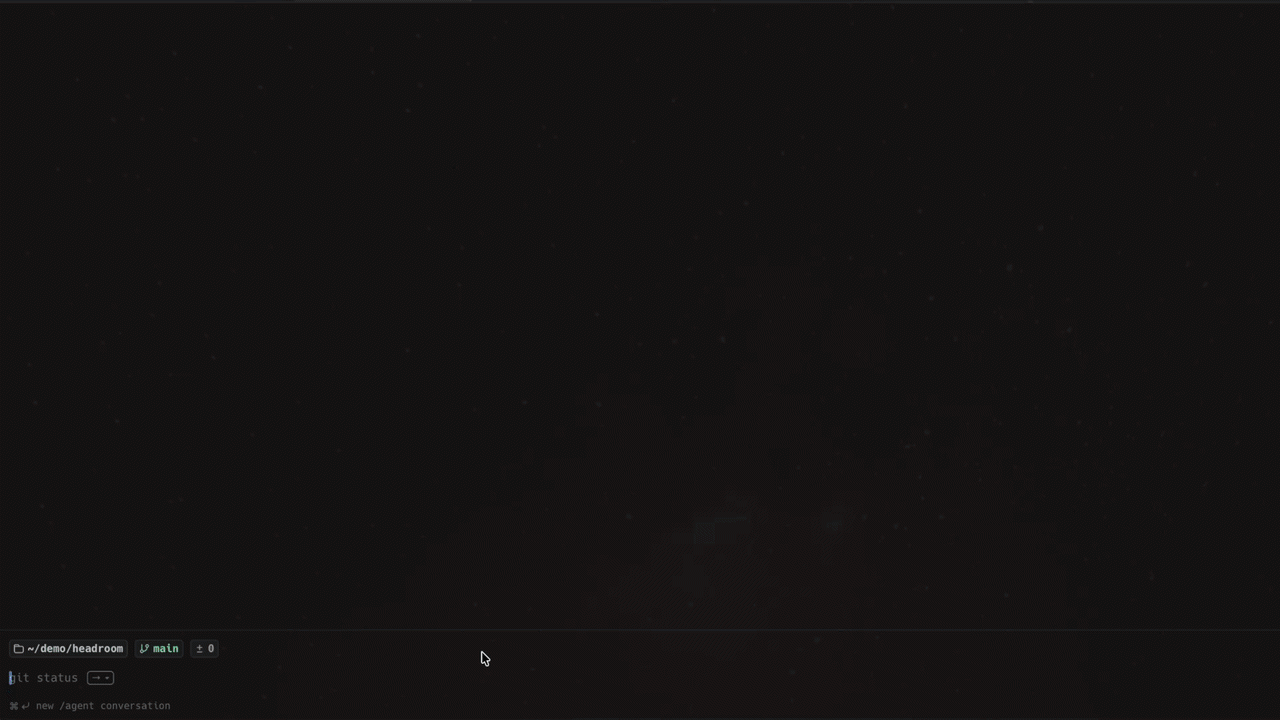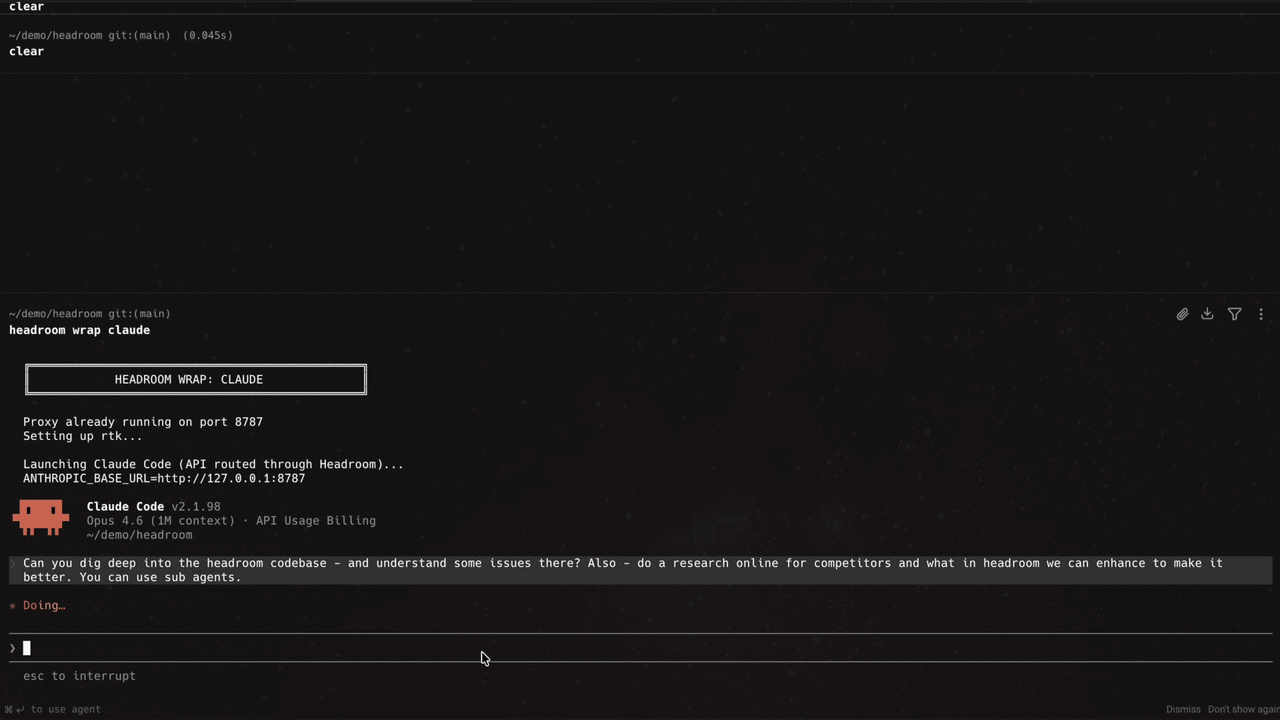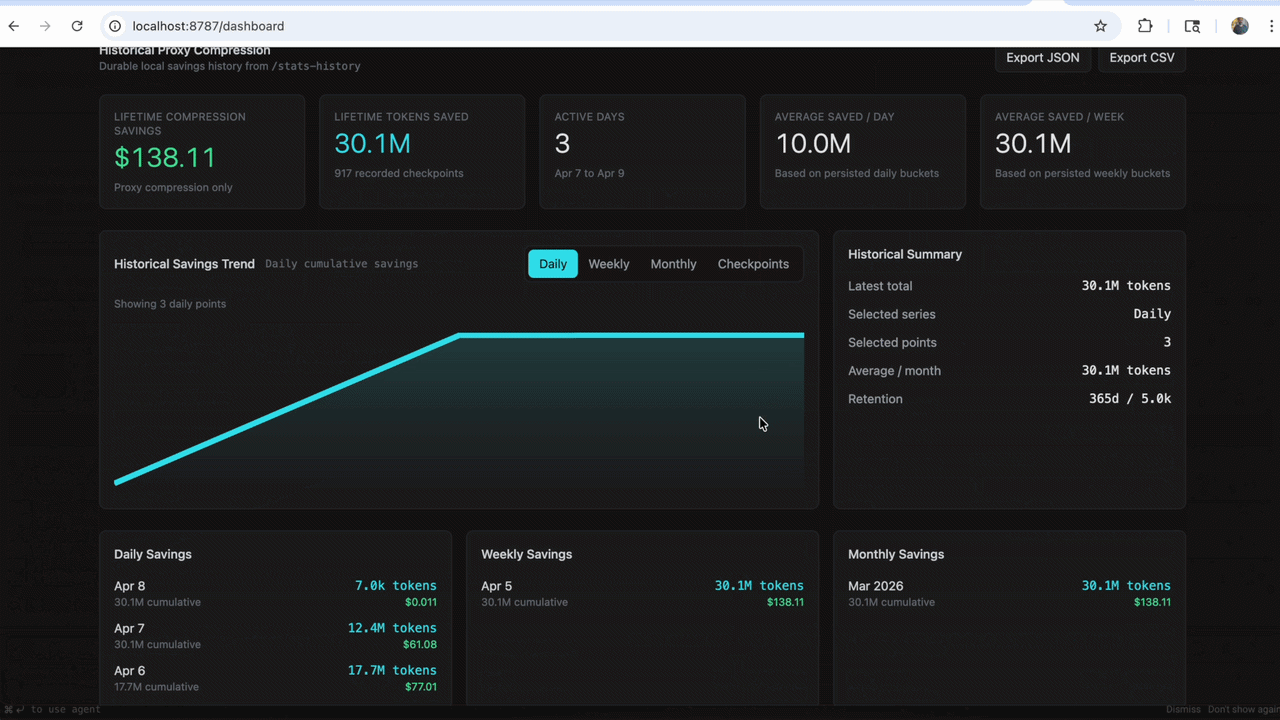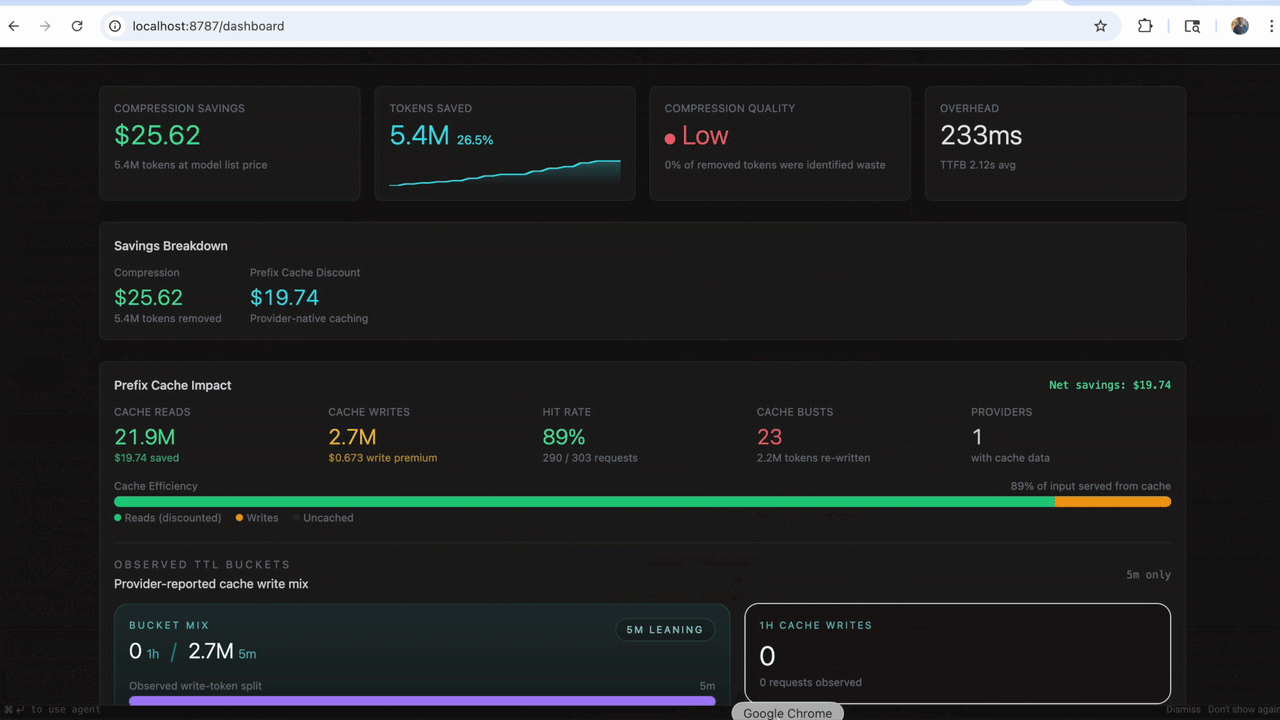
10,144 → 1,260 tokens. The same
FATAL found.
What it does
- Library —
compress(messages)in Python or TypeScript, inline in any app. - Proxy —
headroom proxy --port 8787, zero code changes, any language. - Agent wrap —
headroom wrap claude|codex|grok|copilot|cursor|aider|opencode|cline|continue|goose|openhands|openclaw|vibe|omp|zcodein one command; undo withheadroom unwrap <tool>. - MCP server —
headroom_compress,headroom_retrieve,headroom_statsfor any MCP client. - Cross-agent memory — one shared store across Claude, Codex, Gemini and Grok, with automatic dedup.
headroom learn— mines failed sessions and writes corrections toCLAUDE.local.md(default, gitignored),CLAUDE.md,AGENTS.md,GEMINI.mdorGROK.md.- Output token reduction — trims what the model writes back, not only what you send. See below.
- Reversible (CCR) — originals are cached locally and retrieved on demand.
How it works
 Your agent / app
   (Claude Code, Cursor, Codex, LangChain, Agno, Strands, your own code…)
        │   prompts · tool outputs · logs · RAG results · files
        ▼
    ┌────────────────────────────────────────────────────┐
    │  Headroom   (runs locally — your data stays here)  │
    │  ────────────────────────────────────────────────  │
    │  CacheAligner  →  ContentRouter  →  CCR            │
    │                    ├─ SmartCrusher   (JSON)        │
    │                    ├─ CodeCompressor (AST)         │
    │                    └─ Kompress-v2-base (text, HF)  │
    │                                                    │
    │  Cross-agent memory  ·  headroom learn  ·  MCP     │
    └────────────────────────────────────────────────────┘
        │   compressed prompt  +  retrieval tool
        ▼
 LLM provider  (Anthropic · OpenAI · Bedrock · …)
- ContentRouter detects the content type and selects a compressor for it.
- SmartCrusher / CodeCompressor / Kompress-v2-base handle JSON, source code and prose respectively.
- CacheAligner flags volatile content that would bust a provider KV-cache prefix. It never rewrites prompts.
- CCR stores originals locally so the model can call
headroom_retrievewhen it needs the full text.
→ Architecture · CCR · Kompress-v2-base model card
Get started (60 seconds)
# 1 — Install
uv tool install --python 3.13 "headroom-ai[all]"  # CLI in a self-contained env
pip install "headroom-ai[all]"                    # Python — ships the `headroom` CLI
npm install headroom-ai                           # TypeScript SDK only — no CLI

# 2 — Pick a mode
headroom deploy                         # turnkey local deployment + agent config
headroom wrap claude                    # wrap a coding agent
headroom proxy --port 8787              # drop-in proxy, zero code changes
# or: from headroom import compress     # inline library

# 3 — Check it and watch the savings
headroom doctor                         # health check — confirms routing works
headroom perf
headroom dashboard                      # live savings (proxy must be running)
Inline, in Python:
from headroom import compress
from openai import OpenAI

messages = [{"role": "user", "content": "Analyze these results"}]
result = compress(messages, model="gpt-4o")

client = OpenAI()
response = client.chat.completions.create(model="gpt-4o", messages=result.messages)
print(f"Saved {result.tokens_saved} tokens ({result.compression_ratio:.0%})")
Launch a wrapped agent session each time, so the setup runs. headroom wrap
starts a local proxy, installs Serena for
semantic code navigation, and launches the agent configured to route through
Headroom. For Claude Code, Serena is registered for the wrapped project only
(as a local-scope MCP server in ~/.claude.json). Use
--code-memory-scope user to make it available in every project, or
--code-memory none to skip it. headroom unwrap removes either registration.
The headroom CLI ships only in the PyPI package. The npm headroom-ai package
is the TypeScript SDK — a library you import
(import { compress } from 'headroom-ai') — and provides no headroom command.
Proof
Four scenarios built from real MCP server output formats, measured with the
provider tokenizer and the shipped compress(). Seeded and offline, so you get
the same numbers we did:
uv run python benchmarks/index_proof_table.py --seed 20260902
| Scenario | Before | After | Saved |
|---|---|---|---|
| Code search (100 results) | 17,199 | 13,597 | 21% |
| SRE incident debugging | 55,957 | 24,340 | 57% |
| Codebase exploration | 58,801 | 33,895 | 42% |
| GitHub issue triage | 46,067 | 32,429 | 30% |
Savings scale with how repetitive the payload is. Repeated JSON arrays and log
lines clear 90% in benchmarks/bench_latency.py; prose and already-dense output
compress very little. Run headroom savings against your own traffic for the
number that applies to you.
Compression costs well under a millisecond — 0.21 ms p50 on a 10K-token JSON search result, 1.4 ms at 100K tokens — so it does not show up in agent latency.
Accuracy. python -m headroom.evals suite --tier 1:
| Benchmark | Category | N | Baseline | Headroom | Delta |
|---|---|---|---|---|---|
| GSM8K | Math | 100 | 0.870 | 0.870 | ±0.000 |
| TruthfulQA | Factual | 100 | 0.530 | 0.560 | +0.030 |
| SQuAD v2 | QA | 100 | — | 97% | at 19% compression |
| BFCL | Tools | 100 | — | 97% | at 32% compression |
At N=100 a delta of ±0.03 falls inside the confidence interval, so TruthfulQA shows no detectable difference rather than an improvement. Methodology →
Output token reduction
Everything above shrinks the prompt you send. You also pay for every token the model writes back, and on Opus-class models output costs 5× input. Much of that output is ceremony: "Great, let me…" preambles, code re-printed straight back at you, and deep reasoning spent on routine steps like reading a file.
Headroom trims it from the proxy, with no change to your code:
- Verbosity steering appends a short "be terse, don't restate context" note to the end of the system prompt, so your prompt cache still hits.
It applies to Anthropic /v1/messages and to OpenAI-compatible
/v1/chat/completions and /v1/responses, with the same output_shaper:*
labels on all paths.
export HEADROOM_OUTPUT_SHAPER=1     # off by default
headroom proxy --port 8787
Already running a proxy? These switches are read live on every request, so a proxy that
headroom wrapreused rather than started would not see a value you export afterwards — its environment was snapshotted at launch.headroom wraphot-syncs your current settings to the running proxy over a loopbackPOST /admin/runtime-env, so they take effect with no restart and no dropped requests. On a shared proxy these overrides are global; the last explicit setting wins.
Terseness you didn't have to configure. People rarely state how terse they
want answers — they show it, by interrupting long replies or moving on before
they could have read them. headroom learn --verbosity reads past sessions and
pi
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|