📄 仓库 README
在 GitHub 查看 ↗
Obsidian Mind



An Obsidian vault that gives AI coding agents persistent memory. Built for Claude Code, with working hooks for Codex CLI and Gemini CLI. Start a session, talk about your day, and the agent handles the rest — notes, links, indexes, performance tracking. Every conversation builds on the last.
🔴 The Problem
AI coding agents are powerful, but they forget. Every session starts from zero — no context on your goals, your team, your patterns, your wins. You re-explain the same things. You lose decisions made three conversations ago. The knowledge never compounds.
🟢 The Solution
Give your agent a brain.
You: "start session"
Agent: *reads North Star, checks active projects, scans recent memories*
Agent: "You're working on Project Alpha, blocked on the BE contract.
        Last session you decided to split the coordinator. Your 1:1
        with your manager is tomorrow — review brief is ready."
Works with Claude Code (full support), Codex CLI, and Gemini CLI — same hooks, same commands, same vault.
Install via shardmind install or git clone — same vault either way.
⚡ See It In Action
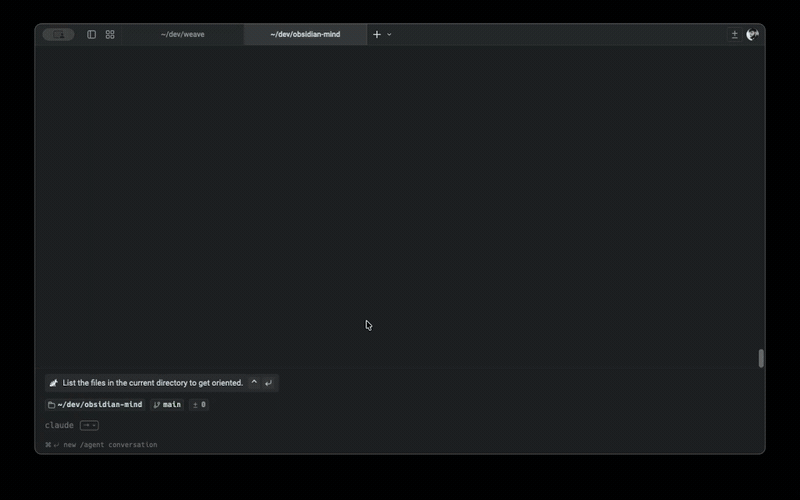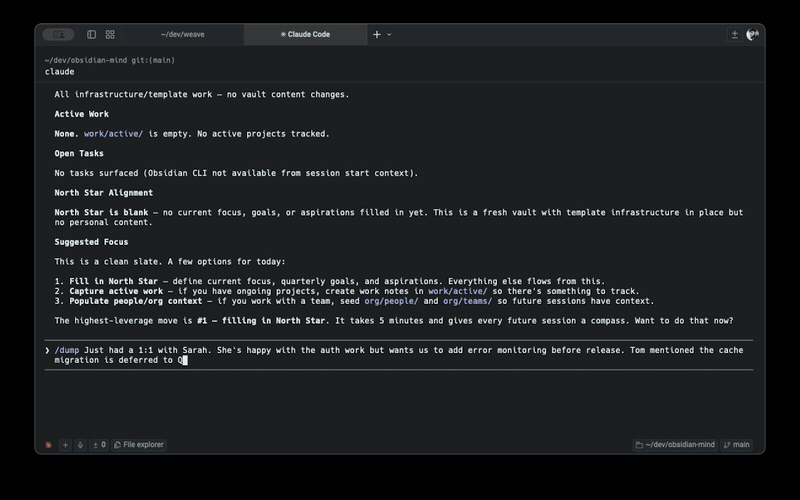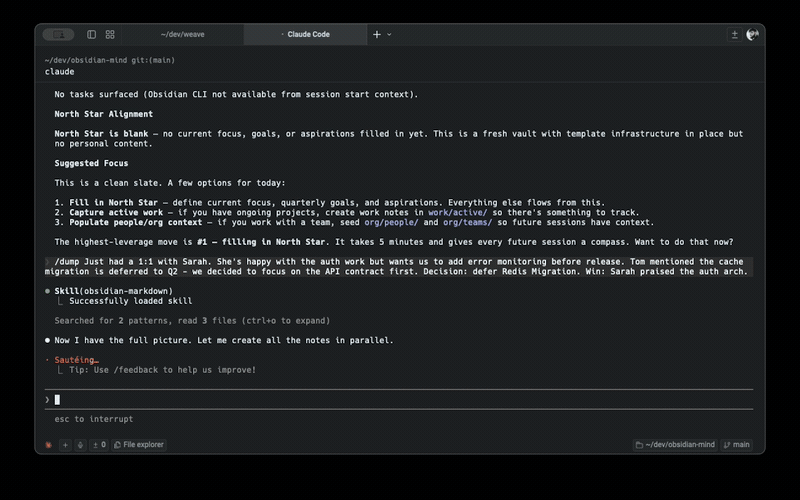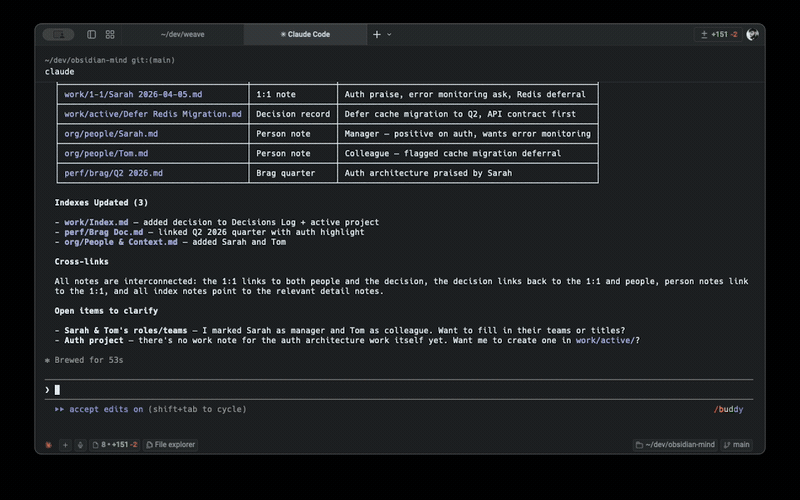
Morning kickoff:
/om-standup
# → loads North Star, active projects, open tasks, recent git changes
# → "You have 2 active projects. The auth refactor is blocked on API contract.
#    Your 1:1 with Sarah is at 2pm — last time she flagged observability."
Brain dump after a meeting:
/om-dump Just had a 1:1 with Sarah. She's happy with the auth work but wants
us to add error monitoring before release. Also, Tom mentioned the cache
migration is deferred to Q2 — we decided to focus on the API contract first.
Decision: defer Redis migration. Win: Sarah praised the auth architecture.
→ Updated org/people/Sarah Chen.md with meeting context
→ Created work/1-1/Sarah 2026-03-26.md with key takeaways
→ Created Decision Record: "Defer Redis migration to Q2"
→ Added to perf/Brag Doc.md: "Auth architecture praised by manager"
→ Updated work/active/Auth Refactor.md with error monitoring task
Incident response:
/om-incident-capture https://slack.com/archives/C0INCIDENT/p123456
# → slack-archaeologist reads every message, thread, and profile
# → people-profiler creates notes for new people involved
# → Full timeline, root cause analysis, brag doc entry
End of day:
You: "wrap up"
# → verifies all notes have links
# → updates indexes
# → brag-spotter finds uncaptured wins
# → suggests improvements
🚀 Quick Start
📦 Install via ShardMind (recommended)
npm install -g shardmind
mkdir my-vault && cd my-vault
shardmind install github:breferrari/obsidian-mind
shardmind install writes into the current directory, so create and enter a fresh folder first. The wizard collects your name, organization, vault purpose, agents to include, and whether to enable QMD; ShardMind then initializes git, optionally bootstraps QMD, and personalizes brain/North Star.md with your answers. Then:
- Open the installed folder as an Obsidian vault
- Enable the Obsidian CLI in Settings → General (requires Obsidian 1.12+)
- Run your agent in the vault directory:
claude,codex, orgemini. Codex runs the vault's hooks only once the folder is trusted and each hook approved: see Using with Other Agents. - Start talking about work
ShardMind is the package manager for Obsidian vault templates. The install adds a .shardmind/ sidecar that powers the wizard, optional modules (skip what you don't use), and three-way-merge upgrades. With every value at its default the install is byte-equivalent to git clone — clone-UX is preserved exactly. Delete .shardmind/ and shard-values.yaml from the installed vault and it keeps working: ShardMind is additive, not load-bearing.
Or clone directly
git clone https://github.com/breferrari/obsidian-mind.git
Or use it as a GitHub template. Skip the wizard, get the bare template. Then run through the same 4 steps above, plus fill in brain/North Star.md with your goals (the ShardMind wizard does this for you).
🔍 Recommended: QMD Semantic Search
QMD is where most of the agent's retrieval intelligence comes from. Optional in the strict sense — the vault falls back to grep + the Obsidian CLI — but the experience is meaningfully better with it:
- Semantic recall. Find "what did we decide about caching" even when the note is titled "Redis Migration ADR."
- Brain topics available on demand. Your agent is instructed (via
AGENTS.md, which points to.claude/rules/brain-topics.md) to consultbrain/guidance through QMD when the conversation touches a listed topic. - Subagents get sharper context.
context-loader,review-prep,brag-spotter, and friends consult QMD first, then fall back to grep. - Native agent tools via MCP. Registered as a Model Context Protocol server in
.mcp.json— when QMD is installed,mcp__qmd__query,mcp__qmd__get, andmcp__qmd__multi_getappear in the agent's tool menu alongside Read and Edit. Subagents, slash commands, and the main conversation all call the same typed contract. Add another MCP-aware tool later (a database, a ticketing system, a calendar) and it plugs in the same way.
npm install -g @tobilu/qmd
node --experimental-strip-types .scripts/qmd-bootstrap.ts
The bootstrap is idempotent — safe to re-run. It resolves this vault's index name — the qmd_index field from vault-manifest.json when set, otherwise the vault folder name slugified — reads qmd_context, registers the collection, attaches the context, and builds the index + embeddings. The SessionStart hook and .mcp.json wrapper both read the same manifest field, so CLI queries, the MCP server, and the re-index all scope to the same named SQLite store. This isolates the vault from any other QMD-using vault on the same machine.
If you want to use a different index name (for example, one vault per engineer on a shared workstation), edit qmd_index in vault-manifest.json before running the bootstrap. Once the store is populated, always pass --index <name> to the CLI:
qmd --index obsidian-mind query "what did we decide about caching"
qmd --index obsidian-mind update   # after bulk edits
qmd --index obsidian-mind embed    # after many new notes
How it works under the hood
QMD runs three small models locally, so there is no API key to set up, no per-query cost, and it works offline:
| model | size | job |
|---|---|---|
embeddinggemma-300M |
~328MB | turns notes and queries into vectors |
qmd-query-expansion-1.7B |
~1.28GB | rewrites your query into better search terms |
Qwen3-Reranker-0.6B |
~640MB | reorders the shortlist by actual relevance |
They download on first use and are cached. QMD offloads to the GPU when it finds one — CUDA on a discrete card, Metal on Apple Silicon — and falls back to CPU otherwise. Check what yours is doing with qmd doctor.
Use qmd 2.5.1 or later. In 2.1, qmd status probes the GPU, and on a machine without one that can take several seconds (4 to 37 s on CI runners, measured 2026-10-13, #349). SessionStart's self-heal reads qmd status under a 5-second limit, so a status that times out leaves it unable to see a broken install.
The three CLI verbs map onto that stack, cheapest first: qmd search is BM25 keywords with no model at all, qmd vsearch is vector-only, and qmd query is the full hybrid. If you want to avoid the larger downloads, search alone is genuinely useful.
What that means for the MCP server
The om server sends a lexical and a vector sub-query, so retrieval finds the note that answers your question even when it shares no keywords with it. Practical consequences worth knowing:
- Reads are the expensive side, not writes. A query embeds locally before it can search, so
recallwith a query takes a couple of seconds whilerecallwithout one is near-instant.searchover notes is fast — it is the vector step that costs. - Writing a memory does not wait for the model. The index update is synchronous, so a new memory is immediately retrievable; generating its vector happens in the background, because that only affects where it ranks, not whether it is found.
- No index, no problem. Without QMD the server falls back to lexical matching. Ordering gets worse; nothing disappears.
[!NOTE] If QMD isn't installed, everything still works — the agent falls back to grep and the Obsidian CLI, and the MCP server entry is skipped with a harmless warning.
📋 Requirements
- Obsidian 1.12+ (for CLI support)
- An AI coding agent: Claude Code (full support), Codex CLI, or Gemini CLI
- Node 22+ LTS (for hook scripts — typically already installed alongside Claude Code / Codex / Gemini CLI)
- Git (for version history)
- QMD (optional, for semantic search)
Note on the Node flag. Hook scripts execute TypeScript di
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|