📄 仓库 README
在 GitHub 查看 ↗
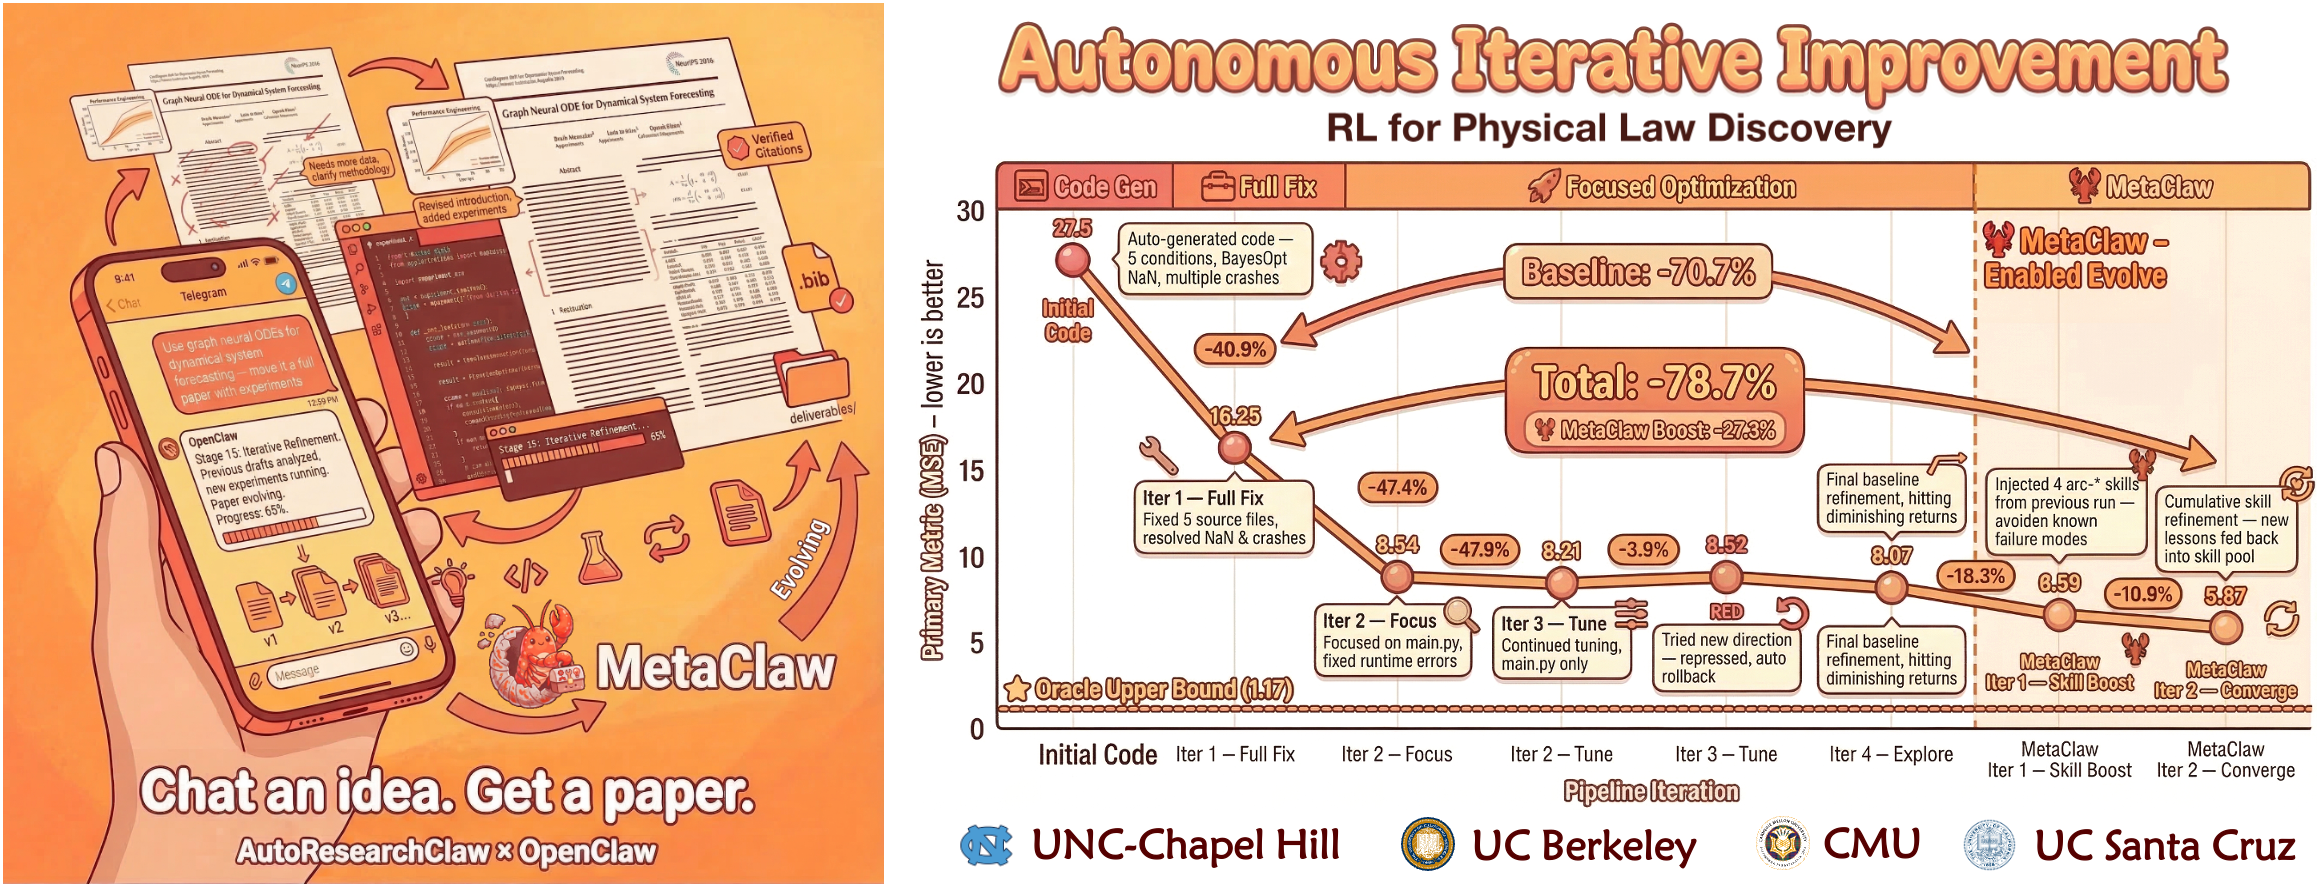
Chat an Idea. Get a Paper. Autonomous, Collaborative & Self-Evolving.
Just chat with OpenClaw: "Research X" → done.
📄 Our paper is on arXiv — come read it! AutoResearchClaw: Self-Reinforcing Autonomous Research with Human-AI Collaboration



🇨🇳 中文 · 🇯🇵 日本語 · 🇰🇷 한국어 · 🇫🇷 Français · 🇩🇪 Deutsch · 🇪🇸 Español · 🇧🇷 Português · 🇷🇺 Русский · 🇸🇦 العربية
🏆 Paper Showcase · 🧑✈️ Co-Pilot Guide · 📖 Integration Guide · 💬 Discord Community
|
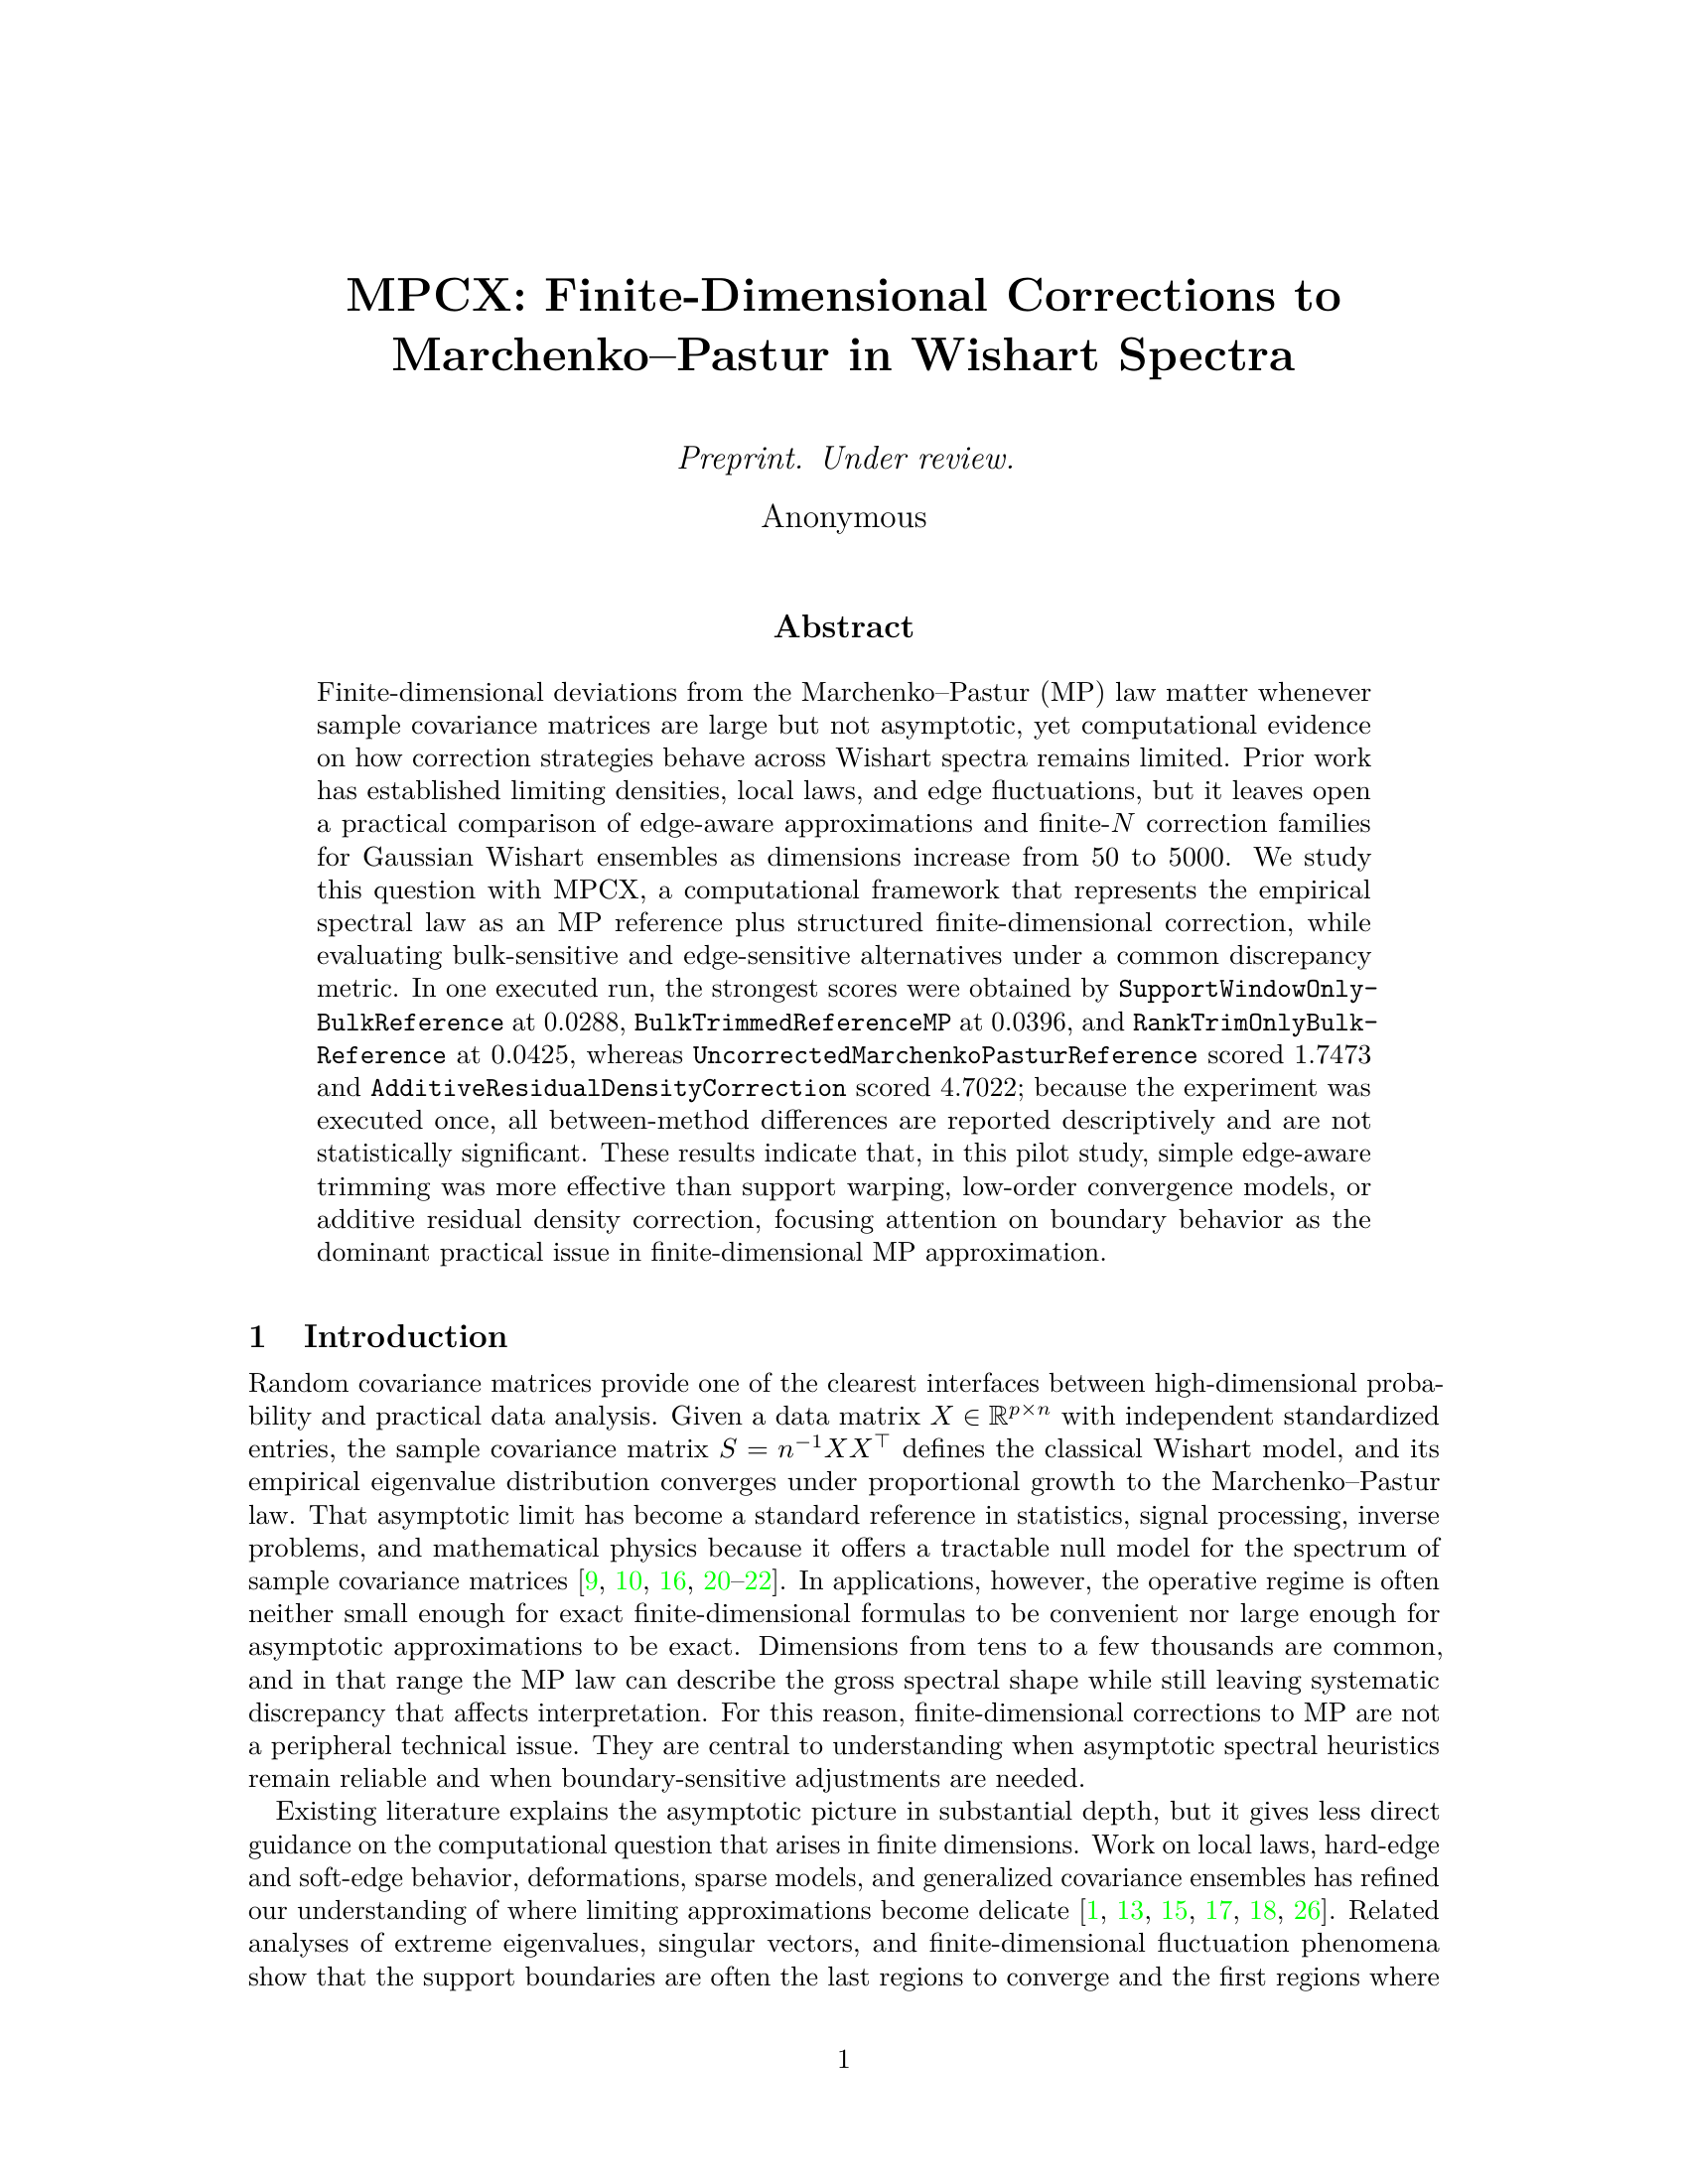
🏆 Generated Paper Showcase 8 papers across 8 domains — math, statistics, biology, computing, NLP, RL, vision, robustness — generated fully autonomously or with Human-in-the-Loop co-pilot guidance. 
|
🧪 We're looking for testers! Try the pipeline with your own research idea — from any field — and tell us what you think. Your feedback directly shapes the next version. → Testing Guide | → 中文测试指南 | → 日本語テストガイド
🔥 News
- [05/19/2026] v0.5.0 — Multi-Domain Experiment Agents + ARC-Bench — Two headline updates. (1) Domain-specialist execution agents: the experiment stage (Stages 10–13) now routes beyond the default ML sandbox to specialist agents per field — high-energy physics (ColliderAgent: Lagrangian → FeynRules → MadGraph5 → Delphes via the Magnus cloud), biology (COBRApy genome-scale metabolic modelling), and statistics (simulation-study agent), with a generic Docker executor covering chemistry/materials. The pipeline auto-selects the right executor from the research domain. (2) ARC-Bench: a 55-topic open-ended autonomous-research benchmark spanning ML (25), HEP (10), quantum (10), biology (7), and statistics (3) — each topic ships a manifest (research question + conditions + metrics + datasets) and a rubric for graded scoring, all under
experiments/arc_bench/, and also released on 🤗 Hugging Face. → Domain Integration Guide - [04/01/2026] v0.4.0 — Human-in-the-Loop Co-Pilot System — AutoResearchClaw is no longer purely autonomous. New HITL system adds 6 intervention modes (
full-auto,gate-only,checkpoint,step-by-step,co-pilot,custom), per-stage policies, and deep human-AI collaboration. Includes: Idea Workshop for hypothesis co-creation, Baseline Navigator for experiment design review, Paper Co-Writer for collaborative drafting, SmartPause (confidence-driven dynamic intervention), ALHF intervention learning, anti-hallucination claim verification, cost budget guardrails, pipeline branching for parallel hypothesis exploration, and CLI commands (attach/status/approve/reject/guide). → Full HITL Guide - [03/30/2026] Flexible Skill Loading — AutoResearchClaw now supports loading open-source and custom skills from any discipline to further enhance your research experience. 20 pre-loaded skills are included as ready-to-use references, covering scientific writing, experiment design, chemistry, biology, and more — including an A-Evolve agentic evolution skill contributed by the community. Load your own via
researchclaw skills installor drop aSKILL.mdinto.claude/skills/. See Skills Library. - [03/22/2026] v0.3.2 — Cross-Platform Support + Major Stability — AutoResearchClaw now runs on any ACP-compatible agent backend (Claude Code, Codex CLI, Copilot CLI, Gemini CLI, Kimi CLI) and supports messaging platforms (Discord, Telegram, Lark, WeChat) via OpenClaw bridge. New CLI-agent code generation backend delegates Stages 10 & 13 to external CLI agents with budget control and timeout management. Also includes anti-fabrication system (VerifiedRegistry + experiment diagnosis & repair loop), 100+ bug fixes, modular executor refactoring,
--resumeauto-detection, LLM retry hardening, and community-reported fixes.
Earlier releases
- **[03/18/2026]** [v0.3.1](https://github.com/aiming-lab/AutoResearchClaw/releases/tag/v0.3.1) — **OpenCode Beast Mode + Community Contributions** — New "Beast Mode" routes complex code generation to [OpenCode](https://github.com/anomalyco/opencode) with automatic complexity scoring and graceful fallback. Added Novita AI provider support, thread-safety hardening, improved LLM output parsing robustness, and 20+ bug fixes from community PRs and internal audit. - **[03/17/2026]** [v0.3.0](https://github.com/aiming-lab/AutoResearchClaw/releases/tag/v0.3.0) — **MetaClaw Integration** — AutoResearchClaw now supports [MetaClaw](https://github.com/aiming-lab/MetaClaw) cross-run learning: pipeline failures → structured lessons → reusable skills, injected into all 23 stages. **+18.3%** robustness in controlled experiments. Opt-in (`metaclaw_bridge.enabled: true`), fully backward-compatible. See [Integration Guide](#-metaclaw-integration). - **[03/16/2026]** [v0.2.0](https://github.com/aiming-lab/AutoResearchClaw/releases/tag/v0.2.0) — Three multi-agent subsystems (CodeAgent, BenchmarkAgent, FigureAgent), hardened Docker sandbox with network-policy-aware execution, 4-round paper quality audit (AI-slop detection, 7-dim review scoring, NeurIPS checklist), and 15+ bug fixes from production runs. - **[03/15/2026]** [v0.1.0](https://github.com/aiming-lab/AutoResearchClaw/releases/tag/v0.1.0) — We release AutoResearchClaw: a fully autonomous 23-stage research pipeline that turns a single research idea into a conference-ready paper. No human intervention required.⚡ One Command. One Paper.
# Fully autonomous — no human intervention
pip install -e . && researchclaw setup && researchclaw init && researchclaw run --topic "Your research idea here" --auto-approve

# Co-Pilot mode — collaborate with AI at key decision points
researchclaw run --topic "Your research idea here" --mode co-pilot
🤔 What Is This?
You think it. AutoResearchClaw writes it. You guide the key decisions.
Drop a research topic — get back a full academic paper with real literature from OpenAlex, Semantic Scholar & arXiv, hardware-aware sandbox experiments (GPU/MPS/CPU auto-detected), statistical analysis, multi-agent peer review, and conference-ready LaTeX targeting NeurIPS/ICML/ICLR. Run it fully autonomous, or use Co-Pilot mode to guide the AI at critical decision points — choose research directions, review experiment designs, and co-write the paper. No hallucinate
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|