📄 仓库 README
在 GitHub 查看 ↗
Built to democratize AI. Powered by .NET.


OpenMono is a coding agent that runs entirely on your hardware — no subscriptions, no data leaving your network, no per-token billing. It pairs a .NET 10 CLI with its own llama.cpp inference server, giving you a full agentic loop with 21 built-in tools, Docker sandboxing, and deep code intelligence. NVIDIA GPU, AMD APU (integrated Radeon iGPU, unified memory), or Apple Silicon (Metal) — it auto-configures itself. You own the model, the compute, and the data.
Free Course — Get Started with OMA
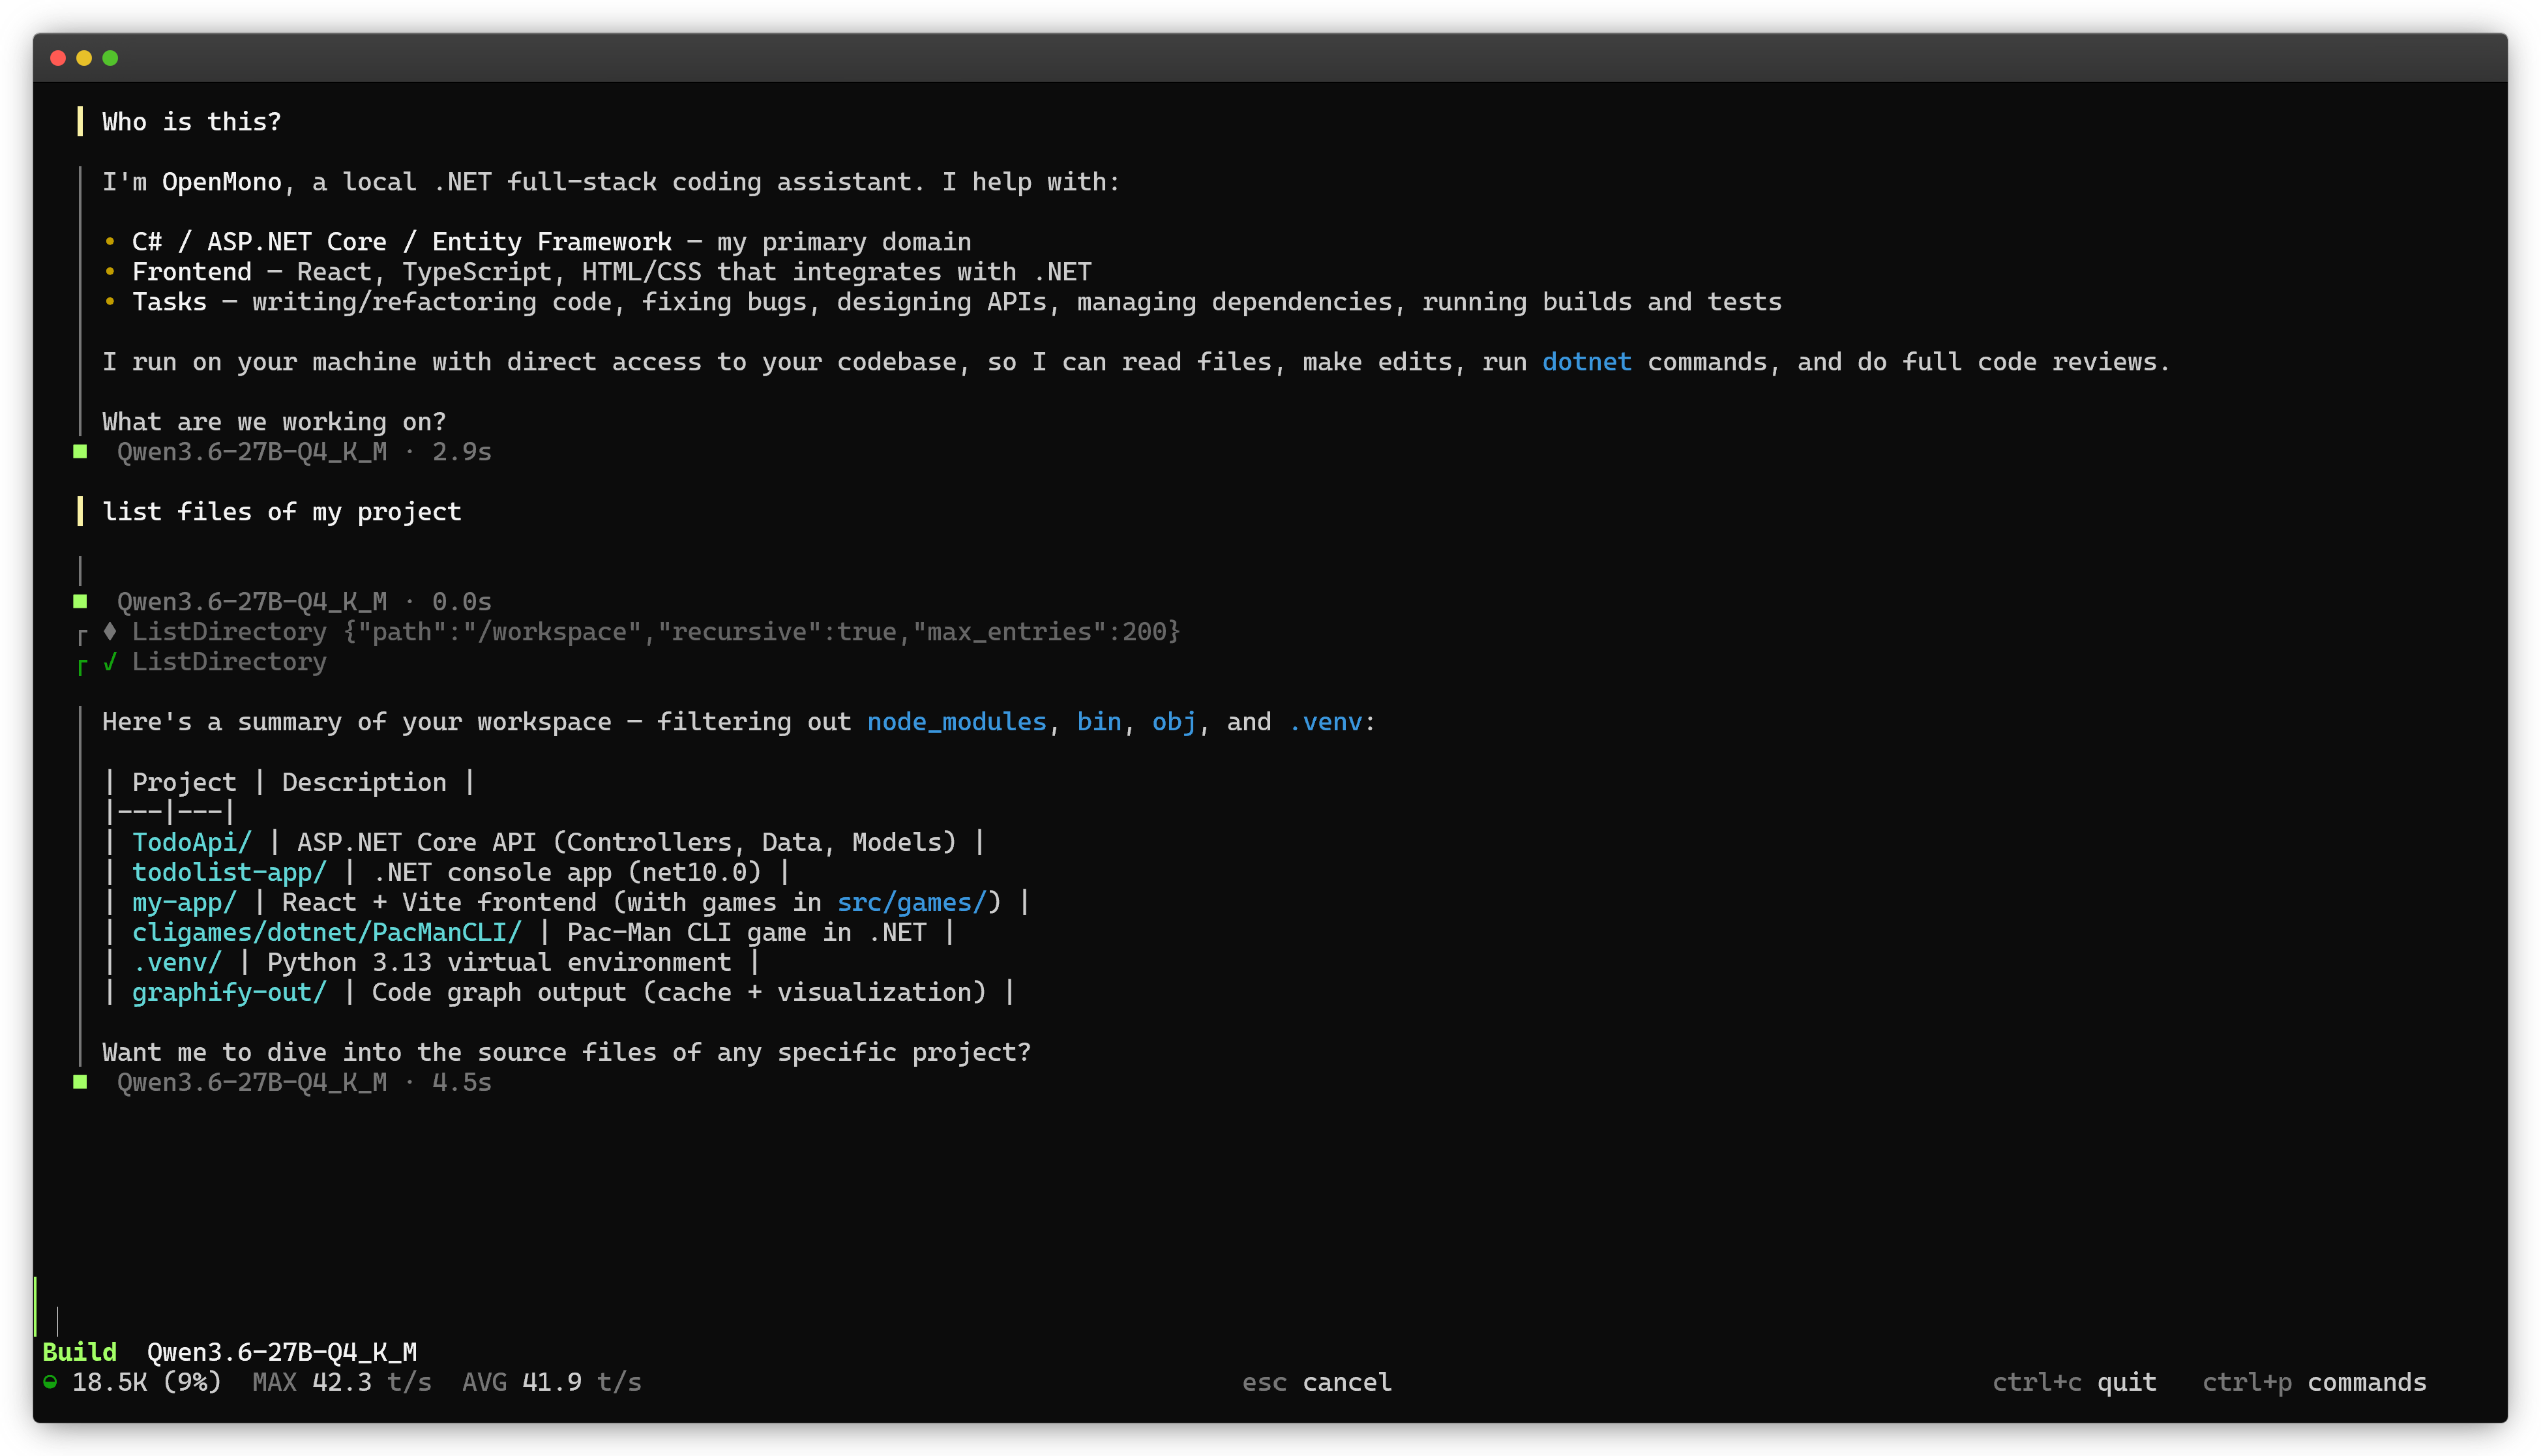
Quickstart
One command. Auto-detects GPU · APU/iGPU · Apple Silicon. Installs model, runtime, and Docker containers.
bash <(curl -fsSL https://raw.githubusercontent.com/StartupHakk/OpenMonoAgent.ai/refs/heads/main/get-openmono.sh)
Then from any project:
openmono agent            # TUI mode (default)
openmono agent --classic  # classic scrolling terminal
→ Full command reference — daily commands, setup flags, GPU/iGPU options · Need help? Book a call
What's shipping
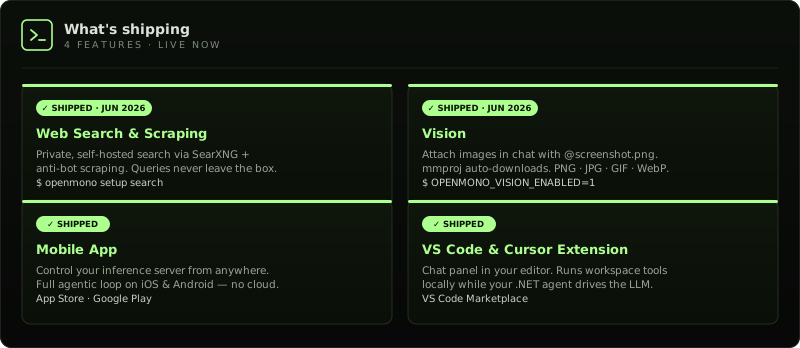
Get them: openmono setup search · OPENMONO_VISION_ENABLED=1 · App Store · Google Play · VS Code Marketplace
How it compares
Most coding agents are cloud products wearing an open-source label. Your prompts, your code, and your context hit someone else's servers on every keystroke. OpenMono runs the model on your hardware — after the one-time setup, inference costs nothing. Your code never leaves the machine. No account. No usage dashboard. No API key.
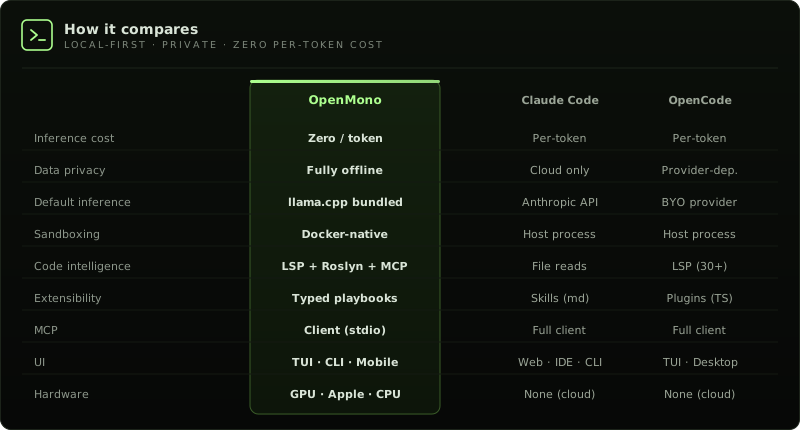
→ Full architecture + diagram · 5 provider backends · runs at ~45 tok/s on GPU, ~20 tok/s on AMD iGPU (APU)
What's inside
| 01 · **Bundled inference — zero config, zero cost** llama.cpp ships inside Docker. Installer detects your hardware and picks the right model. After setup, every token is free. `GPU` Qwen3.8-27B dense · ~60 tok/s `iGPU` Qwen3.6-35B-A3B MoE · APU unified memory · ~20 tok/s `Mac` Qwen3.6-35B-A3B MoE · Metal · ~45–48 tok/s → [Models & reasoning mode](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/MODELS.md) | 02 · **Agentic loop that earns its name** Up to 1,000 iterations per turn. Doom-loop detection nudges on repeated tool batches, escalates the nudge at 3 consecutive detections, and ends the turn at 5. Checkpoints at 65% context fill, compacts at 80%. Runs until done — then stops. |
| 03 · **[21 tools](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/ARCHITECTURE.md), guarded pipeline** Every call: parse → schema validate → path sanity → plan-mode gate → host-mode gate → permission check → cache → pre-hook → execute → post-hook → artifact store → cache write → invalidate. Read-only tools run in parallel. Nothing bypasses the pipeline. | 04 · **5 specialist sub-agents** Isolated sessions with locked tool sets and turn budgets: `Explore` · read-only discovery · 100 turns `Plan` · architecture, no writes · 100 turns `Coder` · full file access · 300 turns `Verify` · adversarial + Roslyn · 150 turns `general-purpose` · everything · 200 turns |
| 05 · **Docker sandbox** In sandbox mode the project mounts as `/workspace`. The agent reads and writes your real files — that's the blast radius; nothing outside that mount is visible. Host mode is the explicit exception: machine-level actions run only through approved `HostExec` calls. | 06 · **Deep code intelligence** Roslyn: type hierarchy, blast-radius, cross-file symbol search, callers, diagnostics — 5-min compilation cache. LSP for TypeScript, Python, Go, Rust, lazy-started on first use. Auto-detects [graphify](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/graphify.md) (semantic concept graph, 25+ languages) and [code-review-graph](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/code-review-graph.md) (structural call graph via MCP, ~22 tools) if installed — no config needed. |
| 07 · **[Playbooks](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/PLAYBOOKS.md)** YAML workflows with typed parameters, conditional gates, and checkpoint/resume. | 08 · **[5 provider backends](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/MODELS.md)** Local llama.cpp is the default; Strata is the supported Linux high-end backend. OpenAI, Anthropic, and Ollama are available but WIP — see [Models](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/MODELS.md) for details. Providers are selected in `settings.json` at startup; `/model` switches the model on the active provider. |
| 09 · **Distributed inference** Agent on your laptop, inference on a separate GPU machine. No port forwarding — tunnel is established outbound from the inference box. Free relay at [app.openmonoagent.ai](https://app.openmonoagent.ai). → [Dual-box setup guide](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/SETUP.md#dual-box-setup) | 10 · **Vision** Attach images in chat with `@screenshot.png` or ask the agent to read any image file. The multimodal projector (mmproj) is downloaded automatically at setup. Supported formats: PNG, JPG, GIF, WebP. Large images are auto-resized to fit within the image budget. Enable vision in `settings.json` (`inference.vision_enabled`) or set `OPENMONO_VISION_ENABLED=1`. → [Vision setup & usage](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/SETUP.md#vision) |
| 11 · **Private web search & scraping** Self-hosted search via SearXNG — your queries never leave the machine. Anti-bot scraping via Scrapling + Camoufox (real browser, Cloudflare bypass). Single Caddy gateway, auto-detected. Falls back to DuckDuckGo / direct fetch when the gateway is absent. `openmono setup search` · `openmono setup scraper` → [Web services architecture](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/ARCHITECTURE.md#inference-side-web-services-caddy-gateway) | 12 · **VS Code extension** The full agent loop in your editor sidebar — streaming responses, live Markdown, file edits, bash, and permission prompts without leaving VS Code. Connects to the local agent over ACP on port `7475`. Also works in Cursor. `code --install-extension StartupHakk.openmono-agent` → [Extension docs](https://github.com/StartupHakk/OpenMonoAgent.ai/blob/HEAD/docs/SETUP.md#vs-code--cursor-extension) · [Marketplace](https://marketplace.visualstudio.com/items?itemName=StartupHakk.openmono-agent) |
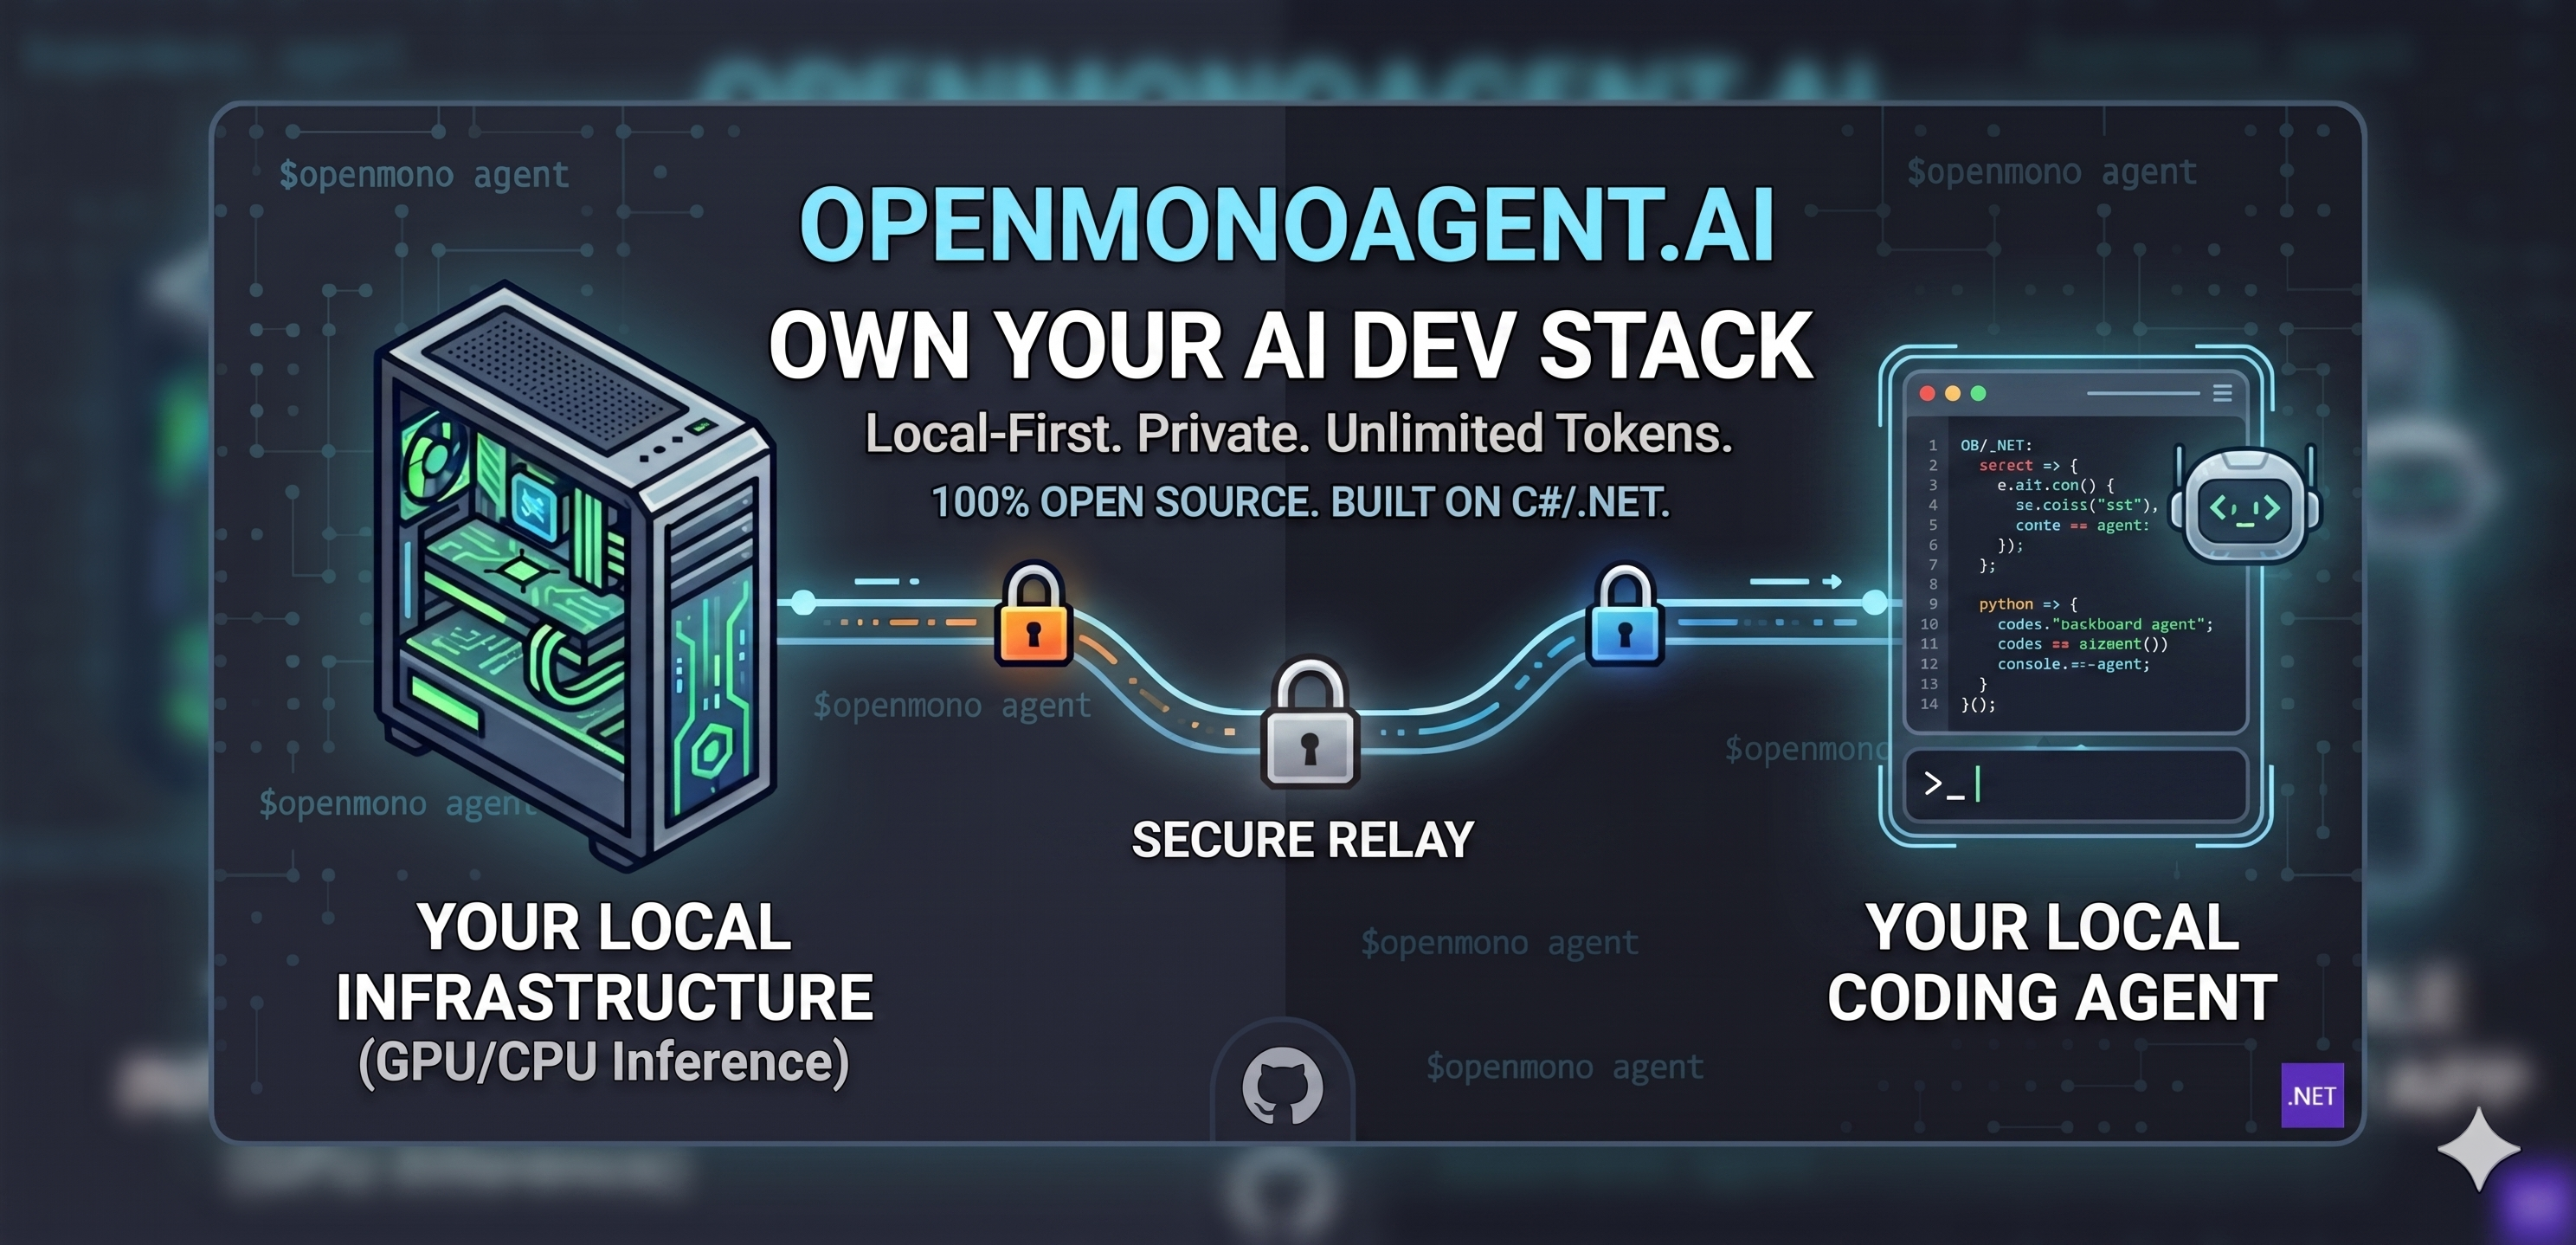
Supported Hardware
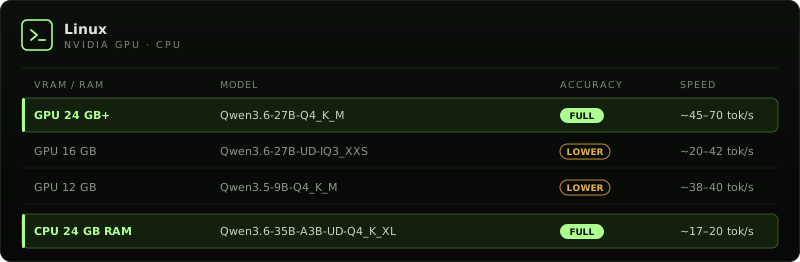
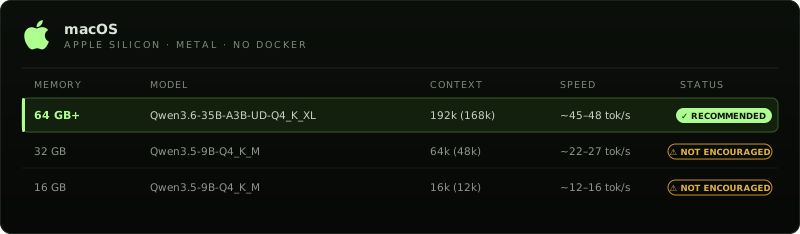
Setup auto-detects GPU · iGPU/APU · no config needed and picks the best model your hardware can run — no prompts. Pass --options to choose the model, vision, and parallel slots yourself, or --model=<name> to pin one. The pick depends on VRAM and system RAM: on Linux a 24 GB+ card gets Qwen3.8-Flash-Next (Strata) on a 48 GB-class box and Qwen3.8-27B below that, a 16 GB card keeps Qwen3.8-27B, a 12 GB card and AMD 780M iGPUs (32 GB+ RAM) get Ternary-Bonsai-2-27B via Prism. Requires Ubuntu 26.04 LTS (recommended) or 25.10. On macOS, the full and inference roles require Apple Silicon (M1+); 48 GB+ unified memory is the recommended, tested configuration. 24–47 GB and 16–23 GB Macs run Ternary-Bonsai (PQ2_0 / PTQ1_0) with a tighter context window. Intel Macs: agent-only mode. macOS 14+ (Sonoma/Sequoia) recommended.
Need Help?
Stuck on setup, or want OpenMono on your own servers? We install and support private OpenMono deployments — contact us, book a call, and we'll walk you through getting it running on your hardware. Pick your hardware. We handle the rest.
Docs
Roadmap |
What's next |
Setup & commands |
Daily commands, TUI vs classic, flags |
Deployment modes |
Single-box vs split-box, server-ops runbook |
Architecture |
.NET CLI + llama.cpp + Docker, full diagram |
Models & reasoning |
Model tiers, reasoning mode, provider config |
Configuration |
settings.json, providers, permissions, MCP servers |
Playbooks |
YAML workflows, typed params, checkpoint/resume |
graphify |
Semantic code graph, 25+ languages |
code-review-graph |
Structural call graph via MCP |
VS Code extension |
Chat panel for VS Code 1.85+ · also works in Cursor · Marketplace |
Contributing |
How to contribute |
| PUBLIC BETA Early access is open — we're shipping updates fast. Try it out and tell us what you'd like to see next. |
Contributing
| OpenMono is early and moving fast. Contributions are welcome — new tools, providers, LSP servers, playbooks, bug fixes, or docs. |
→ Read the contributing guide before opening a PR
|
"AI shouldn't be a subscription you rent. It should be infrastructure you own —
sitting on your desk, serving your code, answering only to you."
— Startup Hakk
GNU AFFERO GENERAL PUBLIC LICENSE v3.0 · © 2026 StartupHakk
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|