📄 仓库 README
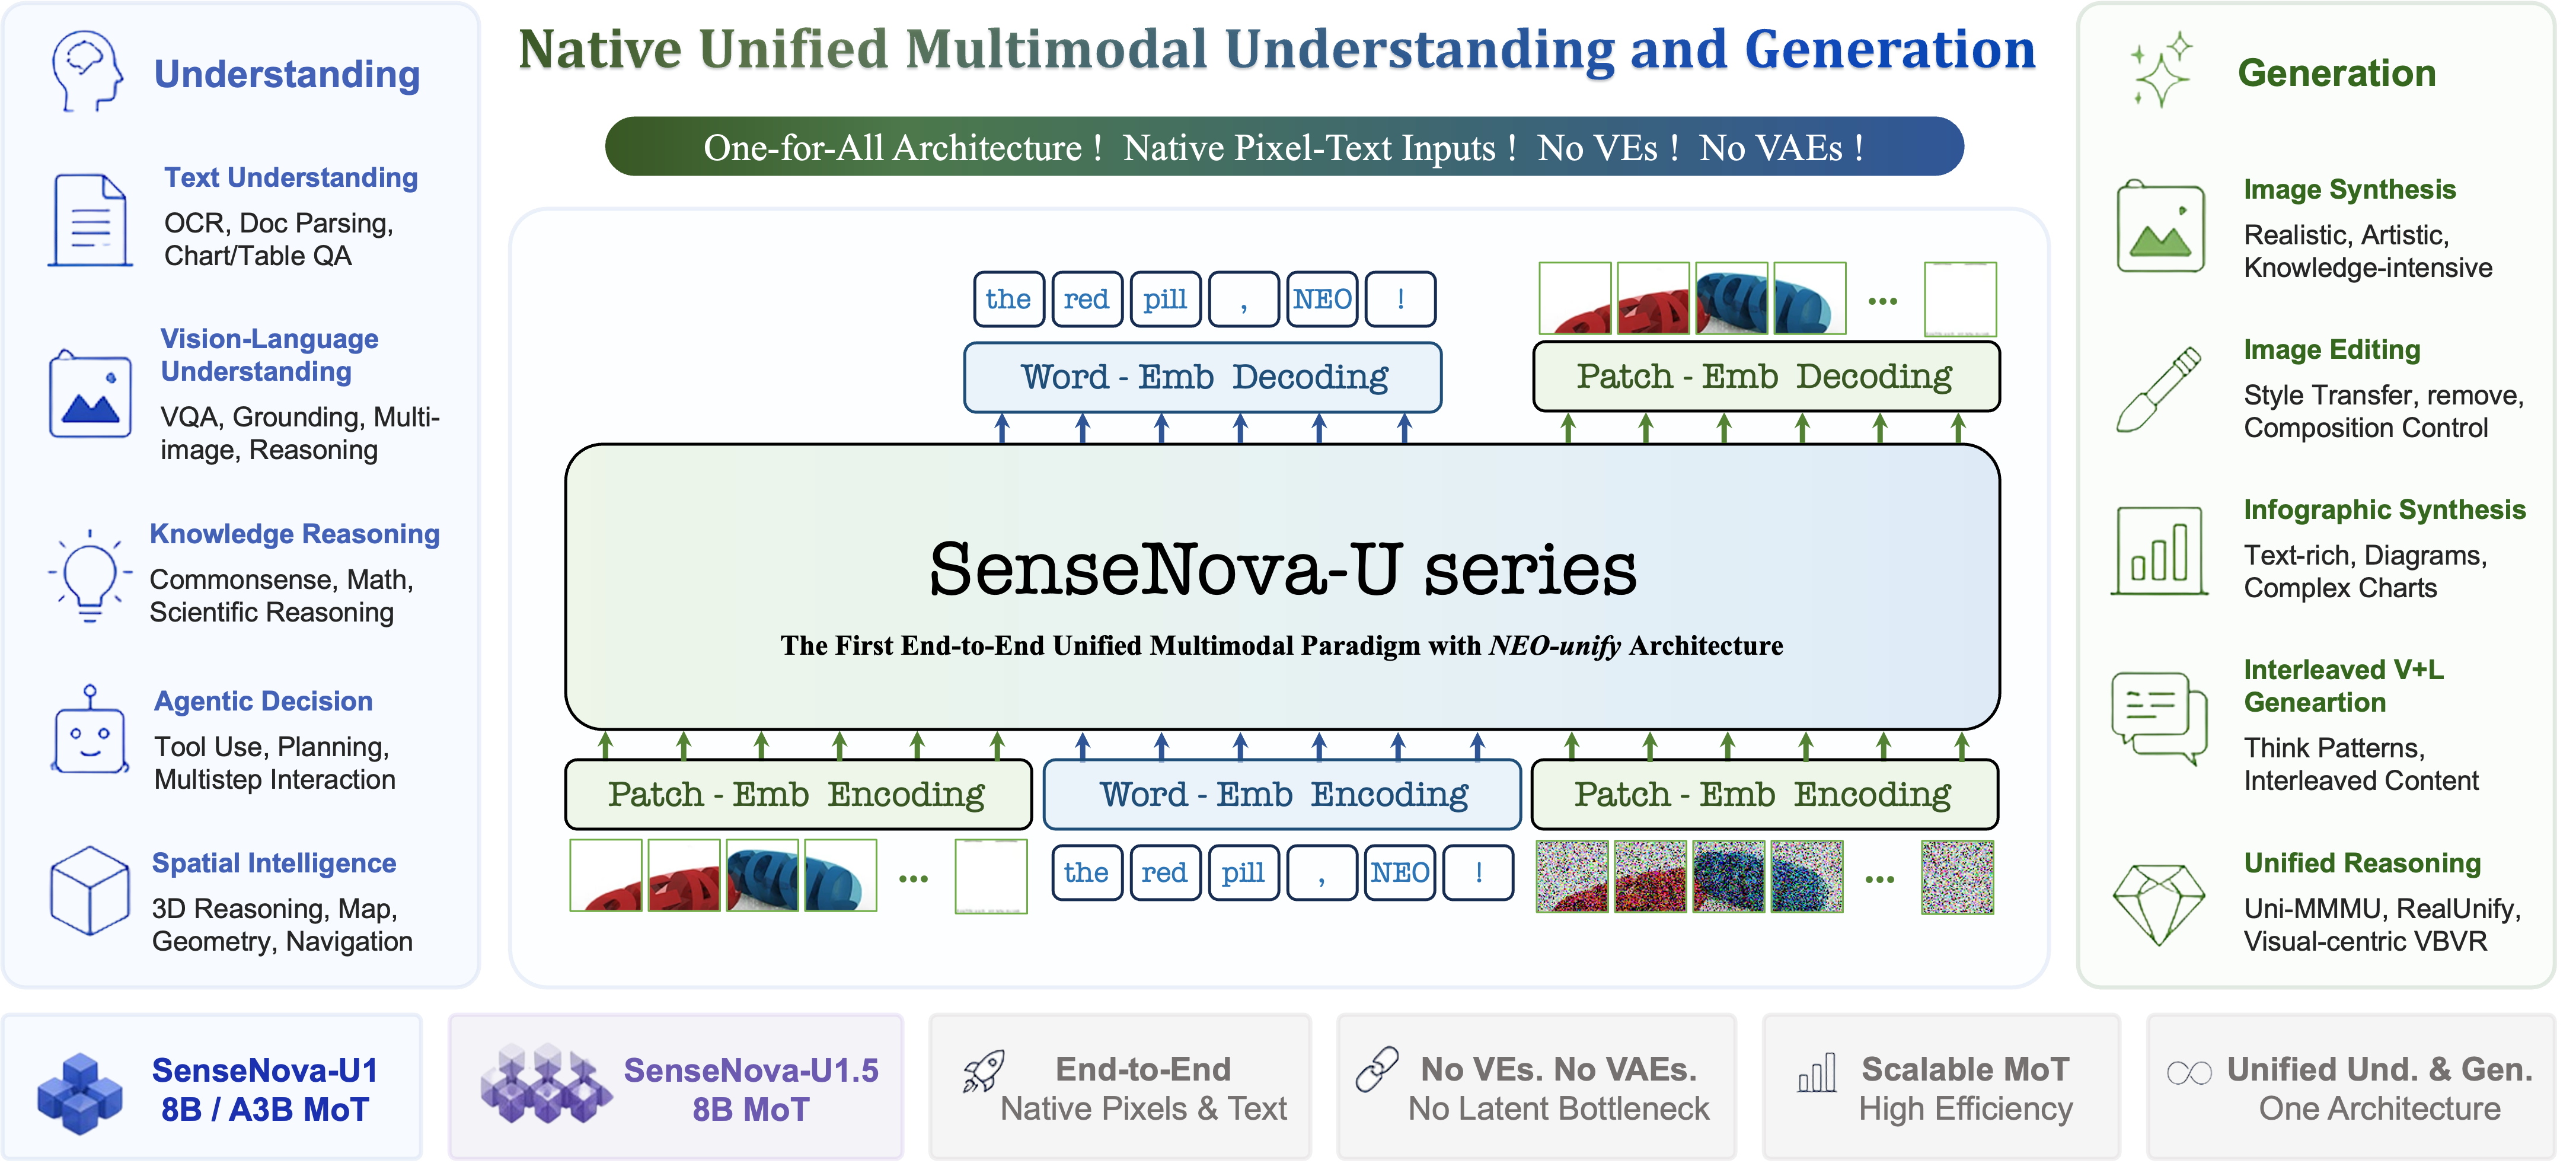
在 GitHub 查看 ↗SenseNova-U series: Native Unified Paradigm with NEO-unify from the First Principles
English | 简体中文


📣 Updated News
-
[2026.10.26]SenseNova-U1.5 has been officially supported by stable-diffusion.cpp for text-to-image generation, and llama.cpp for text-to-text, image-to-text, and image-text-to-text generation. -
[2026.09.24]Release SenseNova-U1.5-8B-MoT-LoRA-8step-V2, which delivers improved visual quality with better color balance, more natural contrast, and reduced oversharpening across the board, compared with the previous SenseNova-U1.5-8B-MoT-LoRA-8step. -
[2026.09.11]Release the 🔥SenseNova-U1.5 Technical Report🔥, covering the native unified architecture, training recipe, and evaluation results. -
[2026.09.01]Community contributor realrebelai on Hugging Face (GitHub @RealRebelAI) released a Q8 GGUF checkpoint for SenseNova-U1.5-8B-MoT (21.2 GB). Thank you for continuing to maintain and share quantized SenseNova-U1.5 weights with the community. -
[2026.08.20]Release SenseNova-U1.5-8B-MoT, which further improves instruction following, text and layout, native 4K generation, image editing, and visual control. Alongside the base checkpoint, we release SenseNova-U1.5-8B-MoT-LoRA-8step for faster and more efficient inference; see example script for usage. We are also preparing the technical report and the full training pipeline, from SFT and RL to MOPD, for open-source release. -
[2026.08.04]Community contributor smthem on Hugging Face (GitHub @smthemex) released a Q8 GGUF checkpoint for SenseNova-U1.5-8B-MoT-Preview (19.9 GB). Thank you for continuing to maintain and share quantized SenseNova-U1 weights with the community. -
[2026.07.31]Release SenseNova-U1.5-8B-MoT-Preview that focuses on native 4K image generation, finer local textures and realistic materials, more complex layout generation, and stronger preservation of subjects and unedited regions during image editing. See the U1.5 Preview documentation for details.
Click to expand older SenseNova-U1 updates
- `[2026.07.16]` Release [SenseNova-U1-8B-MoT-Infographic-V3 📊](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-Infographic-V3), designed for integrated infographic generation and editing. It retains strong text-to-image (T2I) capabilities while significantly enhancing infographic editing, supporting localized text and content editing, global style editing, and global layout editing. See [✨ U1 Infographic Model Series](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/u1_infographic_model.md) for model details and benchmark results. A corresponding supported [ComfyUI workflow](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/apps/comfyui/example_workflows/infographic_series_t2i_edit.json) is also available. - `[2026.06.29]` Release [SenseNova-U1-8B-MoT-Infographic-V2 📊](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-Infographic-V2), an upgraded infographic model with improved dense small-text rendering with sharper text edges, stronger complex dense-layout generation, and better overall visual aesthetics and harmony, plus a fix for the black-background issue. Model details and visual examples are available in [✨ U1 Infographic Model Series](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/u1_infographic_model.md). - `[2026.06.12]` Release [SenseNova-U1-8B-MoT-Infographic-LoRA-8step-V1.0](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-LoRAs/blob/main/SenseNova-U1-8B-MoT-Infographic-LoRA-8step-V1.0.safetensors) for faster infographic generation. Please see the [example script](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/base_vs_distill.md#run-base-and-distilled-model). - `[2026.06.11]` Release [SenseNova-U1-8B-MoT-Interleaved 📖](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-Interleaved), specially optimized for interleaved image-text generation, with notably improved narrative coherence, character and style consistency, and text-image alignment in multi-page content. - `[2026.05.21]` Release the full-parameter fine-tuning [training code](https://github.com/OpenSenseNova/SenseNova-U1/blob/main/training/README.md) for SenseNova-U1. - `[2026.05.15]` Release [SenseNova-U1-8B-MoT-Infographic 📊](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-Infographic) model for improved infographic generation. See [U1 Infographic Model Series](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/u1_infographic_model.md) for details, and [✨ Infographic Showcases ](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/u1_infographic_showcases.md) for 100 generated examples. - `[2026.05.10]` Release [🔥SenseNova-U1 Technical Report🔥](https://github.com/OpenSenseNova/SenseNova-U1/blob/main/docs/pdf/SenseNOVA_U1.pdf) and the weights for [SenseNova-U1-A3B-MoT-SFT](https://huggingface.co/sensenova/SenseNova-U1-A3B-MoT-SFT) & [SenseNova-U1-A3B-MoT](https://huggingface.co/sensenova/SenseNova-U1-A3B-MoT). - `[2026.05.08]` Add **GGUF quantized checkpoints** and **layer-offload VRAM modes** for low-VRAM single-GPU inference. See [Memory-efficient inference](#-memory-efficient-inference-gguf--vram-modes). GGUF weights for `SenseNova-U1-8B-MoT-Merger` are available at [🤗 smthem/SenseNova-U1-8B-MoT-Merger-gguf](https://huggingface.co/smthem/SenseNova-U1-8B-MoT-Merger-gguf) — many thanks to [@smthemex](https://github.com/smthemex) for contributing the quantized weights. - `[2026.05.06]` Release [SenseNova-U1-8B-MoT-LoRA-8step-V1.0](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-LoRAs/blob/main/SenseNova-U1-8B-MoT-LoRA-8step-V1.0.safetensors). Please see the [example script](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/base_vs_distill.md#run-base-and-distilled-model). - `[2026.04.30]` Release the preview version of the 8-step inference model [SenseNova-U1-8B-MoT-8step-preview](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-8step-preview). In most cases, the image generation quality of this model closely matches that of the base model (see [comparison and existing issues](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/docs/base_vs_distill.md)). To test this model, you can use the [inference scripts](https://github.com/OpenSenseNova/SenseNova-U1/blob/HEAD/examples/README.md), but with the following parameters: ```--cfg_scale 1.0 --num_steps 8``` . - `[2026.04.27]` Initial release of the weights for [SenseNova-U1-8B-MoT-SFT](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT-SFT) and [SenseNova-U1-8B-MoT](https://huggingface.co/sensenova/SenseNova-U1-8B-MoT). - `[2026.04.27]` Initial release of the [inference code](https://github.com/OpenSenseNova/SenseNova-U1/blob/main/examples/README.md) for SenseNova-U1.🚀 SenseNova-U1.5
🌟 Overview
SenseNova-U1.5-8B-MoT is our latest native unified multimodal checkpoint for more accurate, consistent, reliable, and aesthetically compelling visual creation. Built on NEO-unify, we further strengthen the patchify layers, data quality and distribution, task formulation, prompt enhancement, and post-training pipeline.
The official release focuses on six user-visible improvements:
- Higher-quality image generation: improved composition and color harmony, with more realistic material rendering, natural lighting, stronger visual fidelity, and finer local details.
- Better text rendering and infographic generation: more legible Chinese and English text, with clearer information hierarchy in posters, infographics, brand assets, and other text-dense designs.
- More efficient native 4K generation: more coherent global structure, col
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|