📄 仓库 README
在 GitHub 查看 ↗


Website · Discord · English · 简体中文 · 繁體中文 · Italiano · 日本語 · Bahasa Indonesia · Português (Brasil)
Tiny engine, immense model. colibri runs very large open models on the machine you already have. A mixture-of-experts model of hundreds of billions of parameters uses only a small part of itself for each token, so colibri keeps that part in RAM and reads the rest, the experts, from the disk when the model asks for them. Pure C, one file per model family, no GPU required.
Thirteen engines run today. Ten are for language models: GLM-5.2/5.3 (which also runs Mistral-Large-4), GLM-5.3-Flash, Inkling, Kimi K3, DeepSeek V4 Flash, DeepSeek V4.1 Flash, MiMo-V2.6 Flash (and Pro), Qwen3.8-Flash-Next, Qwen3.6 (which also runs Qwen3-Coder, the dense Qwen3.8-27B, Flint, Muse Spark Open and LFM3-VL) and OLMoE. One draws pictures: Qwen-Image-2.1. Two answer decisions: Laya and GLiNER2.5-Decide, with a third decision model, Clef, on the Qwen3.6 engine. The language models also run from the GGUF files already published, read as they are (GGUF), on the CPU, on any GPU through Vulkan and on NVIDIA cards through CUDA. Which one for my machine
$ ./coli chat
  colibri v2.1.0 · GLM-5.2 · 744B MoE · int4 · streaming CPU
  ✓ ready in 32s · resident 9.9 GB
  › ciao!
  ◆ Ciao! Come posso aiutarti oggi?

colibri is free and open source. If it has earned a place on your machine, a coffee helps pay for the next engine and the next speedup.
Get started in one step
You need a computer with 8 GB of RAM at the very least (16 GB or more is better), 22 GB free on the disk for the smallest model, and an internet connection. A graphics card is optional.
Windows
- On this page click Code, then Download ZIP, and unzip it.
- Double-click
START-HERE.batin the unzipped folder. If Python is missing, it offers to install it for you.
Linux (Ubuntu and Debian; other distributions have the same packages under their own names)
sudo apt install git python3 build-essential
git clone https://github.com/JustVugg/colibri
cd colibri
./start-here.sh
macOS (with Homebrew)
xcode-select --install
brew install libomp git python
git clone https://github.com/JustVugg/colibri
cd colibri
./start-here.sh
You answer one question, which model, and Enter takes the recommendation. Then the setup:
- looks at your machine: RAM, free disk, CPU and GPUs;
- recommends a model that fits: the part of the model that always stays in RAM, plus a minimum cache of experts, must fit in your RAM, and the download on your disk;
- gets the engine: it builds it for your machine when a compiler is there, otherwise it downloads the prebuilt one, which runs on the CPU and, on Linux and Windows, on a Vulkan GPU too. It builds for your GPU when that pays: CUDA for an NVIDIA card on Linux when the CUDA toolkit is installed, otherwise Vulkan. On a discrete GPU it always does; on an integrated GPU, which shares the CPU's RAM, only for the models measured faster there (Qwen3.6, Qwen3-Coder and Qwen3.8-Flash-Next). If a package is missing it prints the exact command to install it and carries on with the CPU; run the setup again afterwards and it rebuilds for the GPU;
- downloads the model with progress and resume: stop it whenever you like, run it again and it continues where it stopped;
- starts colibri and opens the dashboard in your browser, and prints the addresses other apps can use:
Starting colibri
  Browser:             http://127.0.0.1:8000/
  OpenAI base URL:     http://127.0.0.1:8000/v1
  Anthropic base URL:  http://127.0.0.1:8000
  stop: press Ctrl+C here (or close this window)
Next time, run START-HERE.bat or ./start-here.sh again: colibri starts
straight away, with no download and no build. c/coli status shows what is
installed and whether it runs, c/coli stop stops it (c\coli.cmd status and
c\coli.cmd stop on Windows).
Options go after ./start-here.sh or START-HERE.bat:
| Option | What it does |
|---|---|
--list |
every model against this machine, and why one does not fit |
--model ID |
install that model (the ids are in the tables below) |
--yes |
no questions: take the recommendation |
--dir DIR |
put the models on another disk (default ~/colibri-models) |
--backend vulkan, cuda or cpu |
choose the engine build yourself; --no-gpu is --backend cpu |
--model-dir DIR |
use a model you already downloaded |
--reconfigure |
choose another model |
What each step does, in detail: docs/quickstart.md.
If something goes wrong
| What you see | What to do |
|---|---|
| it stopped during the download | run the same command again: it resumes from the bytes already on disk |
to use the GPU through ..., first run: <command> |
run that command, then the setup again: it rebuilds for the GPU and does not download again |
the ... build failed, for example Unsupported gpu architecture when the installed CUDA toolkit no longer supports the card |
the setup checks the toolkit against the card first and picks Vulkan by itself, saying why; if a build still fails it offers the next one (Vulkan, then the CPU). ./start-here.sh --backend vulkan forces Vulkan; --no-gpu stays on the CPU |
needs N GB free for the download |
--dir with a folder on a bigger disk |
on WSL, the model folder is under /mnt/c |
keep it on the Linux disk (the default, ~/colibri-models): /mnt/c is many times slower |
you updated the checkout (git pull) |
run ./start-here.sh again: it rebuilds the engine when the sources changed, then starts it |
| anything else | c/coli logs -n 50 shows the log of a server started in the background (one started in the foreground prints to its own terminal) and c/coli logs --install the setup's; open an issue with the last lines the setup printed |
Let your AI assistant set it up
If you use an AI coding assistant, it can do all of this for you. Ask it:
Set up colibri on this machine following docs/AI_SETUP.md from https://github.com/JustVugg/colibri
docs/AI_SETUP.md gives the assistant every step as a
command with a machine-readable result, and tells it to ask you before it
downloads a model or installs a system package. Assistants that speak the Model
Context Protocol can use colibri's MCP server instead: coli mcp offers tools
to detect the hardware, recommend a model, install, start, stop and check it
(docs/MCP_SERVER.md).
Or by hand
To choose each step yourself (a prebuilt release or a source build, any model
from the tables below, then coli chat, coli web or coli serve), see
Install by hand, or the
Quick Start guide for every platform step by step.
What colibri is, and why
A mixture-of-experts model is huge on disk and small per token. GLM-5.2 has 744B parameters, uses about 40B for each token, and only about 11 GB of those change from one token to the next: the routed experts.
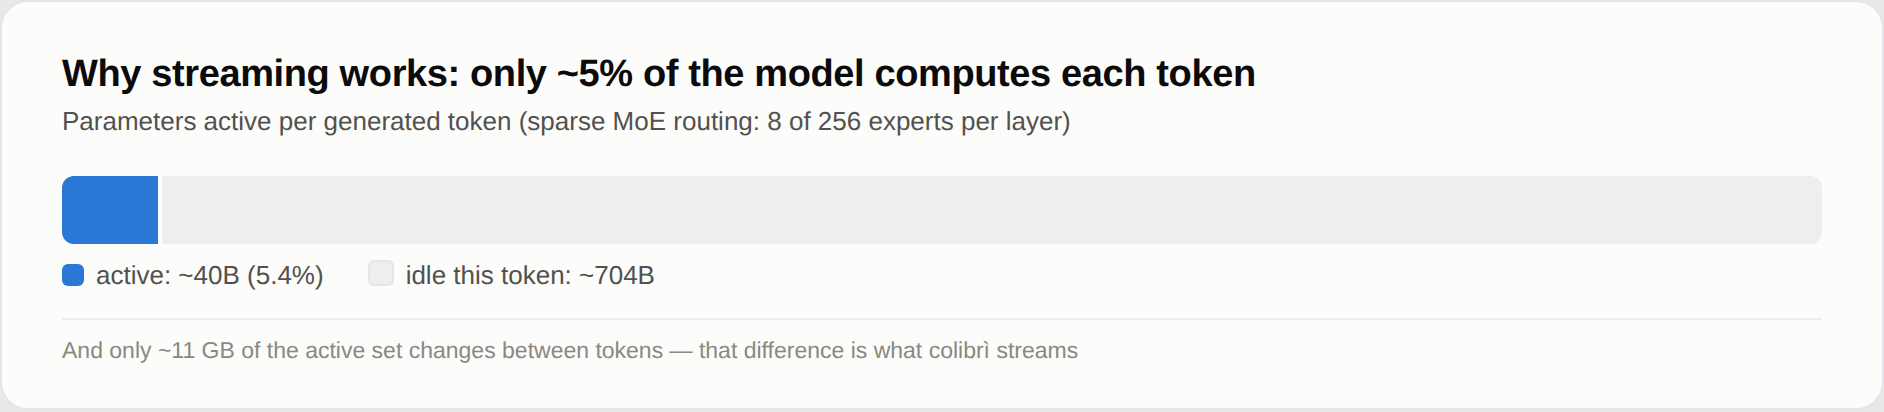
So the model does not have to fit in fast memory; it has to be placed. The dense part (attention, shared experts, embeddings) stays in RAM. The routed experts stay on the disk and are read when the router asks for them, through a cache that learns which experts your work uses. A GPU, when there is one, holds the hottest experts and the dense layers. Where a weight sits changes how fast the answer comes, not which weights or which router decisions produce it.
Why: to run models of this size on hardware people already own, to watch them work (the dashboard shows every expert as it fires), and to keep the engine small enough that anyone can measure it and make it faster. colibri is also an open research platform: an optimisation earns its place with a reproducible end-to-end measurement, and the default policy never silently changes model precision or router semantics. Less fast memory may cost speed; it must not quietly redefine the model. How it works has the details.
Which model for my machine
The setup recommends the most capable model that runs from RAM on your
machine, and lists the larger ones that stream from the disk right below it.
./start-here.sh --list shows them all against your machine. The tables follow
the setup's own catalog (c/setup_catalog.py); the
downloads are the sizes Hugging Face lists for each repository.
- RAM is two numbers: below the first the model does not start, from the second it runs as measured.
- GPU is what the setup can build for that engine (GPUs). Integrated too means it also uses an integrated
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|