HKUDS / RAG-Anything
← 返回首页
"RAG-Anything: All-in-One RAG Framework"
本站解读
多模态 RAG 框架,把文档里的文字和图片放进同一条检索链路,而不是先抽文本再单独处理图像。2025 年 7 月增加上下文配置模块,用于把相关上下文按需拼装进生成流程;8 月上线的 VLM-Enhanced Query 模式在文档含图片时,将图像直接送入视觉语言模型,让回答同时参考图文两类线索;10 月公开技术报告,说明检索与生成的实现路径。2026 年 6 月起,LightRAG 通过原生集成获得多模态检索能力,等于给这套框架接了一条更成熟的上层调用入口。Python 编写,MIT 许可。适合要处理带图表 PDF、扫描件或混合版式资料的检索问答项目,也适合想对照实现细节的研究者。
上榜 1 天 · 首次上榜 2026-11-18 · 近 7 天 +44 star · 榜单最高 #12 · MIT
📄 仓库 README
在 GitHub 查看 ↗来自 GitHub 仓库自述文件 · 版权归原作者所有



🎉 News
- [X] [2026.06]🎯📢 🎉 LightRAG enables multimodal RAG through native integration of RAG-Anything.
- [X] [2025.10]🎯📢 🚀 We have released the technical report of RAG-Anything. Access it now to explore our latest research findings.
- [X] [2025.08]🎯📢 🔍 RAG-Anything now features VLM-Enhanced Query mode! When documents include images, the system seamlessly integrates them into VLM for advanced multimodal analysis, combining visual and textual context for deeper insights.
- [X] [2025.07]🎯📢 RAG-Anything now features a context configuration module, enabling intelligent integration of relevant contextual information to enhance multimodal content processing.
- [X] [2025.07]🎯📢 🚀 RAG-Anything now supports multimodal query capabilities, enabling enhanced RAG with seamless processing of text, images, tables, and equations.
- [X] [2025.07]🎯📢 🎉 RAG-Anything has reached 1k🌟 stars on GitHub! Thank you for your incredible support and valuable contributions to the project.
🌟 System Overview
Next-Generation Multimodal Intelligence
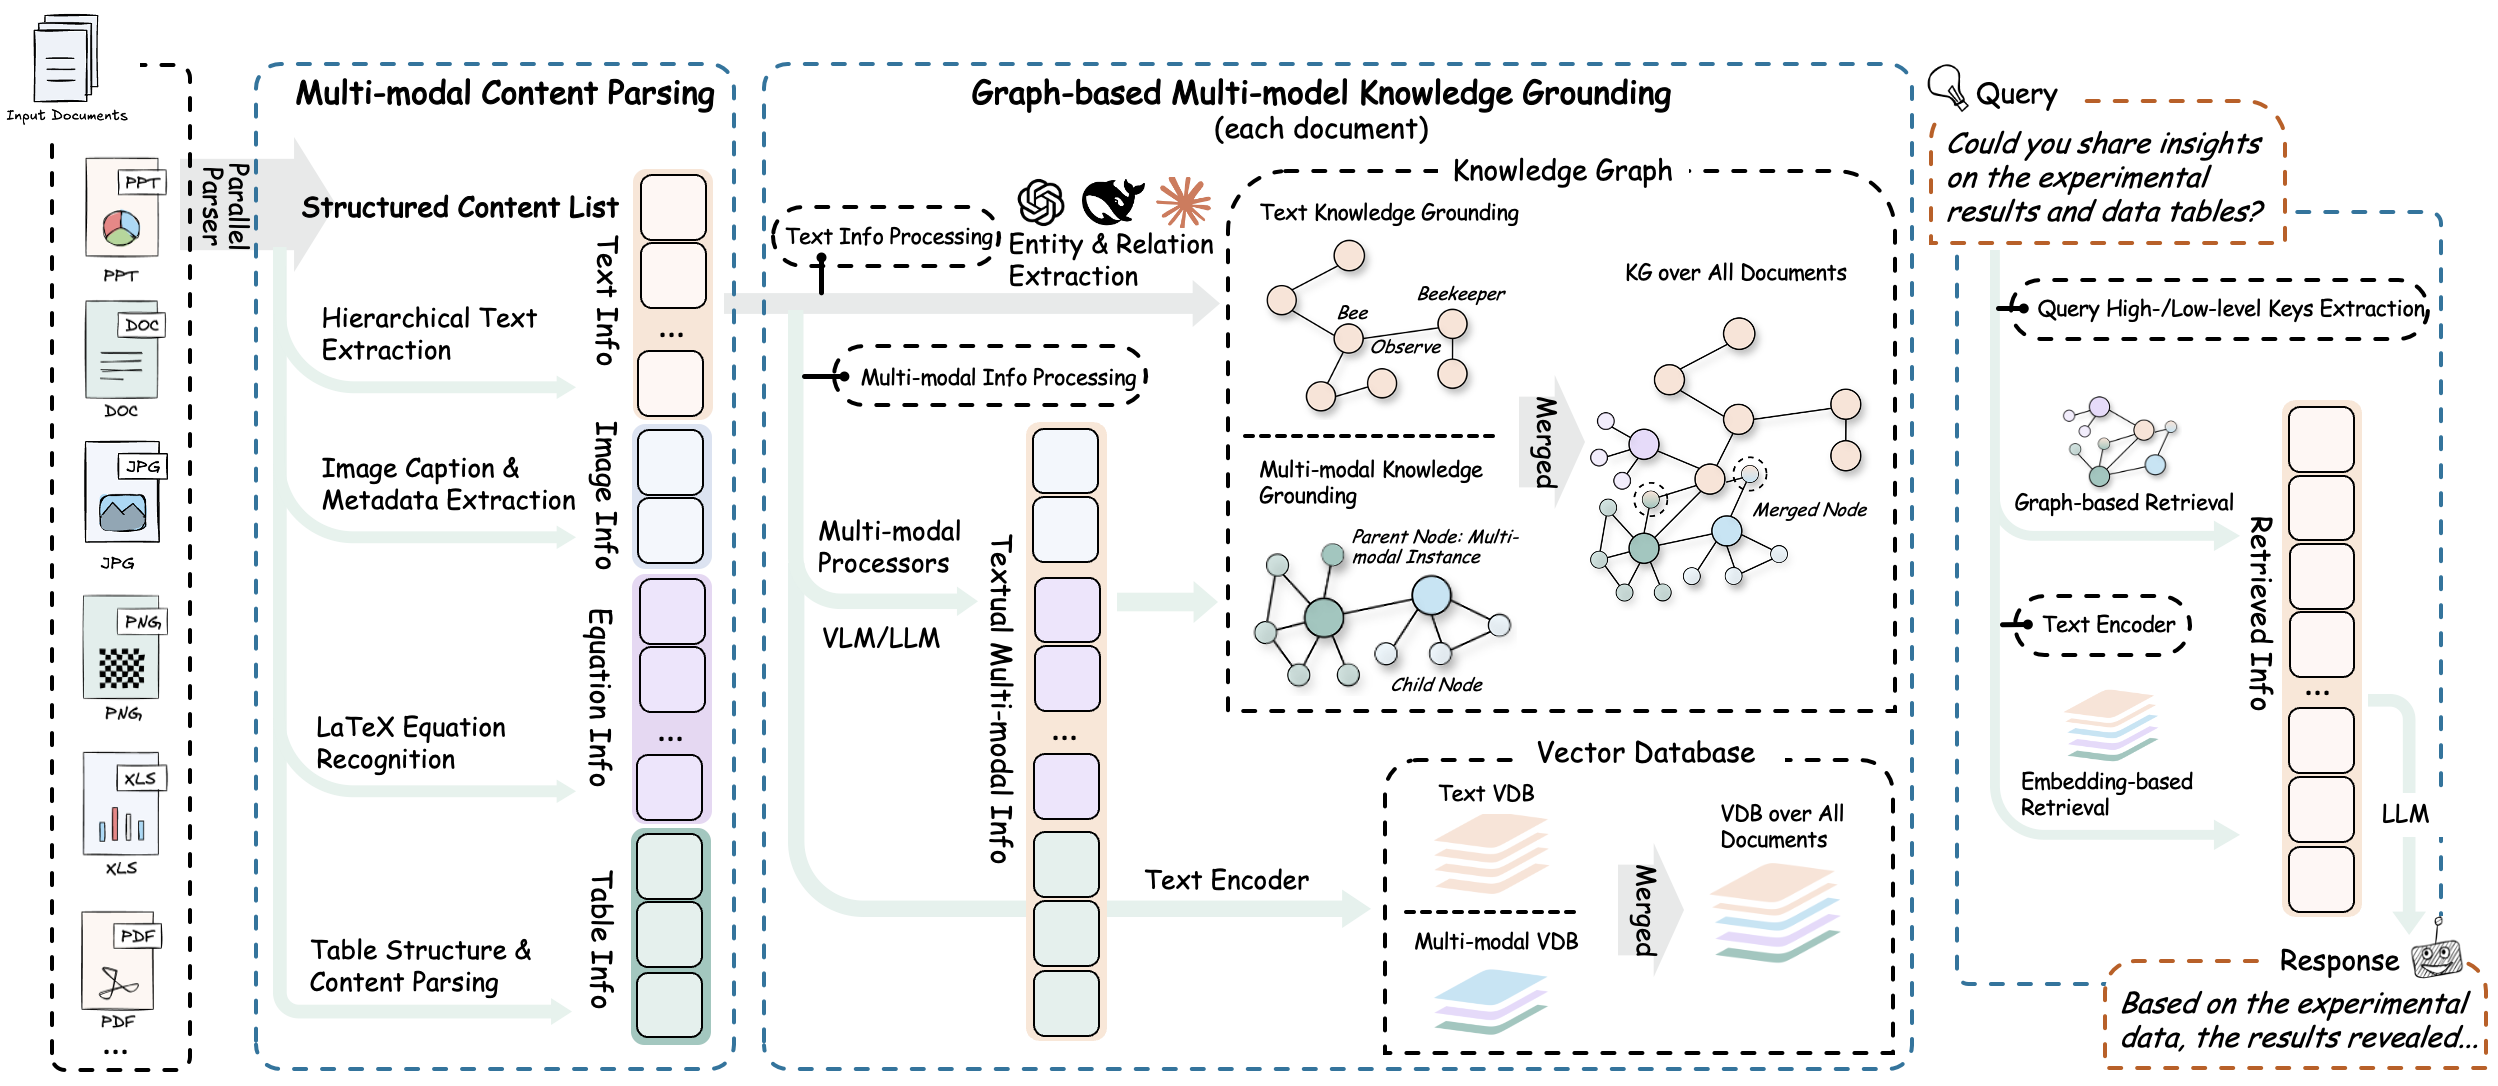
Modern documents increasingly contain diverse multimodal content—text, images, tables, equations, charts, and multimedia—that traditional text-focused RAG systems cannot effectively process. **RAG-Anything** addresses this challenge as a comprehensive **All-in-One Multimodal Document Processing RAG system** built on [LightRAG](https://github.com/HKUDS/LightRAG).
As a unified solution, RAG-Anything **eliminates the need for multiple specialized tools**. It provides **seamless processing and querying across all content modalities** within a single integrated framework. Unlike conventional RAG approaches that struggle with non-textual elements, our all-in-one system delivers **comprehensive multimodal retrieval capabilities**.
Users can query documents containing **interleaved text**, **visual diagrams**, **structured tables**, and **mathematical formulations** through **one cohesive interface**. This consolidated approach makes RAG-Anything particularly valuable for academic research, technical documentation, financial reports, and enterprise knowledge management where rich, mixed-content documents demand a **unified processing framework**.
🎯 Key Features
- **🔄 End-to-End Multimodal Pipeline** - Complete workflow from document ingestion and parsing to intelligent multimodal query answering
- **📄 Universal Document Support** - Seamless processing of PDFs, Office documents, images, and diverse file formats
- **🧠 Specialized Content Analysis** - Dedicated processors for images, tables, mathematical equations, and heterogeneous content types
- **🔗 Multimodal Knowledge Graph** - Automatic entity extraction and cross-modal relationship discovery for enhanced understanding
- **⚡ Adaptive Processing Modes** - Flexible MinerU-based parsing or direct multimodal content injection workflows
- **📋 Direct Content List Insertion** - Bypass document parsing by directly inserting pre-parsed content lists from external sources
- **🎯 Hybrid Intelligent Retrieval** - Advanced search capabilities spanning textual and multimodal content with contextual understanding
🏗️ Algorithm & Architecture
### Core Algorithm
**RAG-Anything** implements an effective **multi-stage multimodal pipeline** that fundamentally extends traditional RAG architectures to seamlessly handle diverse content modalities through intelligent orchestration and cross-modal understanding.
📄
Document Parsing
→
🧠
Content Analysis
→
🔍
Knowledge Graph
→
🎯
Intelligent Retrieval
1. Document Parsing Stage
The system provides high-fidelity document extraction through adaptive content decomposition. It intelligently segments heterogeneous elements while preserving contextual relationships. Universal format compatibility is achieved via specialized optimized parsers.
**Key Components:**
- **⚙️ MinerU Integration**: Leverages [MinerU](https://github.com/opendatalab/MinerU) for high-fidelity document structure extraction and semantic preservation across complex layouts.
- **🧩 Adaptive Content Decomposition**: Automatically segments documents into coherent text blocks, visual elements, structured tables, mathematical equations, and specialized content types while preserving contextual relationships.
- **📁 Universal Format Support**: Provides comprehensive handling of PDFs, Office documents (DOC/DOCX/PPT/PPTX/XLS/XLSX), images, and emerging formats through specialized parsers with format-specific optimization.
2. Multi-Modal Content Understanding & Processing
The system automatically categorizes and routes content through optimized channels. It uses concurrent pipelines for parallel text and multimodal processing. Document hierarchy and relationships are preserved during transformation.
**
📈 近 7 天 Star 趋势
每日新增 Star(柱)与累计 Star(线)· 数据来自 GitHub
🏆 排名变化趋势
在各榜单中的排名历史(数字越小越靠前)
📋 历史上榜记录
每次快照的详细数据
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|