📄 仓库 README
在 GitHub 查看 ↗
I implemented a transformer model from scratch using PyTorch, based on the paper Attention is All You Need. You can use my scripts to train your own billion or million parameter LLM using a single GPU, or a small one on a laptop CPU with no GPU at all.
This started as a pretraining tutorial. It now goes all the way from raw text to an aligned, reasoning style model, with every algorithm hand written in plain PyTorch (no trl, no peft, no transformers). The whole journey is one idea repeated: turn text into numbers, predict the next token, then keep changing the data and the loss until the model does what we want.
Next to the original model there is now a modern one, built the way current open models are (rotary positions, RMSNorm, SwiGLU, grouped-query and latent attention, Mixture of Experts, a KV cache), and every stage can train either. The newer training tricks are here too, each written out by hand: the Muon optimizer, LoRA, IPO and SimPO, Dr. GRPO, DAPO and GSPO, speculative decoding and int8 weights.
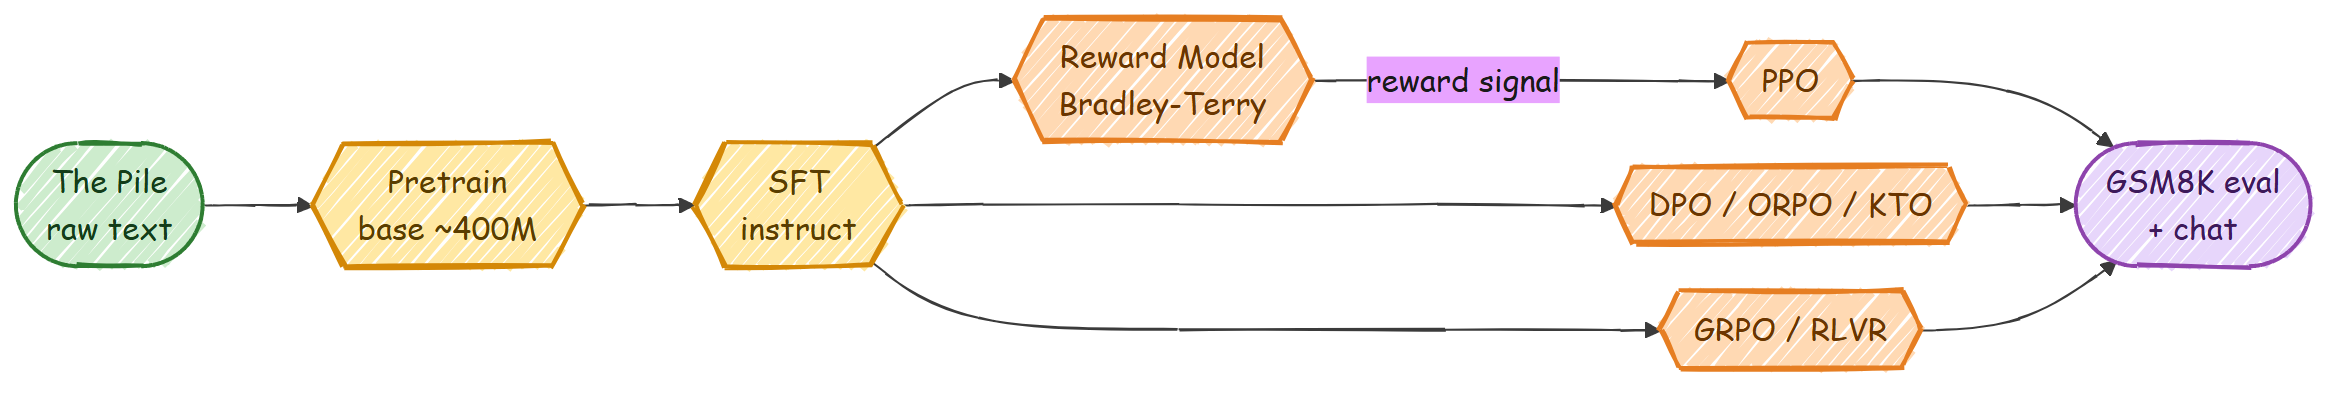
Here is the path we will walk, end to end:
raw text  ->  tokens  ->  a Transformer  ->  next-token loss  ->  a base model
base model  ->  SFT  ->  Reward Model  ->  {PPO, DPO}  ->  GRPO  ->  evaluation and chat
Below is the output of a trained 13 million parameter LLM, just so you can see where the small end of this starts:
In ***1978, The park was returned to the factory-plate that
the public share to the lower of the electronic fence that
follow from the Station's cities. The Canal of ancient Western
nations were confined to the city spot. The villages were directly
linked to cities in China that revolt that the US budget and in
Odambinais is uncertain and fortune established in rural areas.
Table of Contents
- Who this is for
- Prerequisites and Training Time
- Setup
- No GPU? Train on Your Laptop
- Code Structure
- Step 1: Preparing the Data
- Step 2: The Model, Built From Small Pieces
- Multi Layer Perceptron (MLP)
- Single Head Attention
- Multi Head Attention
- The Transformer Block
- The Full Transformer
- The Modern Version of the Same Model
- Step 3: Pretraining the Base Model
- Step 4: Generating Text
- Step 5: Post-Training, Turning a Base Model Into an Assistant
- SFT (Supervised Fine-Tuning)
- The Reward Model
- DPO, ORPO and KTO
- PPO
- GRPO / RLVR
- Step 6: Evaluation
- Step 7: Talking to the Model
- The Streamlit Control Panel
- The Documentation Site
- Run the Whole Thing
- Type Safety and Tests
- What's Next
Who this is for
I tried to write this so one page works for very different readers:
- If you are a student, read top to bottom. Every block of code comes after a plain explanation of what it does and why, and most blocks are followed by the output you should expect.
- If you are a developer, the commands and file paths are all here. You can copy, run, and read the referenced source files directly.
- If you are a researcher, the post-training half is the interesting part: SFT, a Bradley-Terry reward model, PPO with GAE, DPO/ORPO/KTO, and GRPO, all from scratch on the same small Transformer, trained on real public datasets.
Every diagram in this README is colored the same way, so the colors mean something:
- green is raw data
- teal is stored, tokenized data on disk
- blue is a plain processing step
- yellow is the model or a training step
- orange is the reinforcement learning and reward parts
- red is a loss
- grey is a saved checkpoint
- purple is the final output or evaluation
Prerequisites and Training Time
You need a basic understanding of object oriented programming, neural networks, and PyTorch. Below are some resources to help you get started:
| Topic | Video Link |
|---|---|
| OOP | OOP Video |
| Neural Network | Neural Network Video |
| Pytorch | Pytorch Video |
You do not need a GPU to start: the laptop track trains a small model on a CPU in minutes. For the bigger models you will need a GPU. A free Colab or Kaggle T4 is enough for the 13 million parameter model, but it will not fit a billion parameter model. Here is a rough guide:
| GPU Name | Memory | 2B LLM Training | 13M LLM Training | Max Practical LLM Size (Training) |
|---|---|---|---|---|
| NVIDIA A100 | 40 GB | ✔ | ✔ | ~6B to 8B |
| NVIDIA V100 | 16 GB | ✘ | ✔ | ~2B |
| NVIDIA RTX 4090 | 24 GB | ✔ | ✔ | ~4B |
| NVIDIA RTX 5090 | 32 GB | ✔ | ✔ | 13M verified, larger configs TBD |
| NVIDIA RTX 3090 | 24 GB | ✔ | ✔ | ~3.5B to 4B |
| NVIDIA RTX 4080 | 16 GB | ✘ | ✔ | ~2B |
| NVIDIA RTX 4060 | 8 GB | ✘ | ✔ | ~1B |
| Tesla T4 | 16 GB | ✘ | ✔ | ~1.5B to 2B |
If a large config runs out of memory, the pretraining script has opt-in flags (--amp, --grad-checkpointing, --grad-accum) that bring the memory down a lot. More on those later.
Setup
Clone the repository and install it in editable mode. The editable install puts config, src, data_loader, and ui on your import path, so you do not need to set PYTHONPATH by hand anymore:
git clone https://github.com/FareedKhan-dev/train-llm-from-scratch.git
cd train-llm-from-scratch
pip install -e .
If you use uv, uv sync does the same and also installs the test tools. On a Linux machine without an NVIDIA GPU, install the small CPU build of PyTorch first (pip install torch --index-url https://download.pytorch.org/whl/cpu), because the default Linux wheel bundles CUDA.
There are optional extras for the parts you want:
pip install -e ".[train]"   # datasets + wandb, for downloading data and logging
pip install -e ".[ui]"      # streamlit + pandas + altair, for the control panel
pip install -e ".[docs]"    # mkdocs, for the documentation site
pip install -e ".[all]"     # everything
There are two config systems, and it helps to know which is which from the start:
config/config.pyis the original, simple config for the legacy pretraining scriptscripts/train_transformer.py. It is plain Python constants.config/post_training_config.pyplus the JSON files inconfigs/drive everything else (pretraining the bigger base, SFT, reward, DPO, PPO, GRPO). You edit a small JSON file per stage, and any field can also be overridden on the command line, for example--lr 2e-5 --batch_size 16.
For fast checks there is a tiny configs/smoke/ variant of every stage that shrinks the model so a full run finishes in seconds on a CPU or a single GPU.
No GPU? Train on Your Laptop
You can train a real (small) language model on a laptop CPU, from raw text to generated stories, in about ten minutes. Three commands:
python scripts/prepare_tiny_data.py                              # TinyStories + a BPE tokenizer trained from scratch
python scripts/train_transformer.py --preset tiny --arch modern  # 369K parameters, about 5 minutes on a CPU
python scripts/generate_text.py --model_path models/tiny.pt      # write a story
The first command downloads 25 MB of TinyStories (short stories written for training tiny models) and trains a 4,096 token BPE tokenizer on it, written from scratch in src/tokenizer/bpe.py. A small vocabulary keeps the embedding table small, which is what makes a tiny model fast. Here is what the tiny model wrote after five minutes of training on my laptop:
#### OUTPUT ####
Once upon a time, there was a little girl named Lily. She liked to eat some food together.
One day, Lily found a big box in a box. She wanted to pick it up and find it. She thought it
would make it happy. She looked at her bear and said, "Yes, I will find me. I want to help you get it."
Real words, real sentences, a character and a plot of sorts, from 369 thousand parameters. Bigger presets (student, small) take longer and write better stories. scripts/benchmark.py measures how fast each preset trains on your machine before you commit to a long run, and scripts/model_report.py tells you how big a model is, how much compute it needs, and whether it fits in memory.
The full guide, with the presets, the expected losses and experiments to try, is in [docs/student](https://github.com/FareedKhan-dev/train-llm-from-scratch/blob/HEAD/docs/student
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|