📄 仓库 README
在 GitHub 查看 ↗
| Documentation | Quickstart | Supported models | Rust SDK | Python SDK | Discord |

Latest
- LFM3 and LFM3-VL: native support for
LiquidAI/LFM3-1.7BandLiquidAI/LFM3-VL-2B, including text, image, and video inference, GGUF loading, ISQ, paged attention, and chunked prefill. Model notes - v0.9.5: paged attention is now the default on supported Metal models, with automatic memory planning across the CLI and SDKs. Existing memory and device-mapping options have changed; see the upgrade guide. This release also adds Qwen3.8-Flash-Next and CUDA 13.4 source builds.
- Muse Glimmer 30B: native text, image, and video inference with ATEM tool calling, reasoning controls, LoRA, ISQ/UQFF, and companion-projector GGUF loading. Model notes
- GGUF loading: load a local file with
-f, or select a published artifact with--quant. Tokenizer, configuration, and multimodal projector files are discovered when the available metadata identifies them unambiguously. Guide - OpenAI-compatible Skills: upload
/v1/skillsbundles and reference them from Responses requests for reusable procedures, helper scripts, and local data. Guide - OpenAI-compatible file inputs: upload
/v1/files, attach Responsesinput_fileor Chatfileparts, and mount request files into shell/code sessions. Guide - DiffusionGemma: block-diffusion text generation. Fully integrated: paged attention, prefix caching, ISQ, multimodal, and tool calling. Guide
- Anthropic Messages API:
mistralrs servenow exposes Anthropic-compatible/v1/messagesand/v1/messages/count_tokensendpoints alongside the OpenAI-compatible/v1API. Guide - v0.8.2 CUDA performance: paged-attention and MoE optimizations deliver strong results on GB10, B200, and H100 SXM. Benchmarks
- Agentic runtime: web search, local Python code execution, shell execution, OpenAI-compatible Skills, session management, and custom tool hooks. Guide
- Gemma 4: full multimodal: text, image, video, and audio input. Supported models | Video setup
Benchmarks
v0.8.2 CUDA benchmarks
Mean tokens per second across prompt lengths and decode depths from 128 to 16384 tokens. Decode uses 256 generated tokens. See the full [v0.8.2 report](https://github.com/EricLBuehler/mistral.rs/blob/HEAD/releases/v0.8.2/report.md) for commands, model revisions, host metadata, and appendix tables. **Q8 prefill TPS: mistral.rs UQFF q8 vs llama.cpp GGUF Q8_0** | Model | Hardware | mistral.rs | llama.cpp | |---|---|---:|---:| | Gemma 4 E4B | GB10 | 7395.7 | 3973.7 | | Gemma 4 E4B | B200 | 27705.6 | 11992.4 | | Gemma 4 E4B | H100 SXM | 26220.6 | 11702.1 | | Gemma 4 26B-A4B | GB10 | 2947.0 | 2178.5 | | Gemma 4 26B-A4B | B200 | 12725.3 | 8503.4 | | Gemma 4 26B-A4B | H100 SXM | 12362.3 | 8055.1 | **Q8 decode TPS: mistral.rs UQFF q8 vs llama.cpp GGUF Q8_0** | Model | Hardware | mistral.rs | llama.cpp | |---|---|---:|---:| | Gemma 4 E4B | GB10 | 44.1 | 40.5 | | Gemma 4 E4B | B200 | 241.4 | 194.4 | | Gemma 4 E4B | H100 SXM | 223.1 | 183.0 | | Gemma 4 26B-A4B | GB10 | 46.8 | 46.4 | | Gemma 4 26B-A4B | B200 | 210.9 | 192.2 | | Gemma 4 26B-A4B | H100 SXM | 199.8 | 183.9 | **BF16 prefill TPS: mistral.rs BF16 vs vLLM BF16** | Model | Hardware | mistral.rs | vLLM | |---|---|---:|---:| | Gemma 4 E4B | GB10 | 5838.9 | 5812.9 | | Gemma 4 E4B | B200 | 43547.8 | 39431.2 | | Gemma 4 E4B | H100 SXM | 35852.2 | 39293.7 | | Gemma 4 26B-A4B | GB10 | 592.2 | 3878.6 | | Gemma 4 26B-A4B | B200 | 3467.3 | 28532.8 | | Gemma 4 26B-A4B | H100 SXM | 2766.0 | 26295.9 | **BF16 decode TPS: mistral.rs BF16 vs vLLM BF16** | Model | Hardware | mistral.rs | vLLM | |---|---|---:|---:| | Gemma 4 E4B | GB10 | 25.1 | 18.8 | | Gemma 4 E4B | B200 | 202.6 | 196.2 | | Gemma 4 E4B | H100 SXM | 174.4 | 153.0 | | Gemma 4 26B-A4B | GB10 | 26.9 | 23.2 | | Gemma 4 26B-A4B | B200 | 159.6 | 220.2 | | Gemma 4 26B-A4B | H100 SXM | 138.7 | 148.0 |Why mistral.rs?
- Automatic model loading: Architecture, weight format, and chat template are detected for supported Hugging Face models and GGUF files, with flags available for explicit selection.
- True multimodality: Text, vision, video, and audio, speech generation, image generation, and embeddings in one engine.
- Quantization selection:
--quantselects a matching artifact from GGUF repositories. For other Hugging Face repositories, it uses a prebuilt UQFF when available and otherwise applies ISQ. Docs - OpenAI + Anthropic compatible serving: The same
mistralrs serveprocess exposes OpenAI-compatible/v1endpoints and Anthropic-compatible Messages endpoints. - Prometheus metrics:
mistralrs serveexposes a/metricsendpoint in Prometheus format, recording per-request counts and latency labeled by method, route, and status. Docs - Built-in web UI: Served at
/uiby default. Shows reasoning, code execution, plots, and files inline. Edit any message and the new branch runs with its own Python state. Pass--no-uito disable. - Hardware-aware:
mistralrs tunerecommends quantization and device mapping from the model config and your detected hardware. - Flexible SDKs: Python package and Rust crate to build your projects.
- Native agentic support: built-in agentic loop with web search, local Python code execution, shell execution, OpenAI-compatible Skills, session management, and custom tool hooks.
Quick Start
Install
Run the command for your platform in a terminal, then follow the installer.
macOS / Linux:
curl -fsSL https://mistralrs.dev/install.sh | sh
Windows (PowerShell):
irm https://mistralrs.dev/install.ps1 | iex
When installation finishes, open a new terminal.
Chat in Your Browser
Start a model:
mistralrs serve -m Qwen/Qwen3-4B --quant 4
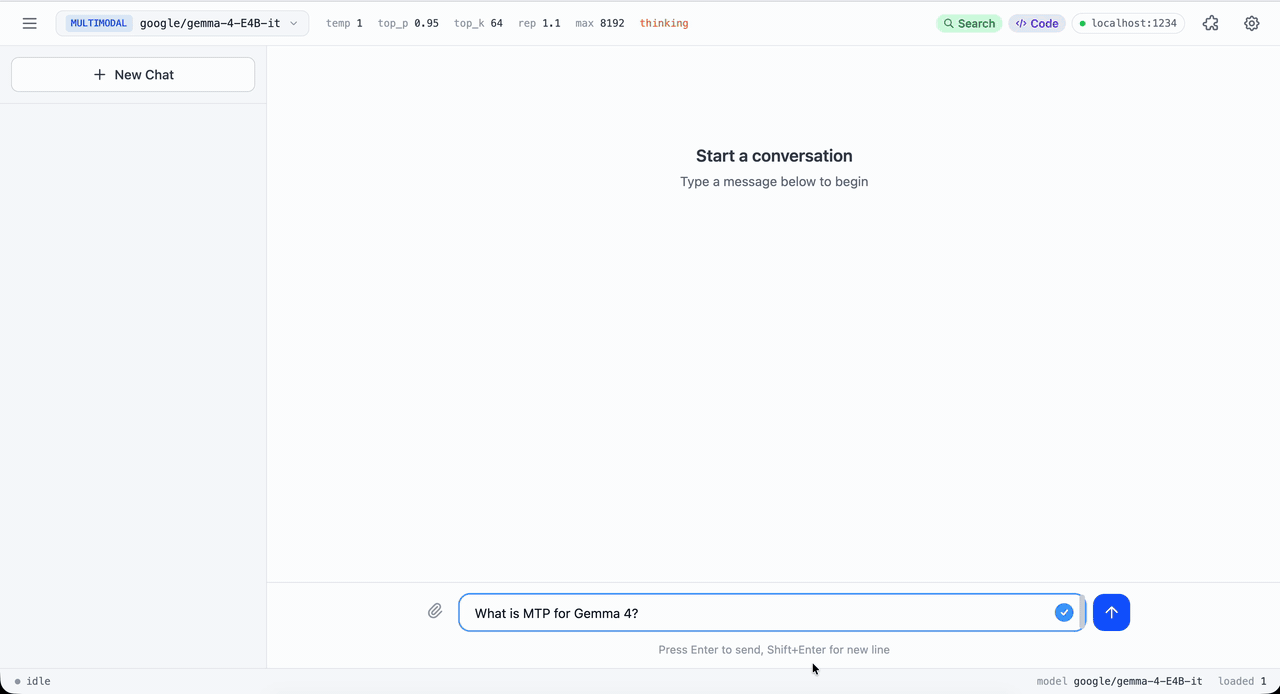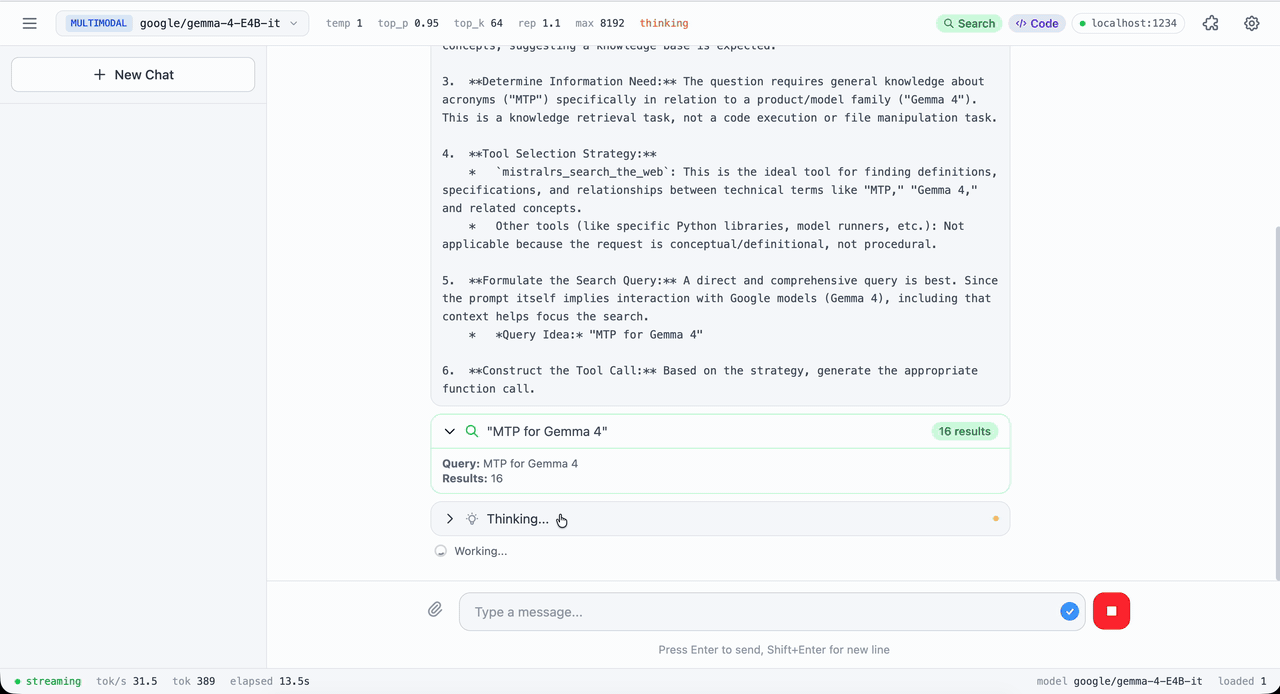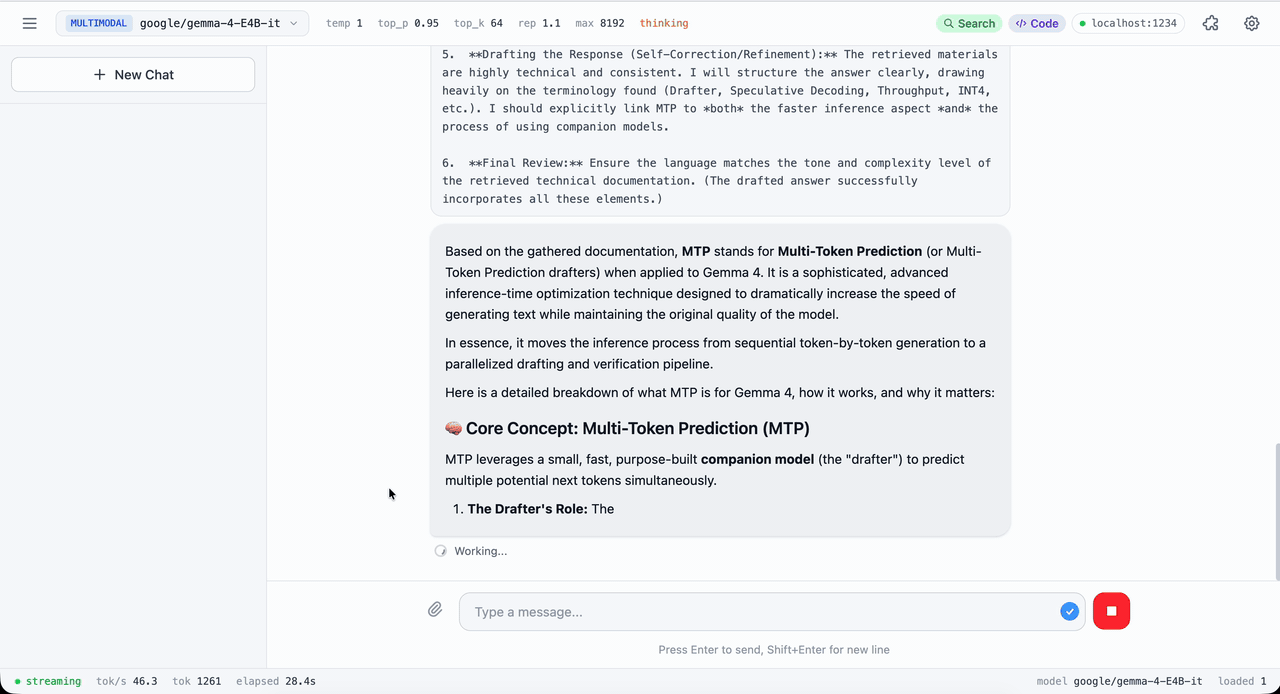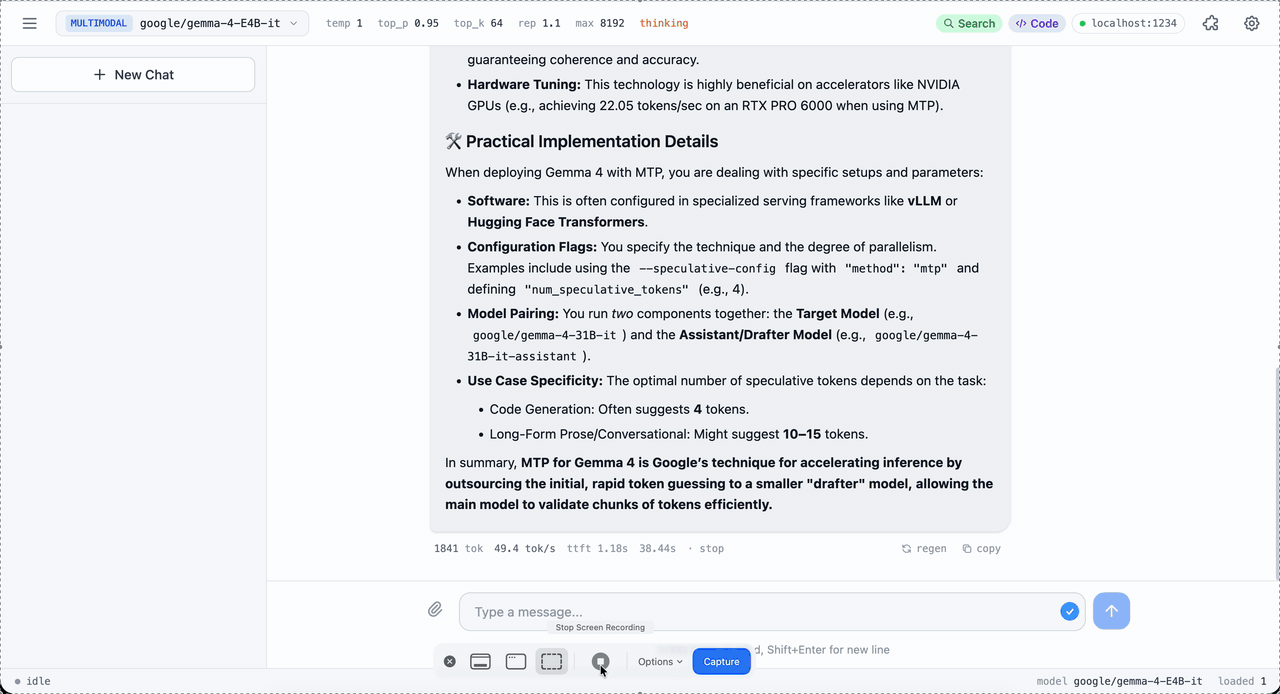
When the server is ready, open http://localhost:1234/ui and send a message. Keep the terminal open while chatting; press Ctrl+C to stop.
Quickstart | Installer options
UI Demo
What Makes It Fast
Performance - Continuous batching support by default on all devices. - CUDA with FlashAttention V2/V3, Metal, and multi-GPU/distributed inference - PagedAttention for high throughput continuous batching on CUDA or Apple Silicon, prefix caching (including multimodal)
Quantization (full docs) - In-situ quantization (ISQ) for Hugging Face models - GGUF (2-8 bit), GPTQ, AWQ, HQQ, FP8, BNB support - ⭐ Per-layer topology: Fine-tune quantization per layer for optimal quality/speed - ⭐ Auto-select fastest quant method for your hardware
Flexibility - LoRA & X-LoRA with per-request LoRA selection and X-LoRA adapter mixing - AnyMoE: Create mixture-of-experts on any base model - Multiple models: Load/unload at runtime
Agentic Features
- Integrated tool calling with grammar enforcement and strict schema mode
- ⭐ Server-side agentic loop: auto-execute tools and feed results back
- ⭐ Python code execution: persistent Jupyter-like sessions with matplotlib capture and multimodal feedback
- ⭐ Shell execution: persistent command-line sessions with sandboxing and approval controls
- ⭐ OpenAI-compatible Skills: uploaded skill bundles for Responses API agents
- ⭐ OpenAI-compatible file inputs: /v1/files, Responses input_file, Chat file, and workdir mounts
- ⭐ Web search integration with embedding-based ranking
- ⭐ Tool dispatch URL: POST tool calls to your own endpoint
- ⭐ MCP client: Connect to external tools via Process, HTTP, or WebSocket
- Python/Rust tool callbacks for custom execution
Supported Models
Text, multimodal, speech, image generation, and embedding models across 45+ architectures. The supported models reference is the single source of truth: it explains how to check whether your model's config.json is supported, lists every architecture with copy-paste run commands, and is generated directly from the engine's loader registry so it never drifts.
Supported models reference | Request a new model
Python SDK
pip install mistralrs
In-process inference from Python: load a model with Runner and send OpenAI-shaped requests, no server required. Accelerator-specific wheels (CUDA, Metal, MKL, Accelerate) are listed in the getting-started guide.
Get started | API reference | Examples
Rust SDK
cargo add mistralrs
Embed the engine in a Rust application with the high-level mistralrs crate.
Get started | docs.rs | Crate | Examples
Docker
Prebuilt CPU and CUDA images are published to GHCR. Pull commands, tags, and Kubernetes notes are in the Docker guide.
Documentation
For complete documentation, see the Documentation.
Quick Links: - Quickstart - Install, first run, first serve - CLI Reference - All commands and options - Anthropic Messages API - Anthropic-compatible Messages, streaming, tool use, and token counting - HTTP API - OpenAI-compatible and Anthropic-compatible endpoints - Quantization - ISQ, GGUF, GPTQ, and more - Multi-GPU and Distributed - NCCL TP, P2P layer mapping, multi-node, and ring - MCP Integration - MCP integration documentation - Troubleshooting - Common issues and solutions - Environment variables - Environment variables for configuration
Citation
If you use mistral.rs in your research, please cite:
@misc{mistralrs,
  author = {Buehler, Eric},
  title = {{mistral.rs}: Fast, flexible {LLM} inference},
  year = {2024},
  url = {https://github.com/EricLBuehler/mistral.rs}
}
Citation metadata is available in CITATION.cff.
Contributing
Contributions welcome! Please open an issue to discuss new features or report bugs. If you want to add a new model, please contact us via an issue and we can coordinate.
Credits
This project would not be possible without the excellent work at Candle. Thank you to all contributors!
mistral.rs is not affiliated with Mistral AI.
📈 近 7 天 Star 趋势
🏆 排名变化趋势
📋 历史上榜记录
| 日期 | 榜单 | 排名 | 周期新增 | 总 STAR |
|---|